Real-Time Event Delivery And WebSockets
Asked of: Software Engineer
Last updated
What's being tested
This topic tests whether you can design a reliable, scalable real-time delivery system rather than merely open a socket and push bytes. The interviewer is probing your understanding of connection lifecycle, event ordering, reconnect behavior, delivery guarantees, backpressure, fanout, and horizontal scaling. Stripe cares because payment state changes must reach dashboards, merchants, and internal tools promptly without exposing customers to duplicated, missing, unauthorized, or misleading events.
Core knowledge
-
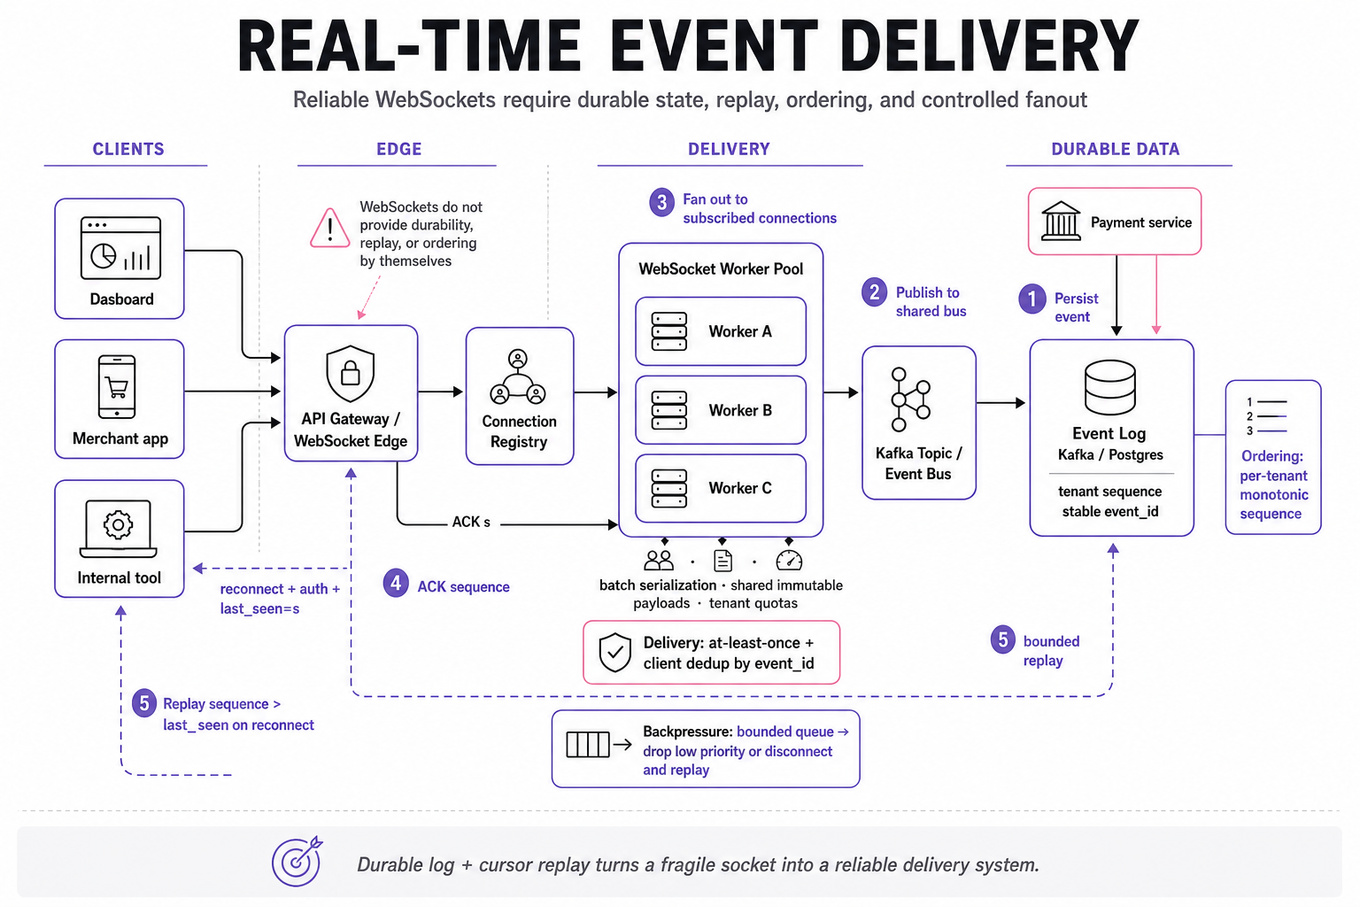
WebSockets provide a long-lived, bidirectional connection after an HTTP upgrade, but they do not provide durable delivery, replay, ordering across producers, or automatic recovery. The application must define those semantics explicitly.
-
Separate the durable event log from the connection-serving layer. Persist events in systems such as
`Kafka`,`Postgres`, or an event store, then use WebSocket workers to deliver them; a process crash must not erase undelivered state. -
Use a per-stream or per-tenant monotonic sequence number. Clients can acknowledge sequence
s, reconnect withlast_seen=s, and request events wheresequence > s; globally ordered delivery is usually unnecessary and expensive. -
Choose delivery semantics deliberately: at-most-once minimizes duplicates but can lose events, while at-least-once permits retries and duplicates. Exactly-once presentation generally requires client-side deduplication using stable event IDs.
-
Design reconnect as a normal path, not an exception. The client should use exponential backoff with jitter, authenticate again when needed, send its last acknowledged cursor, and perform a bounded replay before resuming live delivery.
-
A connection registry maps a logical subscription to active connection workers. In a multi-instance deployment, route events through shared infrastructure such as
`Kafka`pub/sub, Redis Streams, or a broker; never assume an in-memory registry is globally complete. -
Control fanout explicitly. A high-volume event may target many subscribers, so batch serialization, share immutable payloads, coalesce replaceable updates, and apply per-tenant quotas rather than creating unbounded work per recipient.
-
Implement backpressure with bounded per-connection queues and explicit overflow behavior. Slow clients can be disconnected and forced to replay, or lower-priority updates can be dropped; unbounded buffers eventually exhaust memory.
-
Define ordering at the narrowest useful scope: per account, resource, or subscription. Partitioning by that key preserves order while allowing parallelism; asynchronous handlers, retries, and multiple producers can otherwise reorder events.
-
Use heartbeats to detect half-open TCP connections. A ping/pong interval must be shorter than infrastructure idle timeouts, while server-side write deadlines and connection limits prevent dead peers from consuming resources indefinitely.
-
Treat authorization as a subscription-time and event-time concern. Validate the tenant, resource scope, and token claims when subscribing; avoid trusting client-provided channel names, and re-check revocation or permission changes for long-lived sessions.
-
Make events versioned and self-describing: include event ID, type, schema version, resource identifier, sequence, creation time, and tenant context. Consumers should tolerate additive fields and reject or quarantine incompatible versions safely.
Worked example
No interview title was supplied, so consider the representative prompt: “Design a real-time event delivery service using WebSockets.” In the first 30 seconds, clarify event volume, concurrent connections, required latency, tenant isolation, replay duration, ordering scope, and whether missing events are acceptable. State an assumption such as 500,000 concurrent connections, at-least-once delivery, per-account ordering, and a seven-day replay window. Organize the answer around four pillars: durable event production, subscription and authorization, horizontally scalable connection workers, and reconnect/replay semantics. Explain that clients receive an event ID and sequence number, acknowledge a cursor, and resume from that cursor after reconnecting. Explicitly flag the tradeoff between storing a durable per-client cursor and making clients replay from their own last acknowledged cursor; the latter is simpler but may increase duplicate delivery. Close by saying that, with more time, you would quantify queue memory, test broker lag and regional failure behavior, and define operational `p99` latency and drop-rate alerts.
A second angle
A related prompt might focus on delivering payment-status updates to a browser that can disappear and reconnect frequently. The framing shifts from maximum fanout toward correctness of replay, authorization, and stale-state handling. You should distinguish transient UI updates from durable state transitions: a client may skip intermediate progress events but must be able to fetch the current payment state. This naturally leads to snapshot-plus-delta delivery, where the server sends a current resource version followed by newer events.
Common pitfalls
Pitfall: Saying “WebSockets guarantee reliable delivery” is incorrect; TCP only provides ordered bytes while the connection exists. Explain persistence, acknowledgments, replay, and deduplication at the application layer.
Pitfall: Jumping directly to
`Kafka`partitions and Redis nodes without first stating delivery, ordering, replay, and scale assumptions makes the design feel accidental. Establish guarantees and workload numbers before naming infrastructure.
Pitfall: Claiming exactly-once delivery as a simple feature is a depth mistake. A stronger answer distinguishes broker delivery from user-visible effects and uses idempotent event IDs, cursors, and client or consumer deduplication.
Connections
An interviewer may pivot to long polling and Server-Sent Events for transport tradeoffs, or to idempotency, event sourcing, and consumer backpressure for correctness. They may also explore multi-region routing, graceful deployment of connection workers, and observability through connection count, broker lag, replay rate, and `p99` delivery latency.
Further reading
-
RFC 6455: The WebSocket Protocol — protocol-level handshake, framing, control frames, and closing behavior.
-
Designing Data-Intensive Applications by Martin Kleppmann — durable logs, stream processing, ordering, and delivery semantics.
-
The Tail at Scale — why tail latency and stragglers matter in distributed request and fanout systems.