Recommendation And Ranking Systems
Asked of: Machine Learning Engineer
Last updated
What's being tested
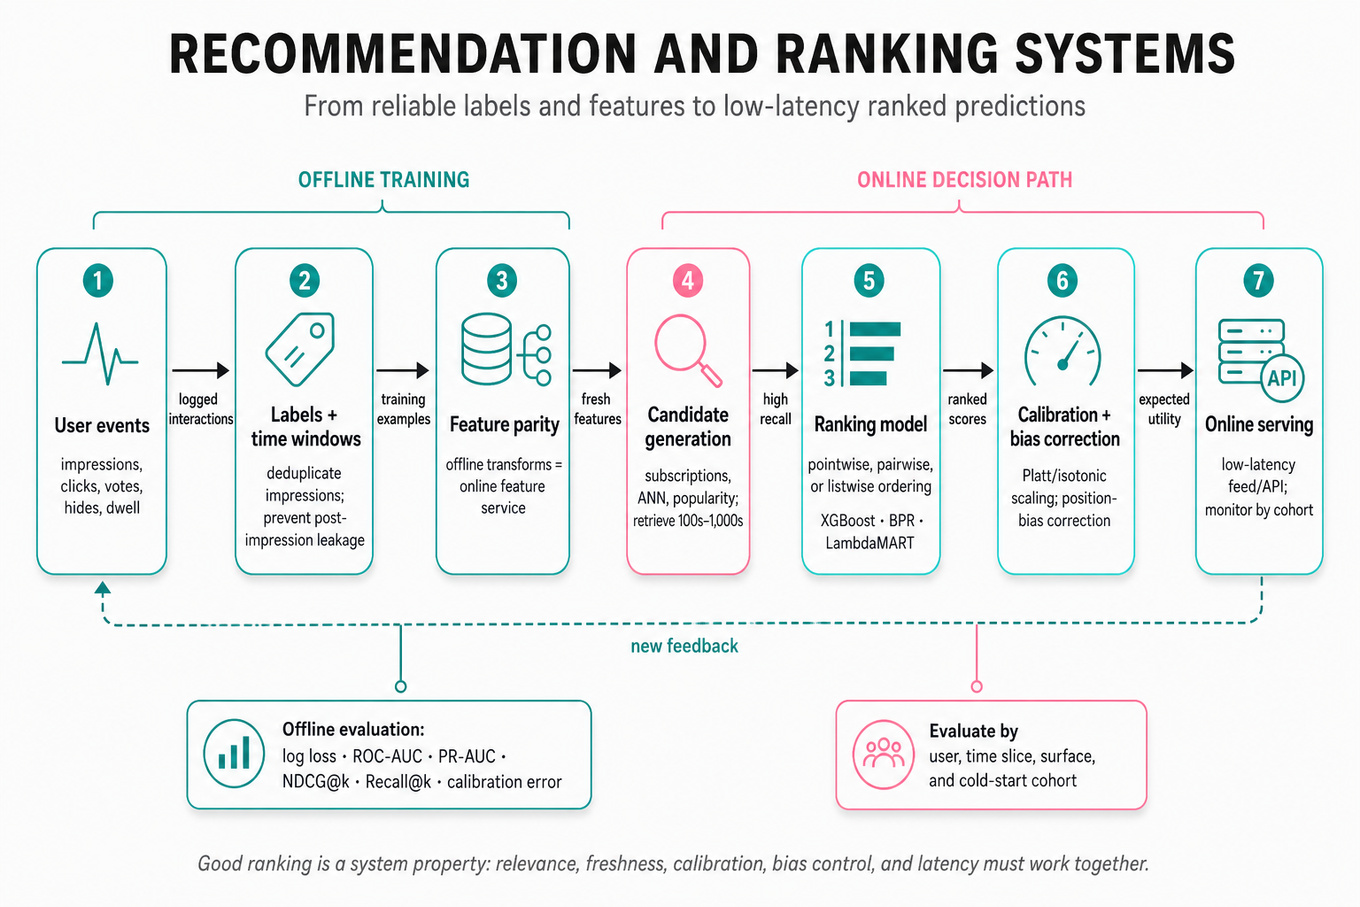
These systems test whether you can connect recommendation modeling with reliable training, feature, evaluation, and serving infrastructure. You should be able to define prediction targets precisely, choose models and metrics appropriate to ranking, and explain how offline artifacts become low-latency online predictions. Reddit cares because ranking quality depends not only on model accuracy, but also on feature freshness, calibration, position-bias correction, cold-start behavior, and safe deployment at high traffic.
Core knowledge
-
Candidate generation and ranking are separate stages: retrieve hundreds or thousands of candidates using subscriptions, approximate nearest neighbors, or popularity, then apply a richer ranker to meet latency budgets. Retrieval optimizes recall; ranking optimizes ordering quality.
-
Label definition must match the product decision and prediction horizon. For click prediction, define when a user clicks within a fixed window, deduplicate impressions, and prevent post-impression features from entering training. Comments, votes, dwell, hides, and reports may be separate labels.
-
Pointwise, pairwise, and listwise learning-to-rank make different assumptions. Logistic regression or
XGBoostwith binary cross-entropy predicts individual outcomes; pairwise losses such as Bayesian Personalized Ranking optimize relative order;LambdaMARTor listwise losses directly optimize ranking positions. -
Offline metrics should include
log loss,ROC-AUC,PR-AUC, calibration error, and ranking metrics such asNDCG@k,MRR, orRecall@k. A model can improve AUC while worsening top-of-feed quality, so evaluate by user, time slice, surface, and cold-start cohort. -
Calibration matters when scores are combined across models or converted into expected utility. For predicted probability , log loss is ; use Platt scaling or isotonic regression on a temporally held-out set when necessary.
-
Position bias means observed clicks reflect both relevance and examination probability: . Randomized swaps, inverse-propensity weighting, or click models estimate and reduce this confounding.
-
Feature parity requires the training pipeline and online feature service to compute identical semantics, transformations, defaults, and time cutoffs. A feature store such as
Feastcan manage materialization, but validation must still detect training-serving skew, stale values, missing entities, and inconsistent categorical vocabularies. -
Online serving commonly uses a low-latency feature lookup, model server, and fallback path behind an API. Cache stable item features, keep user/session features fresh, publish versioned models, enforce
p99latency budgets, and fall back to a prior model or deterministic ranking when dependencies fail. -
Embeddings represent users, communities, posts, authors, or categorical IDs in dense vectors. For high-cardinality IDs, use hashing, frequency thresholds, shared embeddings, or partitioned tables; bound memory and support versioned vocabulary changes rather than allowing unbounded embedding growth.
-
Cold start requires content and metadata features available before interactions: text or multimodal encoders, subreddit, author, language, age, and moderation signals. Blend learned and content-based scores, use exploration carefully, and avoid treating missing history as a meaningful negative signal.
-
Monitoring and deployment should track feature freshness, missingness, prediction distributions, calibration, latency, error rates, and segment-level ranking metrics. Use shadowing, canary rollout, rollback, and drift detection; distinguish covariate drift from label or behavioral drift before retraining automatically.
Worked example: Build and evaluate click prediction models
For Build and evaluate click prediction models, a strong candidate first clarifies the surface, prediction horizon, serving latency, traffic scale, and whether the model ranks candidates or only estimates click probability. They would explicitly define impression-level labels and leakage-safe feature cutoffs, including how repeated impressions and users with no clicks are handled. The answer can be organized around data and labels, feature generation and online parity, model selection and calibration, offline evaluation, and production monitoring. They might start with regularized logistic regression as an interpretable baseline, then compare XGBoost or a neural model using time-based validation rather than random splitting. A key tradeoff is richer interaction features versus serving cost and freshness: a complex model is not useful if it violates the p99 latency budget or relies on stale features. They would evaluate log loss and calibration for probability quality, plus NDCG@k or online ranking metrics if scores determine feed order. They should mention position bias and the danger of training directly on historical clicks generated by an older ranker. They would close by saying that, with more time, they would design an interleaving or controlled online experiment, inspect segment regressions, and validate rollback behavior.
A second angle: Design a Comment-Likelihood Prediction System with a Focus on Feature and Model Serving
For Design a Comment-Likelihood Prediction System with a Focus on Feature and Model Serving, the central prediction is an engagement propensity rather than merely a click, so the label horizon and extreme class imbalance become especially important. The serving design should distinguish slowly changing post and author features from rapidly changing user-session features, with explicit timestamps and defaults for missing history. A calibrated probability can feed a larger utility function, but the model should not silently become a proxy for popularity or exposure. The candidate should emphasize online/offline feature parity, model versioning, fallbacks, and monitoring for stale or unavailable features. The main constraint differs from a generic click model because comments are sparse, delayed, and affected by community context, making delayed labels and temporal validation especially important.
Common pitfalls
Pitfall: Treating historical clicks as unbiased relevance labels. Clicks are affected by position, exposure, thumbnail, and prior ranking; propose randomized data, propensity correction, or a clearly scoped limitation.
Pitfall: Listing “use deep learning and monitor accuracy” without defining the serving contract. State feature freshness, latency, model fallback, versioning, and the exact offline and online metrics tied to the decision.
Pitfall: Going deep into
Kafkaschemas, partitioning, or ETL retries. For an MLE answer, discuss the feature and model interfaces, training-serving skew, deployment strategy, and failure behavior rather than owning data-platform internals.
Connections
An interviewer may pivot to counterfactual evaluation, exploration versus exploitation, feature-store consistency, or fairness and safety constraints in ranking. Be ready to connect ranking metrics to online experimentation and model monitoring without drifting into product strategy or data-pipeline implementation.
Further reading
-
Counterfactual Risk Minimization: Learning from Logged Bandit Feedback — foundations for evaluating and learning from biased logged interactions.
-
Deep Learning Recommendation Model for Personalization and Recommendation Systems — practical architecture for sparse features, embeddings, and interaction modeling.
-
Practical Lessons from Predicting Clicks on Ads at Facebook — calibration, feature engineering, and production CTR modeling lessons.
Practice questions
- Handling High-Cardinality Categorical Features and Cold-Start Items in Embedding ModelsReddit · Machine Learning Engineer · Technical Screen · medium
- Design a Comment-Likelihood Prediction System with a Focus on Feature and Model ServingReddit · Machine Learning Engineer · Onsite · medium
- Explain and Reduce Position Bias in RankingReddit · Machine Learning Engineer · Technical Screen · hard
- Design a video recommendation systemReddit · Machine Learning Engineer · Onsite · medium
- Build and evaluate click prediction modelsReddit · Machine Learning Engineer · Technical Screen · medium
Related concepts
- Recommender And Ranking SystemsMachine Learning
- Recommendation Systems And RankingML System Design
- Recommender Systems, Feed Ranking, And Marketplace MetricsMachine Learning
- Ranking, Recommendation, And Feedback SystemsML System Design
- Recommender Systems And Feed RankingMachine Learning
- Recommendation System DesignML System Design