Feature Stores And Feature Serving
Asked of: Machine Learning Engineer
Last updated
What's being tested
The interviewer is testing whether you can design feature computation and serving as part of a production ML system, not merely list useful predictors. You should demonstrate training-serving parity, point-in-time correctness, freshness guarantees, latency-aware retrieval, and safe handling of missing or stale values. Reddit cares because ranking and engagement models make high-volume, low-latency predictions where a small feature inconsistency can degrade quality globally or create biased feedback loops. They will probe how your choices connect model quality, reliability, deployment, and observability.
Core knowledge
-
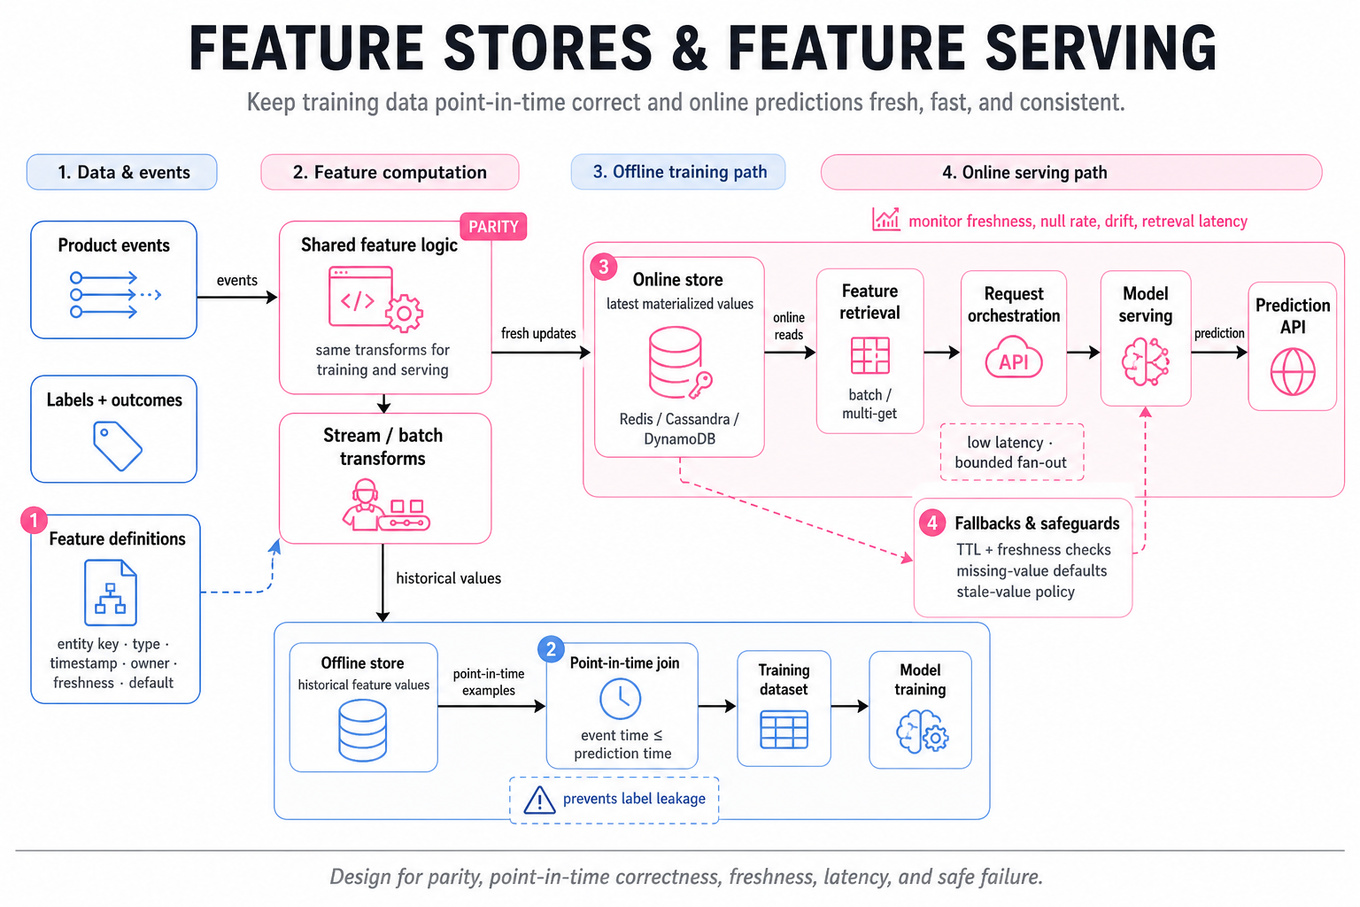
A feature store usually has an offline store for historical training data and an online store for low-latency inference.
`Feast`,`Tecton`, or an internal equivalent may manage definitions, materialization, metadata, and retrieval; the store is not automatically the feature-computation engine. -
Point-in-time joins prevent label leakage: for an entity at prediction time , use only feature values whose event time is . Training examples should resemble serving with , not the latest value of each feature. Late corrections require explicit backfill policy.
-
Define every feature with an entity key, value type, timestamp semantics, owner, expected freshness, and default behavior. Distinguish event time from processing time; “user comments in the last 24 hours” must use the intended window boundary and timezone consistently.
-
Online/offline parity means identical transformation logic, feature names, units, categorical mappings, and null semantics during training and inference. Shared computation, generated code, or validated feature contracts is safer than independently reimplementing Python training logic and Java or Go serving logic.
-
Choose storage by access pattern:
`Redis`or`Aerospike`can provide very low-latency key-value reads, while`Cassandra`,`DynamoDB`, or`Bigtable`offer durable, horizontally scalable access. A request-level feature fetch should meet the model’s latency budget, including network fan-out and serialization. -
Model serving should separate request orchestration, feature retrieval, preprocessing, model execution, and response formatting. Batch or multi-get retrieval is preferable to one remote call per feature; cache stable features, but enforce TTLs so popularity or safety signals do not become silently stale.
-
Establish an explicit latency budget, such as 50 ms at
`p99`for feature retrieval and 20 ms for inference within a 100 ms end-to-end target. Measure`p50`,`p95`, and`p99`, timeout rates, cache hit rate, and fallback frequency rather than only average latency. -
Missing features need typed defaults and an observable policy: zero may mean “none,” “unknown,” or “pipeline failure.” Track missingness indicators when absence is informative, and use model-compatible fallbacks such as global, subreddit-level, or user-segment statistics.
-
Feature freshness is a model-quality contract. A feature with a five-minute SLA may be suitable for comment likelihood, while a rapidly changing abuse or inventory signal may require seconds; expose feature age and reject, degrade, or route predictions when it exceeds a threshold.
-
Evaluate more than aggregate offline metrics. Compare
`AUC`, log loss, calibration, and ranking metrics such as`NDCG@k`or`MRR`; slice by new users, new posts, subreddit, device, and traffic tier. Online impact should be validated with controlled experiments, while guarding latency and error-rate regressions. -
Feature drift describes changes in feature distributions, while concept drift changes the relationship between features and labels. Monitor distribution statistics, null rates, age, cardinality, and prediction calibration; use PSI, KL divergence, or robust quantile comparisons with alert thresholds tied to retraining decisions.
-
For high-cardinality entities and embeddings, avoid fetching thousands of individual values per request. Use compact representations, bounded histories, approximate counters, or precomputed aggregates; version embedding models and dimensions because incompatible vectors can break both storage and inference.
Worked example: Design a Comment-Likelihood Prediction System with a Focus on Feature and Model Serving
For Design a Comment-Likelihood Prediction System with a Focus on Feature and Model Serving, I would first clarify whether the prediction is per impression, whether it ranks posts or only supplies a score, the freshness target, and the acceptable online latency. I would state assumptions such as one score per user-post impression, a binary label defined as a comment within a chosen horizon, and a strict requirement that training features reflect the impression timestamp. I would organize the answer around label and feature definitions, offline training and point-in-time data construction, online feature retrieval and model serving, and monitoring plus rollout. Candidate features might include user and subreddit aggregates, post text or embedding signals, time context, and recent interaction features, with explicit defaults for cold-start users and posts. I would use a versioned feature registry and shared transformations, materialize aggregates into an online key-value store, and retrieve user, post, and context features through batched calls. The key tradeoff is freshness versus latency and cost: real-time counters improve recency but introduce more operational dependency, so I would classify features by freshness tier and provide bounded fallbacks. I would monitor feature age, missingness, retrieval `p99`, calibration, log loss, and slice performance, while comparing online engagement against guardrails such as latency and downstream comment quality. If I had more time, I would detail experiment design, rollback behavior, feature backfills, and protection against feedback loops caused by showing content predicted to generate comments.
A second angle
For Design a video recommendation system, the same principles apply, but retrieval and ranking usually operate at much larger candidate volumes and may include sequential behavior and video embeddings. The candidate-generation stage favors precomputed, compact features and approximate nearest-neighbor retrieval, while the final ranker can afford richer user-video cross features for a smaller set. Freshness, watch-time labels, playback context, and position bias become especially important because a click or impression is not equivalent to meaningful consumption. I would also separate candidate-generation feature SLAs from final-ranking SLAs and evaluate both recall and ranking quality. The central tradeoff shifts toward representation size, throughput, and multi-stage latency rather than only per-request feature freshness.
Common pitfalls
Pitfall: Treating the feature store as a magic fix for leakage. Saying “we load the latest user features into training” is wrong when those values include behavior after the label timestamp; describe point-in-time joins and time-aware aggregation instead.
A communication mistake is jumping straight to `Redis`, `Kafka`, or a model framework without clarifying prediction granularity, latency, freshness, and cold-start behavior. A stronger answer states assumptions first, then ties each technology choice to a measurable requirement.
Pitfall: Staying too shallow on serving by saying “cache features and call the model.” Explain batching, timeouts, stale-value policy, version compatibility, observability, and what happens when one dependency fails; these are the decisions that distinguish production design from a model notebook.
Connections
The interviewer may pivot to training-serving skew, data and concept drift, model rollout and canarying, online experimentation, or cold-start recommendation. Be ready to connect feature quality to calibration, ranking metrics, feedback loops, and rollback decisions.
Further reading
-
Feast documentation: Point-in-time joins — concrete guidance on constructing leakage-resistant historical features.
-
Michelangelo: Uber’s Machine Learning Platform — a production-scale perspective on feature pipelines, training, and serving.
Practice questions
Related concepts
- Production ML Serving, Feature Stores, And MonitoringML System Design
- ML Feature Pipelines And Training-Serving ArchitectureML System Design
- Candidate Generation, Ranking, And Feature StoresML System Design
- ML Model Serving ArchitectureML System Design
- Production ML Pipelines And System DesignML System Design
- Feature Store and Training-Serving Consistency