ML Model Serving Architecture
Asked of: Machine Learning Engineer
Last updated
What's being tested
These interviews test whether you can turn an ML model into a reliable, low-latency product capability rather than stopping at model selection. The interviewer is probing feature serving, model serving, online/offline parity, deployment safety, and operational evaluation under realistic recommendation traffic. Reddit cares because ranking and engagement predictions must serve millions of requests with fresh community, user, and content signals while avoiding latency regressions, stale features, and training-serving skew.
Core knowledge
-
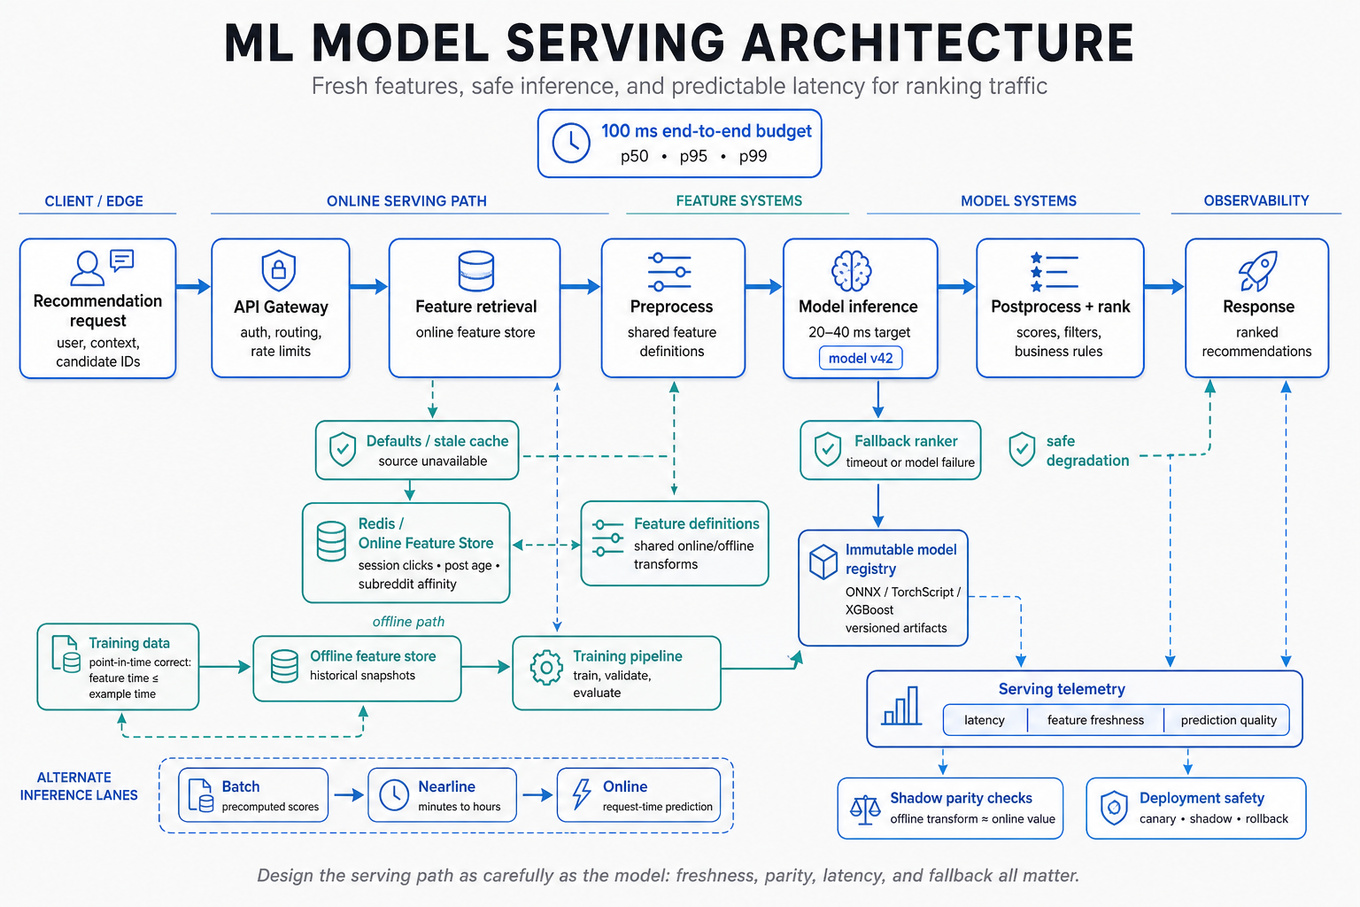
Serving-path decomposition separates request handling, feature retrieval, preprocessing, inference, postprocessing, and fallback behavior. State an explicit latency budget, such as 100 ms end-to-end with 20–40 ms allocated to model inference, then measure each component at
`p50`,`p95`, and`p99`. -
Online features are computed or retrieved during inference: recent impressions, session activity, post age, subreddit affinity, and creator statistics. Use a low-latency key-value store or online feature store such as
`Redis`, while keeping the feature definition shared with offline training. -
Offline features support training and batch scoring from historical data. Point-in-time correctness is mandatory: for an example at time , a feature must satisfy ; otherwise future activity leaks into training and produces deceptively strong validation metrics.
-
Training-serving skew occurs when transformations differ between training and inference—for example, training uses a log-transformed count while production sends a raw count. Centralize feature definitions, validate distributions, and run shadow comparisons between offline transformations and online values.
-
Feature freshness should match feature semantics. A user’s long-term subreddit affinity may tolerate hourly updates, while session clicks may require seconds; document each feature’s TTL, default value, ownership, and behavior when the source is unavailable.
-
Model serving commonly uses a stateless inference service behind a load balancer, with a serialized artifact such as
`ONNX`,`TorchScript`, or a native`XGBoost`model. Keep model artifacts immutable and versioned; horizontally scale replicas and avoid per-request model loading. -
Batch, nearline, and online inference are different design choices. Precompute expensive scores for stable user-item pairs, refresh them nearline when behavior changes, and reserve online inference for context-sensitive features; a hybrid often gives better cost and latency than scoring every candidate synchronously.
-
Candidate generation and ranking should be separated for recommendation systems. Retrieve hundreds or thousands of candidates using subscriptions, collaborative filtering, embeddings, or popular-content retrieval, then apply a more expensive ranker; do not run a deep model across the entire corpus per request.
-
Caching reduces repeated feature and prediction work, but cache keys must include all prediction-relevant context and model version. Short TTLs help freshness, while stale-while-revalidate or a popularity fallback can preserve availability during cache or feature-store failures.
-
Model evaluation needs both predictive and system metrics. For comment likelihood, track log loss, calibration, and PR-AUC alongside online latency, timeout rate, and fallback rate; for ranking, use NDCG or Recall@K offline, then validate impact on comments, watch time, quality, and negative feedback online.
-
Deployment safety uses canary traffic, shadow inference, versioned models, and rapid rollback. A shadow model receives production requests but does not affect decisions, allowing comparison of score distributions, feature availability, latency, and disagreement before exposure.
-
Drift and reliability monitoring should distinguish data drift, concept drift, and infrastructure failure. Monitor feature missingness, range violations, score/calibration changes, label delay, throughput,
`p99`, timeouts, and segment-level behavior; alerting should have actionable thresholds rather than every small distribution change.
Worked example: Design a Comment-Likelihood Prediction System with a Focus on Feature and Model Serving
In the first 30 seconds, clarify whether the prediction is per user-post pair, whether it is used for ranking or notification, the allowed latency, prediction horizon, and what “comment” excludes, such as deleted or automated comments. I would declare an initial target such as a calibrated probability of commenting within 24 hours, with labels generated only after that window closes. I would organize the answer around label and evaluation design, feature computation and point-in-time storage, online inference architecture, and deployment/monitoring. The request path would retrieve user, post, subreddit, and recent-session features, apply the exact shared transformations, invoke a versioned ranker, and return a score with a defined fallback. A key tradeoff is freshness versus availability: session features may be fetched online for better responsiveness, while slower community aggregates can be materialized hourly and served from cache. I would explicitly handle missing features, cold-start users, feature-store timeouts, and model timeouts with defaults or a baseline model rather than failing the ranking request. I would close by saying that, with more time, I would design a shadow-evaluation plan, calibration analysis by subreddit and user cohort, and a replay test for online/offline parity.
A second angle
For Design a video recommendation system, the same serving principles apply, but scale and candidate volume make a two-stage architecture central. Candidate retrieval can combine followed communities, collaborative filtering, embedding nearest-neighbor search, and freshness or popularity sources before a heavier ranking model scores a bounded set. Video-specific features such as completion rate, watch time, skips, and content embeddings introduce delayed labels and stronger freshness requirements than a simple comment event. I would also address privacy-aware feature use, content safety filtering, and diversity constraints before final ranking. The main framing shift is optimizing a feed under repeated exposure, not merely returning one calibrated user-post probability.
Common pitfalls
Analytical mistake: Treating offline AUC as proof that the serving design works is tempting, but it ignores calibration, ranking position bias, feature freshness, and latency-induced fallbacks. A stronger answer connects offline log loss or NDCG to online experiments and explicitly measures prediction quality by important cohorts.
Pitfall: Saying “use the latest feature value” without enforcing point-in-time joins creates leakage and invalidates the evaluation.
Communication mistake: Jumping directly into `Kafka`, `Redis`, or Kubernetes components before clarifying the prediction contract makes the design sound infrastructure-led rather than ML-led. Start with label, horizon, request rate, latency, freshness, and failure assumptions, then justify each serving component against them.
Depth mistake: Saying “put the model behind an API” is insufficient for an MLE interview. Explain artifact versioning, preprocessing parity, batching or caching, canary/shadow deployment, timeout behavior, drift monitoring, and rollback ownership.
Connections
The interviewer may pivot to feature stores, training-serving skew, ranking evaluation, model monitoring, or A/B experimentation. They may also ask how delayed labels, counterfactual exposure, cold start, and privacy constraints change the serving design.
Further reading
-
TFX: Data Validation and Model Analysis — Practical patterns for validating features, detecting skew, and evaluating deployed models.
-
Hidden Technical Debt in Machine Learning Systems — Explains why serving dependencies, feedback loops, and monitoring matter beyond model code.
-
[Designing Machine Learning Systems](https://www.oreilly.com/library/view/designing-machine-learning/978 media) — A broad treatment of data, deployment, monitoring, and production tradeoffs.
Practice questions
Related concepts
- Production ML Serving, Feature Stores, And MonitoringML System Design
- ML Feature Pipelines And Training-Serving ArchitectureML System Design
- ML System Design, Recommenders, Forecasting And AllocationMachine Learning
- Production ML Systems, Evaluation, And SafetyML System Design
- Production ML Pipelines And System DesignML System Design
- Production ML Infrastructure and MonitoringBehavioral & Leadership