What to expect
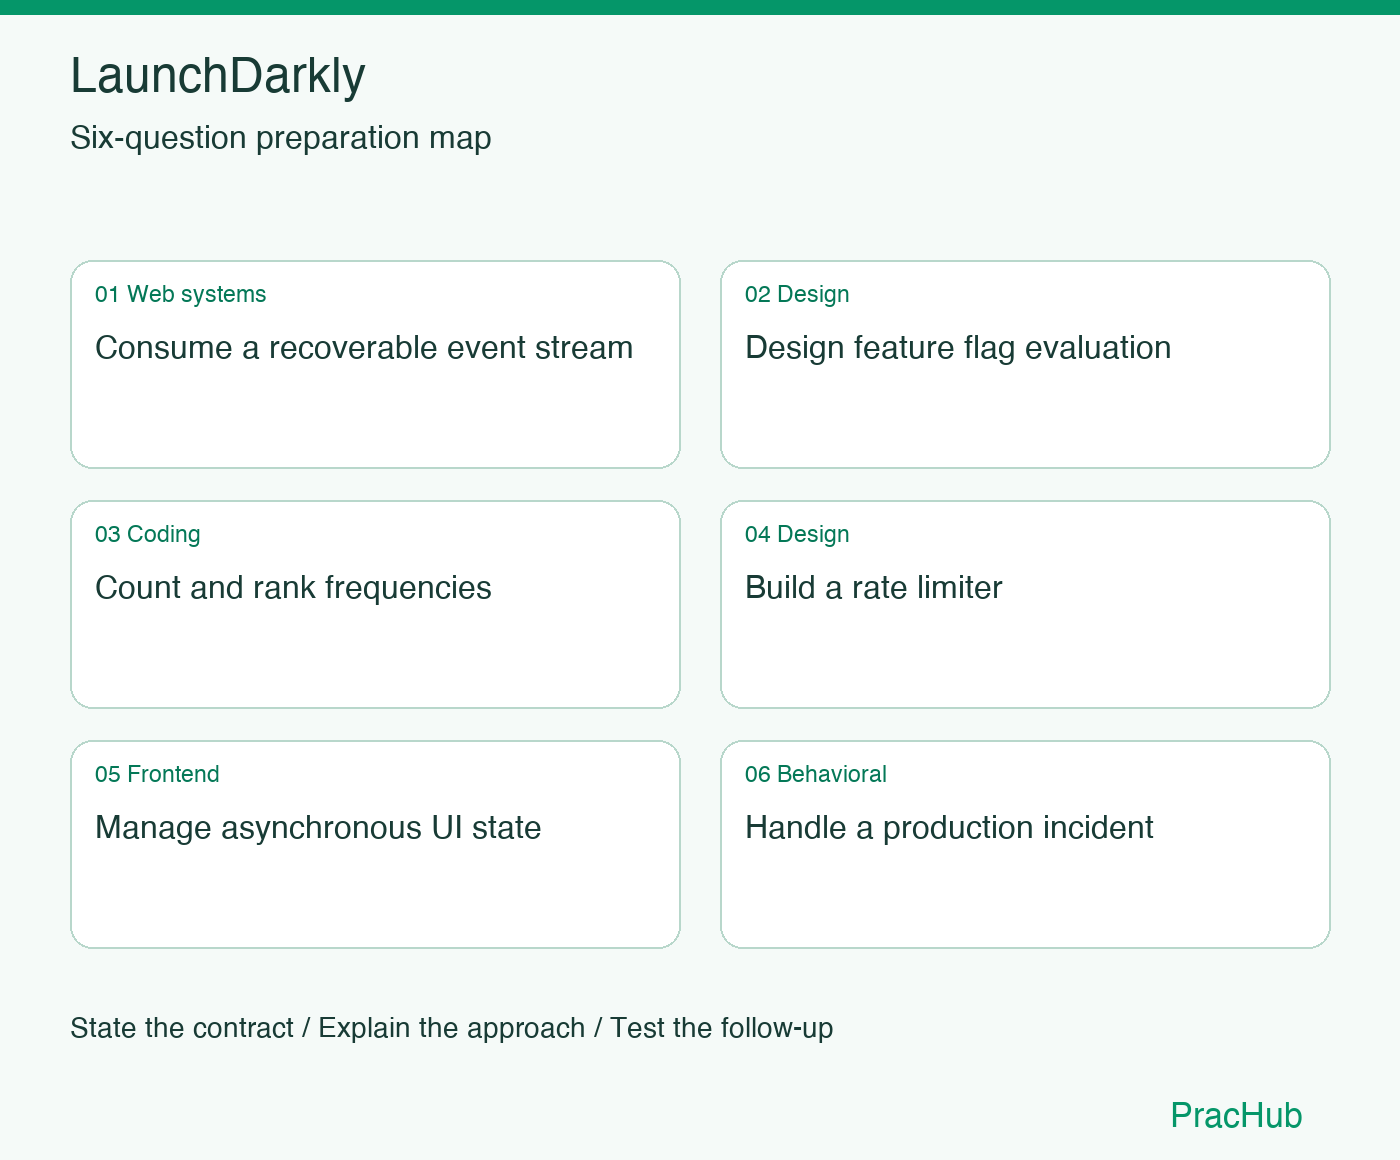
Prepare for a LaunchDarkly Software Engineer conversation by connecting technical fundamentals to flag state and recoverable streaming. This guide gives you six focused practice questions, an illustrated design exercise and a study plan with concrete outputs. Use it to build answers you can explain and test, then adjust the emphasis to the actual team and assessment.
LaunchDarkly's official company resource provides background on feature management software. That context helps you ask better questions about users and product constraints. It does not establish a required interview language, a fixed sequence of rounds or a promised set of questions.
Explore six guide-only practice questions →
Build a role brief before you study
A useful starting question for this domain is how a team would detect and recover from a disconnected client evaluating an outdated flag rule. Write down who is affected, what they should be able to trust and which component owns the accepted state. This is an original practice scenario, not a description of LaunchDarkly's internal architecture.
Read the vacancy with three columns in your notes: a stated requirement, an example from your work that demonstrates it, and an uncertainty to ask about. Separate an explicit language or framework requirement from a tool you happen to prefer. If the role is mainly frontend, focus on state, accessibility and browser behavior; if it is infrastructure-oriented, bring deeper evidence about concurrency, failure recovery and operation under load.
Ask the recruiter which assessments apply, whether work is live or take-home, what tools are permitted and how seniority changes the expected depth. Make those answers change your preparation. A timed coding discussion calls for a different rehearsal from a project review or a collaborative debugging session.
Choose your first practice session
Begin with consume a recoverable event stream, design feature flag evaluation, count and rank frequencies. Read each prompt without its answer, state the contract aloud and attempt a solution before checking the approach. The follow-ups are designed to expose assumptions, so write the changed requirement before changing your implementation.
For a coding task, retain one small example with expected output. For a design task, draw the state owner and one failure boundary. For a project question, identify your own decision and the evidence behind it. These artifacts make gaps visible much faster than rereading an explanation you already recognize.
Guide-only practice question bank
These six practice topics are selected from the published third-party guide. PracHub supplies the clarified problem statements, solution approaches and follow-ups. Treat them as preparation material; their inclusion does not independently verify that this employer asked them.
Consume a recoverable event stream
Practice prompt: Consume a persistent stream and keep an application projection correct through disconnects and bursts.
Solution approach:
- Define event identity, ordering scope and the baseline snapshot. A reconnect must reconcile missed changes rather than assume the stream resumes at exactly the right point.
- Bound buffers and batch display updates so a fast producer cannot block the interface or exhaust memory. Separate transport reconnection from domain-level recovery.
- Test duplicates, out-of-order events, expired replay history and a slow client. If replay is unavailable, refresh a new snapshot and resume from its version boundary.
Follow-up: How would you detect that a client’s local projection has fallen too far behind to replay safely?
Design feature flag evaluation
Practice prompt: Evaluate changing feature rules quickly while defining what happens when the configuration service is unavailable.
Solution approach:
- Separate rule distribution from evaluation. Cache a validated version locally where appropriate, but define the fallback when no usable configuration exists.
- Keep targeting data and secrets at an appropriate trust boundary. A browser cannot keep a server secret simply because an SDK hides it from the interface.
- Test stale rules, invalid updates, deterministic bucketing and reconnects. Measure evaluation latency separately from the time it takes a new rule to reach every client.
Follow-up: How would you safely roll back a rule that is syntactically valid but harmful?
Count and rank frequencies
Practice prompt: Count occurrences by key and return the most frequent key with a deterministic tie rule.
Solution approach:
- Use a hash map from key to count, then compare counts under the chosen tie rule. The key could be a character, user ID or error code; validate the field before counting.
- Expected processing is O(n), with O(k) space for k distinct keys. A full sort is unnecessary for one maximum; top-K requires an additional bounded selection structure.
- Test no records, one record, equal counts and malformed records. Explain whether invalid records are rejected, skipped with an error count, or quarantined.
Follow-up: How would you handle a key space too large for an in-memory map?
Build a rate limiter
Practice prompt: Protect an API with a stated request-rate policy and support concurrent callers.
Solution approach:
- Choose a policy before a data structure: fixed window, sliding window or token bucket each allows different bursts. Define the tenant key, clock and what counts as one request.
- Update the decision state atomically. A distributed deployment needs a shared authority or an explicit approximation; independent per-node counters do not enforce a strict global limit.
- Test boundary timestamps, bursts, concurrent requests and store failure. Specify rejection status, retry guidance and whether the limiter fails open or closed for this workload.
Follow-up: How would you combine a per-tenant limit with a global downstream capacity limit?
Manage asynchronous UI state
Practice prompt: Manage a data-heavy interface whose requests may complete out of order as the user changes selection.
Solution approach:
- Separate server data, local draft state and derived display values. Give each request an identity so an older response cannot overwrite a newer selection.
- Define loading, empty, error and retry states. Cancel obsolete work when possible, but still guard response application because cancellation is not always immediate.
- Test rapid selection changes, navigation away during a request and network failure. Keep updates immutable where the framework expects that, and measure before adding memoization.
Follow-up: How would you preserve unsaved user edits while refreshing server data?
Handle a production incident
Practice prompt: Describe how you investigated and mitigated a serious service problem under pressure.
Solution approach:
- Establish scope, user impact and an incident timeline. Separate observed facts from hypotheses, and choose the next log, query or trace that distinguishes competing explanations.
- Mitigate with a bounded action and communicate its effect. Preserve enough evidence for root-cause analysis rather than restarting everything without a reason.
- Explain recovery validation, follow-up ownership and a prevention change. If you use a personal or course project, state that context honestly instead of implying production responsibility.
Follow-up: What evidence told you the service was recovered rather than temporarily quiet?
Design walkthrough: flag state and recoverable streaming
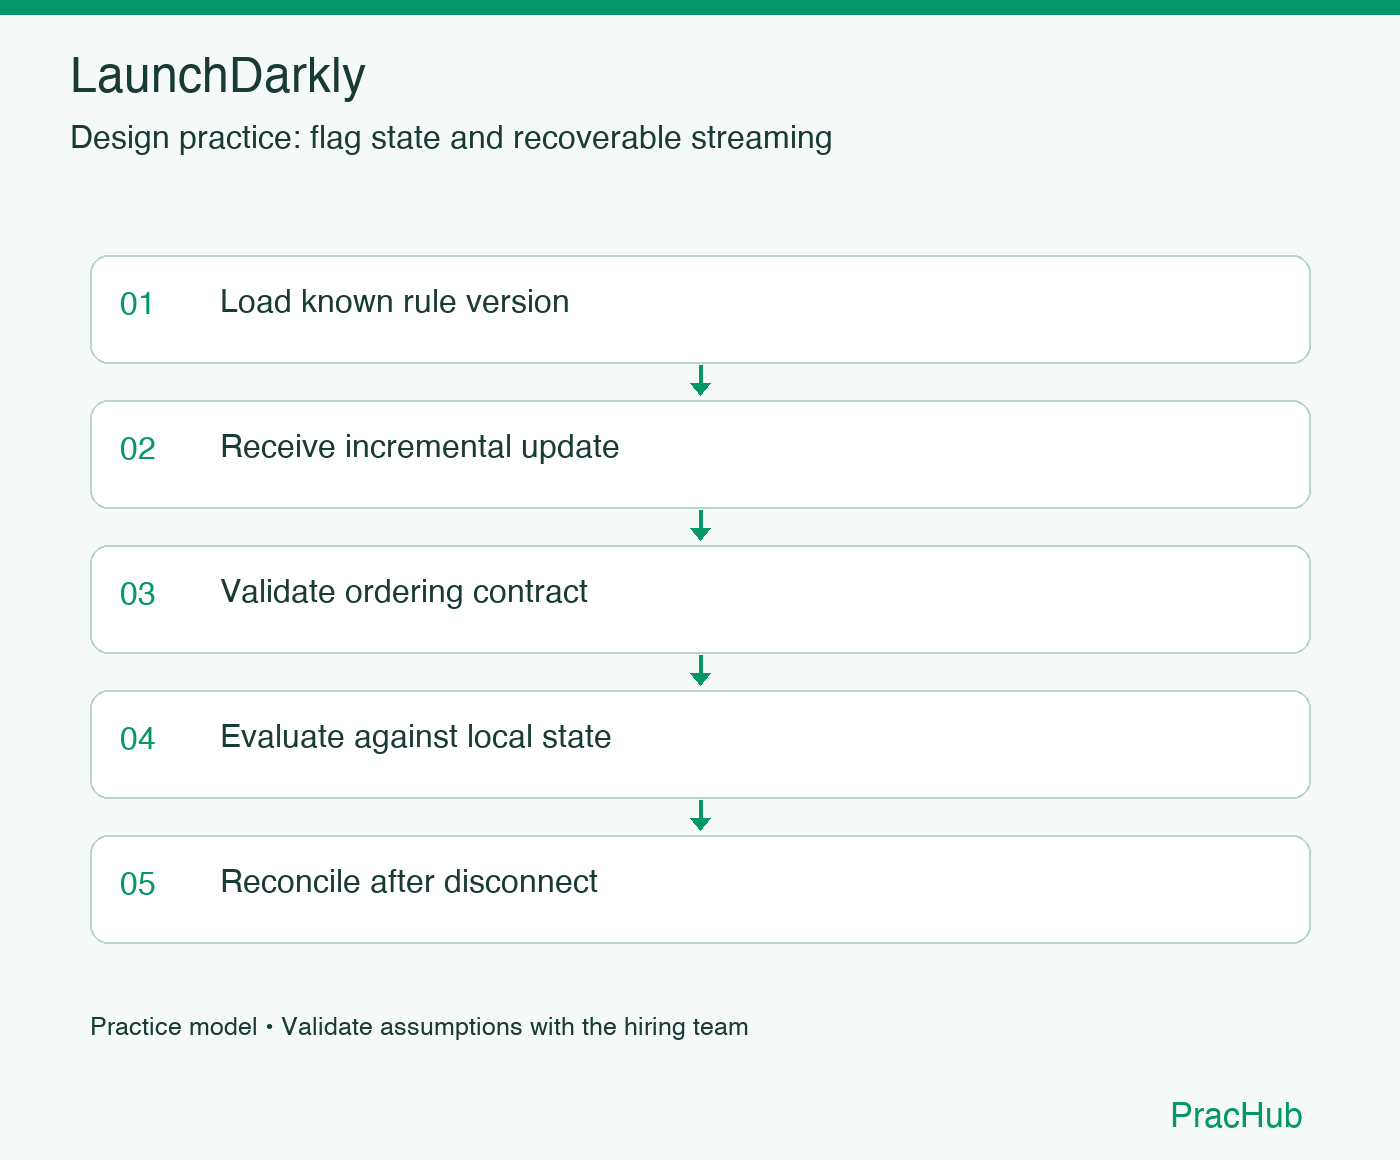
Use this exercise to connect the selected topics to a plausible application in feature management software. The diagram is a preparation model with deliberately simplified boundaries. It is not a claim about the company's deployed systems.
Scenario: A disconnected client evaluating an outdated flag rule. Explain how the system discovers the discrepancy, what remains authoritative and what a user can do while recovery is in progress.
Establish the contract
Start at load known rule version. Define the input identity, the caller's permissions and the result that counts as acceptance. Use one normal request and one invalid request to test whether your description is precise. If the operation can be repeated, decide whether a retry means another attempt at the same work or an intentionally new operation.
Then explain receive incremental update. Identify what is checked before state changes and what may still fail afterward. Avoid a success response that implies more than the system has actually completed. An accepted request, a durable record, a delivered message and a refreshed screen can be four different milestones.
Put ownership where the invariant lives
At validate ordering contract, name the record or state transition that must remain correct when two callers race. Choose a transaction, conditional update or single owner for that invariant. Describe the losing caller's result as carefully as the winning caller's result. A lock or queue is useful only if it protects the right boundary.
Keep derived displays and reports separate from authoritative state. Write down which version a displayed result represents and how that version is invalidated or refreshed. If a view may lag, define how the user recognizes that it is pending or stale. Do not hide an uncertain outcome behind a generic error message that encourages uncontrolled retries.
Make the failure observable
Now exercise evaluate against local state with a slow or unavailable dependency. Trace the identifier through the request, durable record, asynchronous work and final view. For the scenario above, show one concrete discrepancy between expected and observed state and the evidence that distinguishes an incomplete operation from a completed operation whose response was lost.
Finish with reconcile after disconnect. A recovery procedure should explain who can perform it, how repeated execution is made safe and what evidence proves completion. Bound retries and surface work that cannot progress automatically. Keep the original failure visible long enough to investigate rather than deleting the evidence as part of a replay.
Test the design before adding more components
Run four variations: a duplicate request, an out-of-order observation, a dependency timeout and an unauthorized caller. For each, record the expected durable state and the user-visible result. If a variation does not apply to your chosen operation, explain why instead of adding a mechanism by habit.
Only then discuss scaling. Identify the first likely bottleneck using the work performed per request, the size of retained state and the slowest dependency. More replicas can amplify a shared database or queue bottleneck. Explain what you would measure before choosing sharding, caching or another independently deployed service.
Explain your reasoning in the interview
Make the first answer small and correct
Begin with the contract and a simple approach. Explain its cost and limitations, then improve the part that conflicts with a stated constraint. If you propose an optimization, preserve a test that demonstrates the original behavior. In a design discussion, a small system with a clear failure contract is easier to evaluate than a large diagram with unnamed responsibilities.
Handle a changed requirement explicitly
When the interviewer adds concurrency, a larger dataset or a failing dependency, pause and name the assumption that changed. Describe what remains correct and which boundary needs revision. Do not restart the entire answer unless the new requirement invalidates the original model. This makes adaptation visible and gives the interviewer a chance to correct your interpretation early.
Bring a project story with evidence
Prepare an example relevant to flag state and recoverable streaming. Explain the constraint, your personal contribution, an alternative you considered and the outcome you verified. If you lack professional experience in this domain, use a course or personal project honestly and describe what extra controls production work would need. Never invent traffic numbers, savings or responsibility to make the story sound more senior.
A two-week preparation plan
This is a suggested schedule, not LaunchDarkly's interview timeline. Move effort toward the confirmed assessment and the topics where your first attempt exposed a gap.
| Session | Concrete output |
|---|---|
| Days 1–2 | A role brief and an attempted answer to consume a recoverable event stream. |
| Days 3–4 | A tested answer to design feature flag evaluation, including one failure or boundary case. |
| Days 5–6 | Rehearse count and rank frequencies and explain a changed requirement. |
| Days 7–8 | Complete build a rate limiter and compare your reasoning with its checklist. |
| Days 9–10 | Work through manage asynchronous ui state and handle a production incident. |
| Days 11–12 | Annotate the design diagram with ownership, failure and recovery. |
| Days 13–14 | Run a mock, repair the weakest answer and prepare questions for the team. |
After each session, record what you could not explain without looking at the answer. Turn that uncertainty into a small test, diagram or documented example. Repeating a question is useful when the second attempt demonstrates a specific improvement, such as a clearer invariant or a previously missed edge case.
Questions to ask the team
Ask which user workflow needs the most attention, how the team knows a change is working and where engineers spend time diagnosing failures. For LaunchDarkly, use the discussion of flag state and recoverable streaming to make the questions concrete: which system owns the truth, which views may lag and who handles discrepancies between them?
Also ask how code reviews, production support and onboarding work for this specific role. The answers help you assess the work and prepare relevant examples without assuming that every team at one company has the same stack or responsibilities.
Frequently asked questions
Are these confirmed LaunchDarkly interview questions?
The six topics are selected from a third-party company guide; the problem clarifications, solution approaches, diagrams and follow-ups are PracHub preparation material. The third-party listing is not independent confirmation that this team asks these questions. Use current recruiter instructions for the actual format.
Do I need to use the language shown in a reference?
Use the language required by the assessment, or your strongest suitable language when there is a choice. Reference documentation helps verify behavior; it does not prove the employer requires that language. Be ready to explain your data structures and test cases without relying on memorized syntax.
What if I have only a weekend?
Complete the first two selected questions, trace the design failure above and prepare one honest project story. Prefer a few answers you can defend over a wide list of topics you cannot explain. For more exercises, use the PracHub Software Engineer question bank.
Sources and further reading
- LaunchDarkly: company background — context on feature management software; use the actual vacancy to establish role requirements.
- Dataford: LaunchDarkly Software Engineer guide — source of the selected practice topics, with PracHub-authored explanations and follow-ups. Its company-question attribution has not been independently confirmed.
- MDN web documentation — Look up browser APIs, networking and JavaScript behavior relevant to the selected exercises.
- Microsoft architecture patterns — Compare documented patterns and their tradeoffs instead of treating a pattern name as a complete design.
- Python data structures — Review sequences, dictionaries, sets and their behavior when implementing the coding exercises.
- MDN HTTP overview — Check HTTP request, response and connection semantics when defining an API contract.
- React: managing state — Review state ownership, update behavior and common state-management mistakes.
- Google SRE: monitoring distributed systems — Use latency, traffic, errors and saturation to structure operational diagnosis.