Observability And ML Incident Management
Asked of: Machine Learning Engineer
Last updated
What's being tested
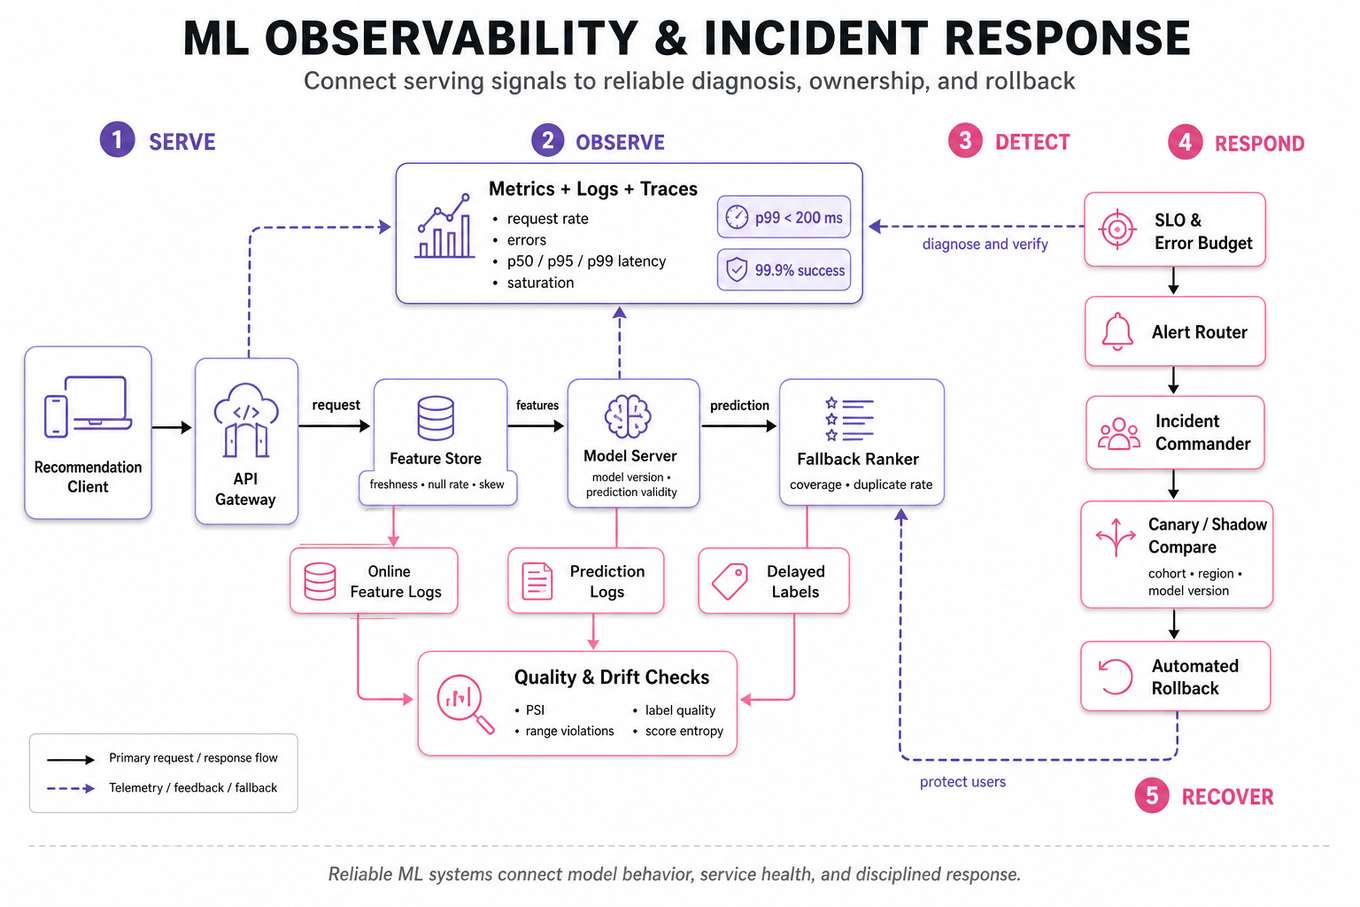
These interviews test whether you can make ML systems observable, detect failures before they materially harm users, and lead a disciplined response when they do. Reddit cares because recommendation and ranking models influence what communities see at high volume, while failures can affect relevance, latency, safety, and trust simultaneously. The interviewer is probing for an MLE who connects model behavior to service-level signals, distinguishes infrastructure failures from data and model failures, and communicates ownership without overclaiming certainty.
Core knowledge
-
Observability combines logs, metrics, and traces to explain system behavior; for ML, add feature distributions, prediction distributions, label-based quality metrics, model versions, and training-serving skew rather than monitoring only CPU and error rate.
-
Track the golden signals: request rate, errors, latency, and saturation. For recommendation serving, segment
p50,p95, andp99latency by endpoint, model version, region, device, cache status, and fallback path; averages hide tail failures. -
Define SLOs before alerts: for example, 99.9% successful responses and
p99latency below 200 ms over a rolling window. An error budget converts reliability into a deployment constraint: repeated budget burn should pause launches. -
Monitor data quality at feature and prediction boundaries: null rate, range violations, cardinality, freshness, and distribution changes. A useful drift statistic is PSI: ; thresholds require calibration, not blind adoption.
-
Detect training-serving skew by computing the same feature transformation in both paths where possible, then comparing sampled online feature values with offline-recomputed values. Version feature definitions and record transformation metadata so incidents are reproducible.
-
Separate model quality from proxy health. Monitor delayed labels such as watch time or engagement when available, but also use immediate proxies—fallback rate, recommendation coverage, score entropy, duplicate rate, and block or hide feedback—to detect degradation before labels arrive.
-
Use canary releases, shadow traffic, and automated rollback. A canary should compare treatment and control by model version and important cohorts; rollback criteria can combine latency, error rate, prediction validity, and statistically significant quality regression.
-
Design fallbacks deliberately: a previous-known-good model, cached recommendations, popularity within a relevant community, or a chronological feed. Validate that fallback content remains safe, policy-compliant, and available when dependencies such as feature stores fail.
-
Make incidents diagnosable with structured logs containing request ID, model version, feature-set version, experiment assignment, candidate count, retrieval source, timeout reason, and fallback reason. Avoid logging raw private content or unnecessary user identifiers.
-
Use distributed tracing to attribute latency across retrieval, feature lookup, ranking, policy filtering, and response assembly. Trace sampling must preserve rare failures, and high-cardinality dimensions should be bounded to avoid making telemetry itself expensive or unusable.
-
Establish an incident lifecycle: detect, triage, mitigate, validate, communicate, and conduct a blameless postmortem. During mitigation, freeze risky changes, assign an incident owner, preserve evidence, and record a timeline; afterward, create concrete owners and due dates for corrective actions.
-
Treat alert quality as an ML problem: tune thresholds using historical incidents, require persistence or multi-signal confirmation, and page only on actionable symptoms. A drift alert without a user-impact hypothesis is investigation work, not necessarily an emergency.
Worked example — Design a video recommendation system
For “Design a video recommendation system,” I would first clarify the target surface, latency and availability SLOs, recommendation objectives, privacy constraints, traffic scale, and whether labels such as watch completion arrive quickly enough for online monitoring. I would state an assumption such as a two-stage system: candidate retrieval followed by a ranking model, with policy and safety filtering before serving. I would organize the answer around feature and event logging, offline training and evaluation, online serving and fallback, and observability with incident response. For observability, I would track request success, p99 latency, candidate count, feature-store timeout rate, model-version prediction distributions, filtering rate, and delayed quality metrics such as completion or meaningful watch time. I would connect each alert to a response, such as routing to a previous model when feature freshness breaks or rolling back when a canary shows a quality regression. One explicit tradeoff is between richer real-time features and reliability: I would prefer bounded-time lookups plus a safe default over allowing personalization dependencies to violate the serving SLO. I would also explain cohort-level monitoring because aggregate metrics can hide failures affecting a language, device type, community, or cold-start users. If I had more time, I would specify alert thresholds from historical baselines, runbook ownership, privacy-safe logging, and a post-launch rollback drill.
A second angle — Describe a failure and a success
For “Describe a failure and a success,” the same concept is evaluated through operational judgment rather than architecture: choose an incident involving a model launch, feature issue, or monitoring gap and explain impact with measured evidence. A strong response follows situation, action, result, and learning, while distinguishing your decisions from the team’s broader work. Include how you detected the problem, narrowed the hypothesis, mitigated user impact, communicated uncertainty, and prevented recurrence through a test, alert, dashboard, or runbook. The success should demonstrate reliable delivery and measurable improvement, not merely that a model had a better offline score.
Common pitfalls
Analytical mistake: Treating feature drift as proof that model quality has declined is tempting but incorrect; user mix can change without harmful predictions. Pair drift with calibration, proxy outcomes, cohort slices, and serving-health signals, and state which labels are delayed or unavailable.
Pitfall: “The dashboard turned red, so I rolled back” omits diagnosis and may cause unnecessary reversions. Explain the trigger, blast radius, confidence, mitigation, and validation step.
Communication mistake: Blaming the data pipeline, platform team, or a vague “bad deployment” weakens an incident answer. State what you owned, how you collaborated, what users experienced, and how you communicated status while facts were still incomplete.
Depth mistake: Listing Kafka, tracing, or alerting tools without defining actionable thresholds is not observability design. Tie every important signal to a failure mode, an owner, a response, and a tradeoff such as alert sensitivity versus fatigue.
Connections
An interviewer may pivot to offline/online evaluation, feature-store consistency, canary deployment, data drift, calibration, or privacy-aware telemetry. Be ready to connect observability to SLOs, experiment guardrails, rollback automation, and postmortem-driven reliability improvements.
Further reading
-
Google SRE Book — Monitoring Distributed Systems — practical guidance on signals, symptoms, and actionable monitoring.
-
Machine Learning: The High-Interest Credit Card of Technical Debt — explains why hidden dependencies and weak monitoring make ML systems difficult to operate.
-
Hidden Technical Debt in Machine Learning Systems — a foundational framing for maintenance, monitoring, and failure modes in production ML.
Practice questions
Related concepts
- ML Observability And Production MonitoringML System Design
- Production ML Infrastructure and MonitoringBehavioral & Leadership
- Production ML Systems, Evaluation, And SafetyML System Design
- Production ML Serving, Feature Stores, And MonitoringML System Design
- Production ML Pipelines And System DesignML System Design
- ML Model Serving ArchitectureML System Design