HackerRank Python Basic Certification Prep: Practice the Published Skills With Original Tasks
Quick Overview
Map the published Python Basic competencies to two original, runnable exercises on aggregation, deterministic output, instance state, and snapshot behavior.
For HackerRank Python Basic certification prep, start with the published Python skills, then prove you can use them in a small, unfamiliar program. Practice normalizing string keys, choosing collections, defining function contracts, and keeping each object's state independent. Use a fresh task to check those skills before attempting the certification.
This guide is for candidates who know introductory Python and want a practical readiness check. The two exercises below are original PracHub practice tasks, with explicit inputs, expected outputs, and failure cases. They are not certification questions or an official passing rubric.
Use Python Language and Runtime Fundamentals on PracHub to rehearse your explanations alongside the code. Some question content requires account access; the worked tasks here are self-contained.
What does HackerRank Python Basic officially cover?
Official facts: HackerRank's Python Basic skills directory names control flow and functions, strings and collections, iteration, modular program design, classes and attributes, and built-in functions. That is broader than solving a few array problems in Python. You need to understand what the language does when you update a list, iterate paired inputs, or create a second instance.
The certification landing page displayed 90 minutes and two questions when checked on October 11, 2026. Treat those as dated catalog observations and confirm the instructions shown before your own attempt. Those two catalog fields establish duration and question count only; they provide no evidence about particular prompts, hidden tests, or a passing threshold.
Candidate-report boundary: our research did not establish two independent, same-cycle firsthand accounts sufficient to verify the current Python Basic prompts or scoring. Employer assessments hosted on HackerRank and public certificate announcements are different evidence. This guide therefore uses official competency descriptions and original practice, rather than reported answer lists.
Preparation inference: a useful readiness check asks whether you can implement and explain a contract you have not memorized. The following map converts the published areas into observable work; it is our teaching rubric, not HackerRank's scoring model.
| Published skill area | Evidence to produce in practice | Failure to investigate |
|---|---|---|
| Functions and control flow | Return a result after scanning every reading | Returning inside the loop |
| Strings, collections, iteration | Normalize names and aggregate with a dictionary | Duplicate keys caused by inconsistent normalization |
| Modular design | Separate a pure summary function from stored history | Printing instead of returning the requested value |
| Classes and attributes | Give each practice book independent entries | A mutable class attribute shared across instances |
| Built-ins | Explain the iterator and result produced by the tools you choose | Assuming every built-in returns a reusable list |
Task 1: summarize labeled readings with exact rules
Imagine a small calibration workshop. Two lists contain labels and integer readings at matching positions. Implement summarize_readings(labels, readings, minimum) with this original contract:
- Labels contain ASCII letters and optional surrounding spaces. Normalize each with
strip().lower(). - Readings and the minimum are nonnegative integers. These value types are guaranteed by this exercise.
- The lists must have equal lengths; otherwise raise
ValueError. - Sum every reading for each normalized label. Repeated labels are additional measurements, not duplicates to discard.
- Keep totals greater than or equal to the minimum. Return
(label, total)tuples, ordered by descending total and then ascending label. - Preserve the caller's inputs. Two empty lists produce an empty result.
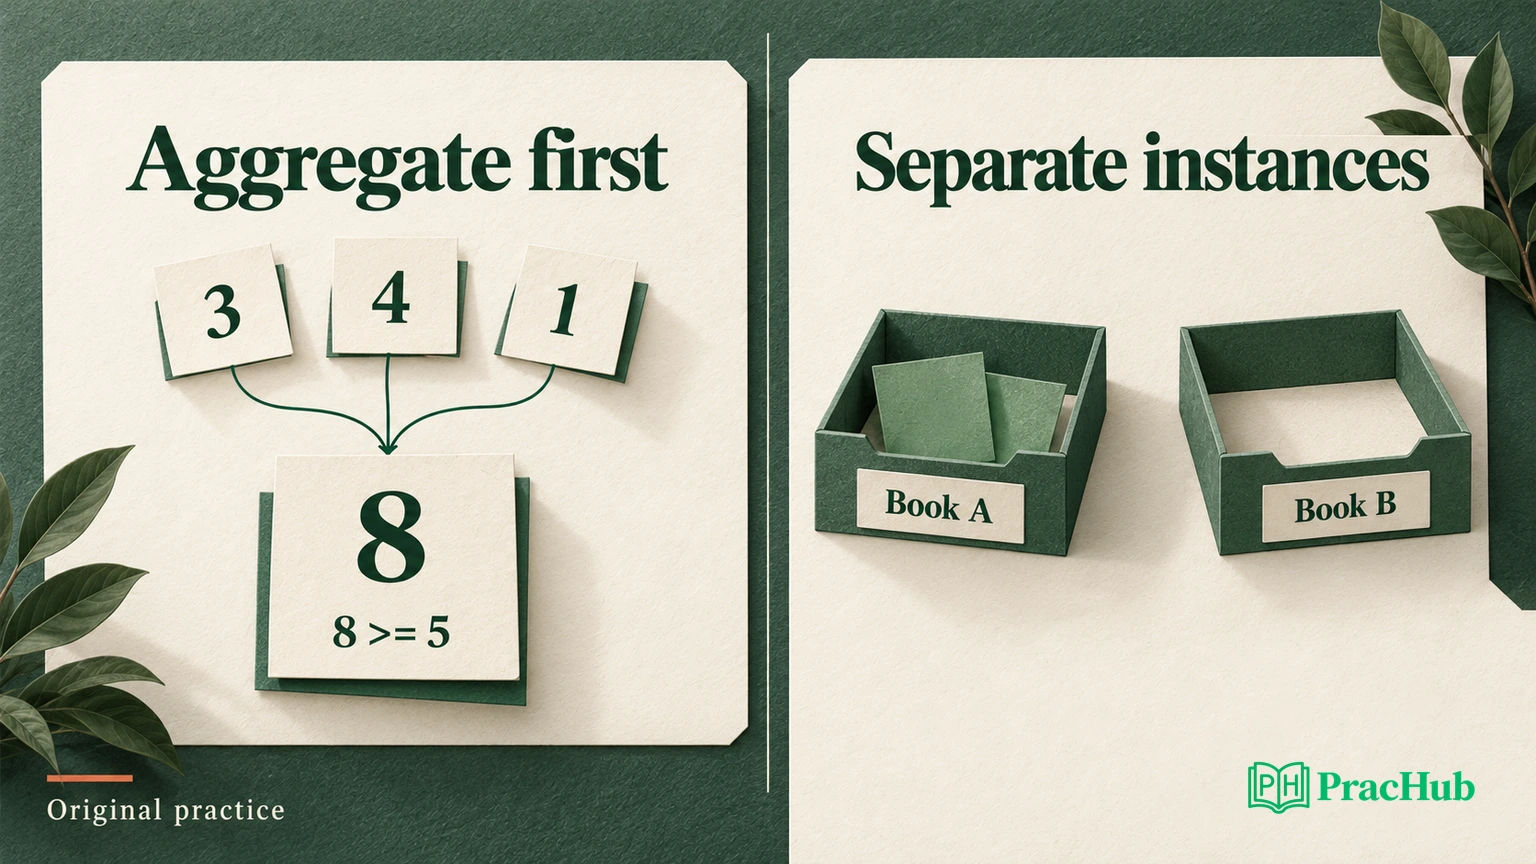
For labels = [" Iris ", "iris", "Oak", "IRIS"], readings = [3, 4, 5, 1], and minimum = 5, the answer is [("iris", 8), ("oak", 5)]. Iris combines three readings; Oak qualifies exactly at the boundary. The normalized label, rather than the original spelling, appears in the output.
Before coding, write that result yourself. Then add a tie: labels = ["Oak", "Iris"], readings [5, 5], minimum 5. The answer becomes [("iris", 5), ("oak", 5)]. This tie test catches a solution that accidentally uses input order instead of the required alphabetical order.
These examples make three independent requirements visible: normalization, inclusive filtering, and a secondary sort key. A solution can get two right and still fail the third. Keeping those requirements separate makes debugging faster than repeatedly changing the whole function.
Implement the function and explain the choices
One reference implementation is:
def summarize_readings(labels, readings, minimum):
    if len(labels) != len(readings):
        raise ValueError("paired inputs must have equal lengths")

    totals = {}
    for label, reading in zip(labels, readings):
        key = label.strip().lower()
        totals[key] = totals.get(key, 0) + reading

    eligible = [
        (key, total)
        for key, total in totals.items()
        if total >= minimum
    ]
    return sorted(eligible, key=lambda item: (-item[1], item[0]))
The length check is part of the contract. Python's built-in function documentation explains that ordinary zip stops at the shortest iterable. Without the check, an extra label or reading disappears silently. Under a suitable Python version, zip(..., strict=True) is another option, but explain its behavior and confirm the actual environment before relying on it.
The dictionary stores one accumulated total per normalized label. get(key, 0) supplies a starting total, so a first occurrence and a repeated occurrence follow the same update rule. A set would preserve distinct names but lose the totals. A list of all original pairs would preserve more information than this output requires.
The sort key negates the total to put larger totals first while leaving names in ascending order. Simply sorting tuples in reverse order reverses both fields, producing the wrong alphabetical tie order. Construct a tied example whenever a task mixes ascending and descending requirements.
Let n be the number of readings and k the number of distinct labels. With bounded label length and average dictionary behavior, accumulation takes expected O(n) time; sorting eligible labels takes at most O(k log k). Retained state is O(k). For unbounded labels, account for string normalization and comparison costs rather than pretending every string operation is constant time.
The input lists stay unchanged because the function builds a new dictionary and returns a new list. Python's data-structures tutorial is useful background for distinguishing operations that mutate a list from functions that construct a result. You should be able to name which objects your own function changes.
Build counterexamples instead of counting solved samples
For this reading-summary function, record the expected output and the rule each test checks.
| Input change | Required result | What a failure reveals |
|---|---|---|
| Empty paired lists | [] | Incorrect assumptions about a first element |
One label with reading 5, minimum 5 | That label with total 5 | An exclusive > comparison |
Repeated normalized labels with readings 3, 4, 1 | One total of 8 | Overwriting or deduplicating measurements |
Two totals of 5, labels Oak and Iris | Iris before Oak | Missing or reversed secondary key |
A label with reading 0, minimum 0 | Include its zero total | Filtering by truthiness |
| Different input lengths | ValueError | Silent truncation |
Also save copies of both input lists before the call and compare them afterward. That check catches a solution that sorts or rewrites the caller's data while still returning the expected answer.
Do not add requirements that are absent from the contract. This task guarantees nonnegative integers and ASCII labels, so it does not need a complete international name normalizer or a parser for arbitrary JSON. In an unfamiliar assessment, first identify which inputs are guaranteed and which must be validated. Extra rules can change valid outputs just as easily as missing rules can.
Task 2: keep independent attempt histories
The next original exercise concerns objects rather than aggregation. Implement an AttemptBook that stores (topic, passed) pairs in append order. Topic is a string and passed is a Boolean, guaranteed by the exercise. Repeated topics remain separate attempts. A new book starts empty; snapshot() returns an outer-list copy that callers may edit without changing the book.
First predict this broken design:
class BrokenBook:
    entries = []

    def record(self, topic, passed):
        self.entries.append((topic, passed))
Create two books, record ("collections", True) in the first, then inspect the second's entries. It sees the same entry because the mutable list belongs to the class and is shared. If creating a fresh book still exposes old attempts, inspect where its list was allocated: this example stores it on the shared class.
Python's classes tutorial explains the distinction between class and instance variables, including the danger of shared mutable class data. A repaired implementation allocates the list for each instance:
class AttemptBook:
    def __init__(self):
        self.entries = []

    def record(self, topic, passed):
        self.entries.append((topic, passed))

    def snapshot(self):
        return list(self.entries)
Now create first and second, record two attempts in first, and confirm that second.snapshot() is still []. Next clear a snapshot returned by first; a fresh snapshot must still contain both attempts. These checks distinguish independent instances from an independent exported container. They are different properties.
A shallow copy is sufficient for this contract because entries are tuples containing strings and Booleans, all immutable. If an entry later contains a mutable list, copying the outer list does not isolate that nested list. Explain the boundary rather than claiming that list(...) makes every object deeply independent.
The public entries attribute also remains directly mutable. This teaching class promises snapshot isolation, not a security boundary or fully encapsulated history. If a follow-up requires callers to update state only through methods, discuss the revised interface explicitly. Do not claim protections that your code does not provide.
Rehearse the explanation after the tests pass
For the function, explain why normalization happens before grouping and why a threshold belongs after aggregation. Filtering each individual reading first would remove Iris's 3, 4, and 1 even though their combined total qualifies. That is a semantic error, not a performance issue.
For the class, point to the exact statement that allocates instance state and describe what the snapshot copies. Then change one requirement: suppose callers need the most recent result per topic rather than all attempts. A dictionary might now fit, but it would intentionally discard earlier attempts. Choosing a collection is a decision about information preservation.
Try implementing a second version from a blank file without looking at the reference. Compare outputs and side effects, not variable names. If you need a hint, record whether it concerned syntax, the contract, the collection choice, or the test design. Those categories lead to different next practice sessions.
Five PracHub questions for targeted follow-up
These are verified PracHub question records for transferable practice, not predictions of Python Basic certification prompts. Some include topics beyond the published basic scope; select the relevant subquestion rather than treating every extension as mandatory. Access to full content can vary by account.
| PracHub question | Use for this preparation |
|---|---|
| Python Language and Runtime Fundamentals | Explain language behavior before running a snippet. |
| Explain Python lists, dicts, and concurrency | Focus first on list-versus-dictionary operations; concurrency is an extension. |
| Implement a Safe Average Function in Python | State numeric and empty-input contracts before implementation. |
| Python and pytest Fundamentals: Fixtures, Decorators, and Generators | Practice small reproducible tests; advanced tooling is optional. |
| Python Multiple Inheritance: Which Parent Method Runs When Names Collide | Use as a later object-model extension, after instance state is clear. |
Decide whether your next step is study or an attempt
Editorial recommendation: attempt the certification when you can implement both original tasks, reproduce their counterexamples, and explain the important object and iteration behavior without reading a solution. Use this as a readiness signal for these skills; it cannot predict a certification result or establish complete prompt coverage.
If the function fails, revisit the failed rule instead of collecting more answer links. If the class fails, draw which object owns each list. If both work only with the reference open, repeat a changed contract before adding more advanced topics. Keep one small record of the assumption that caused each failure.
Before starting the actual assessment, check the shown runtime, input/output interface, timer, allowed resources, and submission instructions. HackerRank's certification FAQ says it does not share official certification questions or solutions. Use published competencies and honest practice rather than treating an answer dump as an official study guide.
The goal of HackerRank Python Basic certification prep is a demonstrable language foundation: predictable functions, appropriate collections, controlled mutation, and explanations backed by examples. Return to Python Language and Runtime Fundamentals after your next blank-file attempt and explain one behavior more clearly than before.
Sources and Further Reading
- HackerRank: Python Basic certification catalog
- HackerRank: Python Basic skills directory
- HackerRank: certification FAQs
- Python documentation: data structures
- Python documentation: classes and instance variables
- Python documentation: built-in functions, including zip
Research checked October 11, 2026. Catalog details may change. All worked tasks and datasets above are original practice.
Comments (0)