Precision-Recall Curves And Classification Metrics
Asked of: Data Scientist
Last updated
What's being tested
Candidates must show they can evaluate and compare binary classifiers under realistic constraints: compute and interpret precision–recall curves, choose operating thresholds aligned to asymmetric business costs, and summarize performance with metrics that are meaningful under class imbalance. Interviewers probe statistical correctness (formulas, edge cases), practical computation (sorting, ties, libraries), and how to translate metrics into a decision (threshold choice, expected-cost reasoning) for product or experiment decisions.
Core knowledge
-
Confusion matrix entries: true positive (TP), false positive (FP), false negative (FN), true negative (TN); all classification metrics derive from these counts.
-
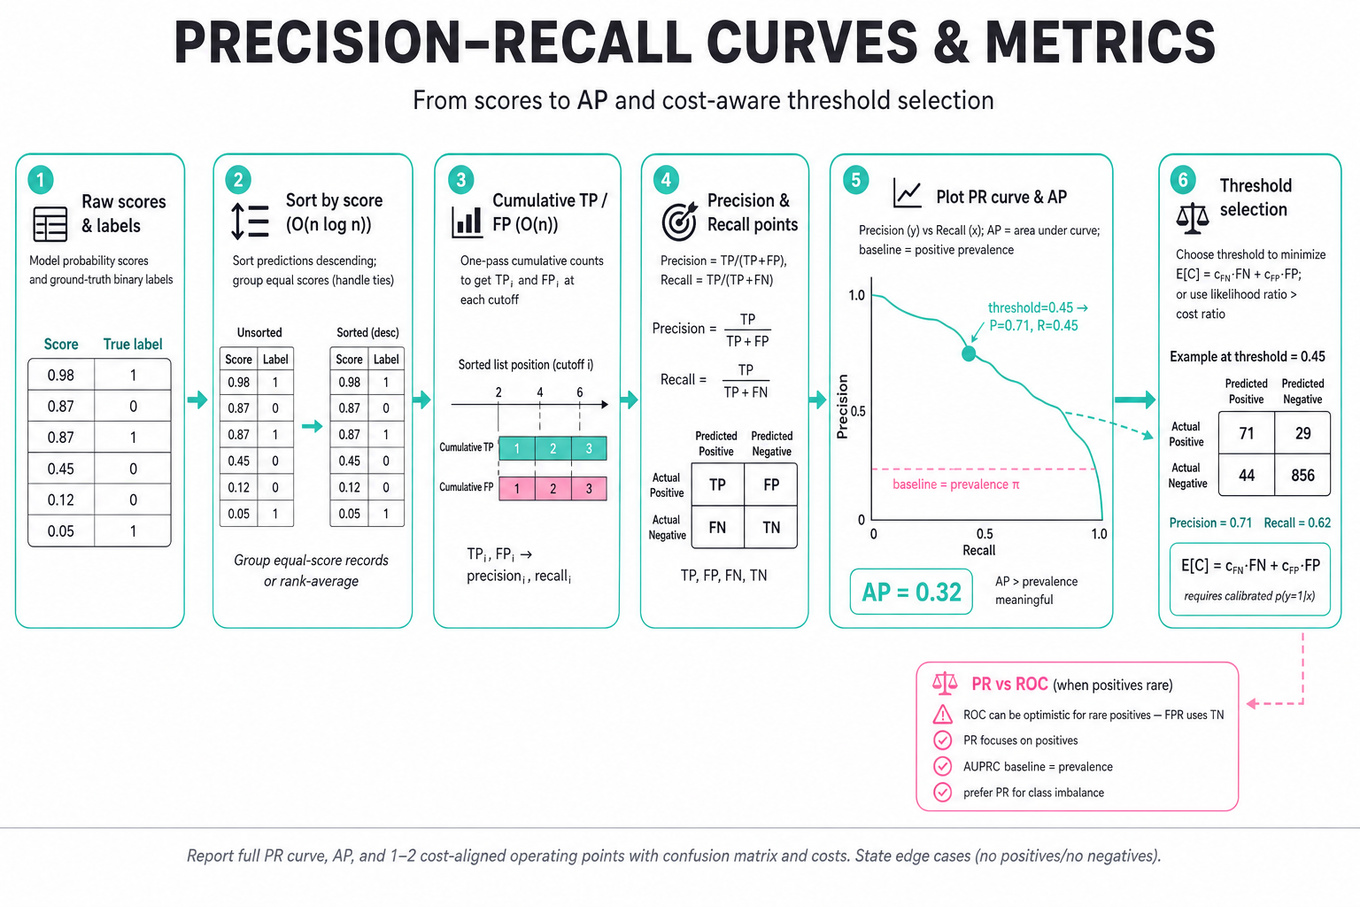
Precision: . Recall (sensitivity): . F1: harmonic mean .
-
Precision–recall curve: plot precision (y) vs recall (x) by sweeping the threshold on model scores; points correspond to unique score cutoffs after sorting predictions by descending score.
-
Average Precision (AP) / AUPRC: area under the precision–recall curve; AP emphasizes performance on the positive class—baseline equals positive prevalence (), so AUPRC > is meaningful.
-
Why prefer PR over ROC: ROC/AUROC can be overly optimistic on rare positives because false positive rate uses TN in denominator; PR focuses on positives and is sensitive to class imbalance (see Saito & Rehmsmeier).
-
Computation details: sort by score , compute cumulative TP/FP in one pass , handle ties by grouping equal-score records or using rank-average; Python libraries (
scikit-learnprecision_recall_curve,average_precision_score) implement standard variants. -
Edge cases: no positives recall undefined (or zero) and baseline AP = 0; no negatives leads to precision = 1 at all recalls; report these explicitly when presenting results.
-
Threshold selection under asymmetric costs: minimize expected cost or equivalently choose threshold where likelihood ratio exceeds cost ratio; calibration of probabilities matters for cost-based thresholds.
-
Reporting: show the full PR curve, AP value, and one or two operating points (threshold, confusion matrix, precision/recall) with business-aligned cost interpretation and confidence intervals (bootstrap).
-
Statistical uncertainty: obtain CI on AP/precision/recall via bootstrap or stratified resampling; for small positive counts use exact binomial intervals for recall at a point.
-
Ranking vs probability: PR curve works with ranked scores; if scores are uncalibrated, ranking-based metrics (AP) still valid, but cost-minimizing thresholds require calibrated probabilities (
Platt scaling,isotonic regression). -
Visualization nuance: PR curves are often step functions; interpolation method (interpolating precision at increased recall) affects AP numeric value—state which method used.
Worked example — Compute and plot a precision–recall curve
Frame: ask whether you have probabilistic scores or only binary predictions, confirm the evaluation set is holdout and whether positives are rare or sample-weighted. Skeleton: (1) sort predictions by descending score, (2) sweep unique thresholds computing cumulative TP/FP to get precision and recall points, (3) plot precision vs recall and compute Average Precision with trapezoidal/integration rule, (4) annotate business-relevant operating points and CI via bootstrap. Tradeoff to call out: whether to group ties (same-score examples) — grouping yields fewer thresholds and a stable curve, but may slightly change AP; document your tie strategy. If using scikit-learn, call precision_recall_curve and average_precision_score and state which interpolation they implement. Close: say you'd next derive threshold(s) that minimize expected cost using calibrated probabilities and produce bootstrap CIs for AP and for the chosen operating point.
A second angle — Choose Classification Metrics Under Asymmetric Costs
Here the same precision/recall machinery informs a cost-sensitive decision. Start by eliciting business costs: quantify and or their ratio. Convert costs to an objective: choose the threshold that minimizes on validation data (or expected over calibrated probabilities). Present both a visual approach (overlay cost lines on PR or ROC space) and a numeric one (compute cost at each threshold).
Tip: Flag calibration: if model scores are poorly calibrated, map scores to calibrated probabilities before computing expected cost; otherwise thresholding by raw score may be suboptimal.
For extremely imbalanced positives, consider decision rule based on top-K predictions if downstream capacity or attention is limited.
Common pitfalls
Pitfall: Reporting accuracy as the main metric on imbalanced data. Accuracy can be near 100% with a useless model; prefer PR/AUPRC and confusion-matrix at selected thresholds.
Pitfall: Treating AUROC and AUPRC as interchangeable. AUROC measures separability across both classes; AUPRC focuses on positive-class retrieval and is sensitive to prevalence—use AUPRC for rare positives.
Pitfall: Selecting thresholds without accounting for probability calibration. If you optimize expected-cost on uncalibrated scores, your chosen threshold and estimated costs will be biased; calibrate (e.g.,
Platt scaling) or use ranking-based objectives if calibration isn't possible.
Connections
Precision–recall analysis frequently connects to probability calibration, cost-sensitive learning (cost matrices, asymmetric loss), and ranking metrics (AP, nDCG) for top-K decisions. Interviewers may pivot to model calibration methods, uplift/causal metrics for treatment targeting, or experiment-design consequences of classifier thresholds.
Further reading
-
scikit-learn precision-recall documentation — implementation notes and function behavior for
precision_recall_curveandaverage_precision_score. -
Saito & Rehmsmeier (2015), “The precision‑recall plot is more informative than the ROC plot when evaluating binary classifiers on imbalanced datasets” — explains when and why to prefer PR curves.
Practice questions
- Choose Classification Metrics Under Asymmetric CostsMicrosoft · Data Scientist · Technical Screen · medium
- Compute and plot a precision–recall curveMicrosoft · Data Scientist · Technical Screen · easy
- Compute and plot a precision–recall curveMicrosoft · Data Scientist · Technical Screen · easy
- Design a model for imbalanced conversionsMicrosoft · Data Scientist · Technical Screen · hard
Related concepts
- Classifier Evaluation And Cost-Sensitive ThresholdsMachine Learning
- Classification Thresholds, Imbalanced Learning And RiskMachine Learning
- Classifier Evaluation, Calibration, And Thresholding
- Evaluation, Statistical Inference, And Class ImbalanceMachine Learning
- Cost-Sensitive Threshold OptimizationStatistics & Math
- Logistic Regression, Regularization, And Imbalanced ClassificationMachine Learning