Databricks software engineer interview preparation benefits from building components whose behavior you can explain under failure. A cache is a good example: fast lookup is only one part of the contract. Updating an existing value, evicting it, acknowledging a write and recovering after a crash can all disagree unless the design makes their ordering explicit.
This guide combines dated official process guidance with an original persistent-cache fixture. The code and tests are teaching material, not Databricks production code or a recalled private question.
Use official guidance, then confirm your invitation
Databricks’ April 2025 engineering interview preparation PDF describes a backend path with a 30-minute recruiter screen, a one-hour technical screen, internal team matching, a panel combining four to six one-hour interviews, committee review, references and offer. Treat this as dated company guidance rather than a promise about every 2026 role.
The backend modules include coding, algorithms, system programming, architecture, domain deep dive and cross-functional discussion. The document accepts different programming languages while expecting fluency. It describes implementation, testing, synchronization, I/O and storage as relevant areas; its frontend and database tracks differ.
Ask which modules apply to your role, whether pseudocode or runnable code is expected, which environment you will use, and what tools are permitted. Practice in that environment. A product frontend role needs different emphasis from a storage-infrastructure role.
Convert preparation into inspectable outputs
| Practice area | Output to bring to a mock | Failure to expose |
|---|---|---|
| Implementation | Small API, trace and tests | An overwrite breaks accounting |
| Concurrency | Shared-state and lock map | A read sees stale committed data |
| Persistence | Commit and acknowledgement timeline | Success is returned before persistence |
| Architecture | Scope, bottleneck and evolution plan | A faster design changes guarantees |
| Project discussion | True contribution and measured evidence | A proposed mechanism is presented as deployed |
Start with PracHub’s Design a single-node persistent in-memory cache. The verified Databricks-tagged practice record asks for single-process concurrency, byte capacity and small critical sections without disk I/O. Its coaching also discusses sharding and recovery.
The separate implementation below is a smaller synchronous write-through baseline. It deliberately keeps one lock across disk work to establish a simple correctness trace. It does not meet the linked question’s latency discipline or hard total-memory requirement. The follow-up section explains the redesign those constraints require.
Original exercise and contract
Implement get, put and delete for immutable byte values. Keep an exact least-recently-used RAM layer and a persistent backing store. Multiple threads share one owning instance. A successful write returns only after the backing-store transaction commits.
Resolve these choices before coding:
- Keys are nonempty strings; values are nonempty immutable
bytes. Missing keys returnNone. - The demonstration budget counts cached value bytes only. Keys, Python objects, database pages and returned references are outside it. This is not a bound on process memory.
- A value larger than the payload budget is rejected before mutation. Updating a key subtracts its old byte size before adding the new size.
getrefreshes RAM recency. A backing-store hit is inserted into RAM and can evict older RAM entries.- Eviction removes only a RAM copy. The persistent row remains available.
deleteremoves both logical value and cached copy. - Restart begins with empty RAM and loads values on demand. Recency is not persisted.
- Reopening with a smaller budget leaves an oversized existing value readable without caching it. Its returned bytes are outside the RAM payload budget.
- One instance owns the path. External writers or concurrent cache instances are outside the coherence contract.
This is a bounded cache over a persistent key-value store, not a persistent record of the exact resident cache. If the requested product must forget evicted values, eviction must be a durable deletion instead. That changes both recovery and write load.
Walk four bytes through the cache
Use a four-byte payload budget. Put a=AA and b=BB: RAM order from least to most recent is [a,b], and usage is four. Get a: order becomes [b,a]. Put c=CC: b leaves RAM and order becomes [a,c].
Now get b. Its row still exists on disk, so the answer is BB. Loading it evicts a, producing [c,b]. Overwrite b with B: usage becomes three, not five. Delete c: only b remains in RAM, but durable a can still be read.
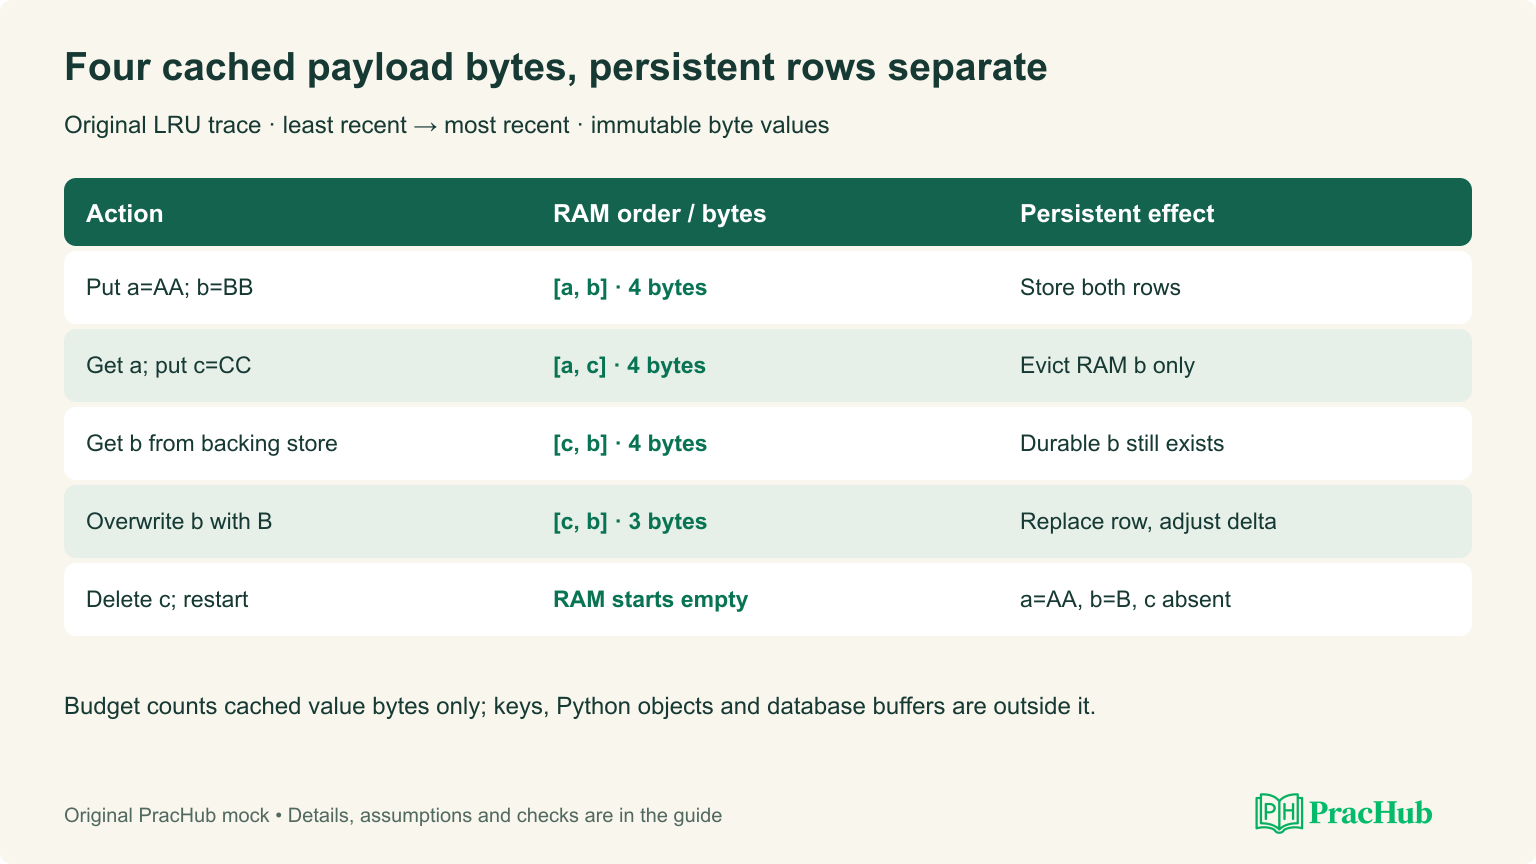
After closing and reopening, RAM is empty. Reading a returns AA; reading b returns B; deleted c is absent. Those observations distinguish eviction from deletion and durable values from transient recency.
Runnable synchronous baseline
Save this code as persistent_cache.py. It uses Python’s standard-library SQLite binding; no third-party package is required. Create one instance with a local database path and budget, then call its methods from your test harness.
The fixture selects SQLite’s rollback journal in DELETE mode and synchronous=EXTRA. It checks that the journal selection took effect. The application delegates journaling and restart recovery to SQLite rather than claiming that a hand-written append log is complete.
import sqlite3
from collections import OrderedDict
from threading import RLock

class PersistentCache:
    """Single owning instance; payload-byte LRU; synchronous teaching baseline."""
    def __init__(self, path, budget):
        if type(budget) is not int or budget <= 0: raise ValueError('budget')
        self.budget, self.used, self.ram = budget, 0, OrderedDict()
        self.lock = RLock()
        self.db = sqlite3.connect(path, check_same_thread=False, isolation_level=None)
        if self.db.execute('PRAGMA journal_mode=DELETE').fetchone()[0] != 'delete':
            raise RuntimeError('rollback journal required')
        self.db.execute('PRAGMA synchronous=EXTRA')
        self.db.execute('CREATE TABLE IF NOT EXISTS kv(k TEXT PRIMARY KEY, v BLOB NOT NULL)')

    def _key(self, key):
        if type(key) is not str or not key: raise ValueError('nonempty string key')

    def _drop(self, key):
        old = self.ram.pop(key, None)
        if old is not None: self.used -= len(old)

    def _remember(self, key, value):
        self._drop(key)
        if len(value) > self.budget: return  # Reopened with a smaller RAM budget.
        while self.used + len(value) > self.budget:
            _, old = self.ram.popitem(last=False); self.used -= len(old)
        self.ram[key] = value; self.used += len(value)

    def get(self, key):
        self._key(key)
        with self.lock:
            if key in self.ram:
                self.ram.move_to_end(key); return self.ram[key]
            row = self.db.execute('SELECT v FROM kv WHERE k=?', (key,)).fetchone()
            if row is None: return None
            self._remember(key, row[0]); return row[0]

    def _write(self, sql, args, key, value, hook):
        with self.lock:
            self._drop(key)  # Invalidate even if commit outcome becomes uncertain.
            try:
                self.db.execute('BEGIN IMMEDIATE'); self.db.execute(sql, args)
                if hook: hook('before_commit')
                self.db.commit()
                if hook: hook('after_commit')
                if value is not None: self._remember(key, value)
                if hook: hook('before_ack')
            except BaseException:
                self._drop(key); self.db.rollback(); raise

    def put(self, key, value, hook=None):
        self._key(key)
        if type(value) is not bytes or not 0 < len(value) <= self.budget:
            raise ValueError('nonempty bytes no larger than payload budget')
        self._write('INSERT INTO kv VALUES (?,?) ON CONFLICT(k) DO UPDATE SET v=excluded.v',
                    (key, value), key, value, hook)

    def delete(self, key, hook=None):
        self._key(key)
        self._write('DELETE FROM kv WHERE k=?', (key,), key, None, hook)

    def close(self):
        with self.lock: self.db.close()
The cache invalidates the affected RAM entry before attempting a write. If a commit or test hook raises, it invalidates again and attempts rollback. That prevents retaining an old cached value after an uncertain commit outcome. The next read queries the backing store. It does not imply the caller can assume the write failed.
Concurrency: correctness first, contention visible
One reentrant lock protects the dictionary, recency, byte counter and database connection. A hit changes recency, so it is a write to shared cache metadata. Immutable returned values avoid in-place mutation of a cached blob by a caller.
A successful put commits and updates RAM before releasing the lock. A later get on the instance therefore observes that write. The test pauses a writer after commit, starts a reader, releases the writer and verifies the reader receives the new value. Four concurrent threads also write and read 160 distinct keys, with all rows retained and the RAM payload within budget.
The cost is explicit: a slow commit stalls unrelated reads. Cache operations are not all constant-time. A hit uses expected constant-time recency operations; a miss includes database lookup, and a large insertion can evict several entries. A SQL index lookup is not a hash-map lookup.
Crash before commit, after commit and before acknowledgement
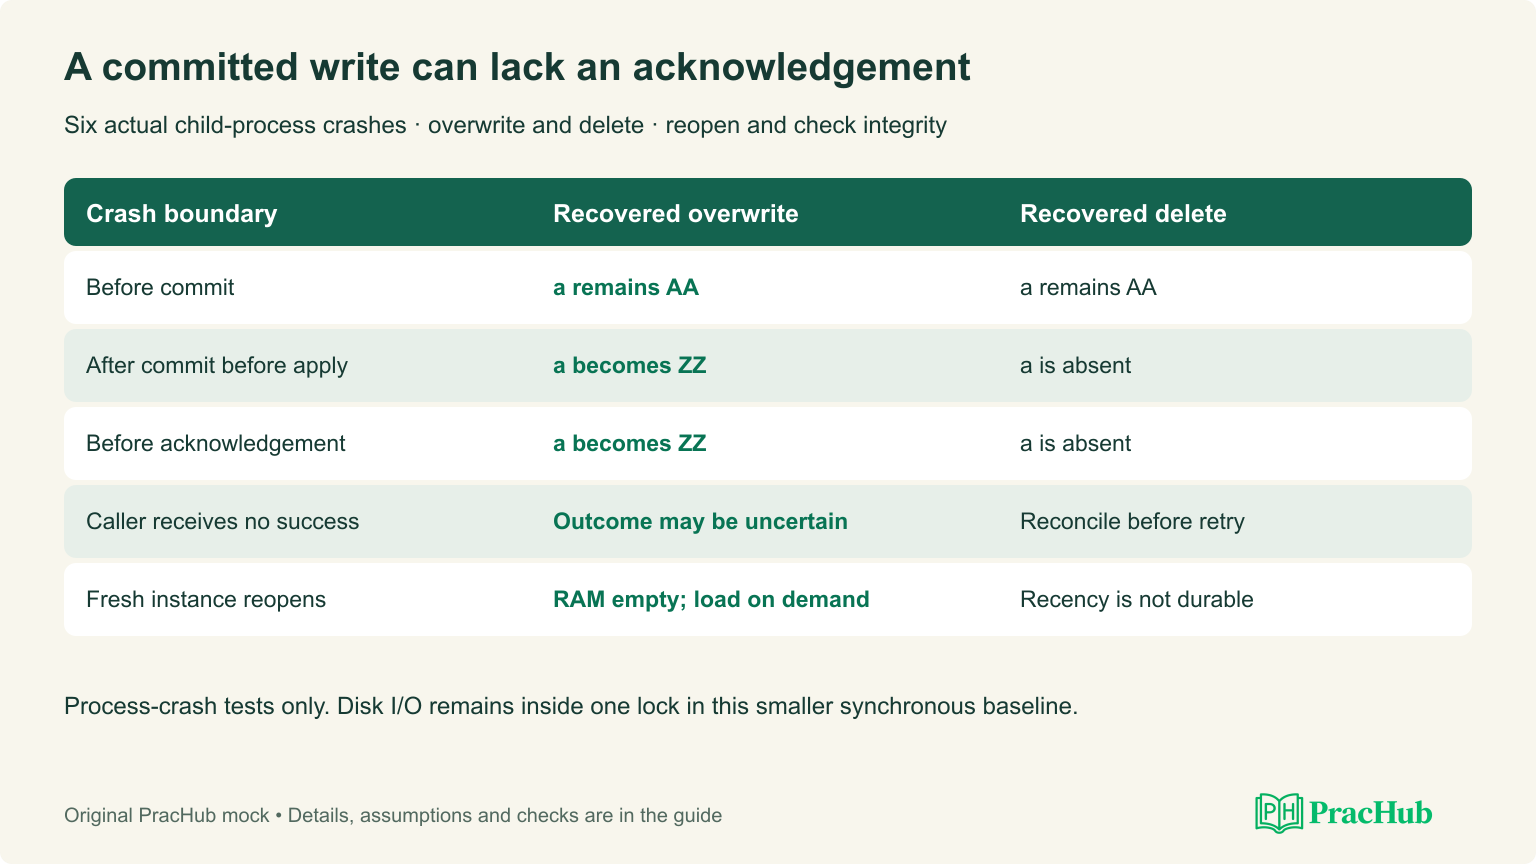
The hook parameter exists for the teaching harness. Run each failure in a disposable child process; terminating the child prevents its normal exception and close paths from cleaning up the transaction. The parent waits for exit, opens a new instance and checks recovered state and database integrity.
| Boundary | Overwrite a=AA with ZZ | Delete a | Caller knows success? |
|---|---|---|---|
| Before commit | Recover AA | Recover AA | No |
| After commit, before RAM apply | Recover ZZ | Key absent | No |
| Before acknowledgement | Recover ZZ | Key absent | No |
All six child-process cases passed. Each child exited at its selected hook; recovery returned the expected state and SQLite’s integrity check reported ok. This tests application-process crashes, not sudden power loss, kernel failure or lying storage hardware.
The post-commit cases expose uncertain outcomes. No response does not mean no effect. Blindly replaying a non-idempotent command after reconnect can apply it twice. This API stores absolute values, but a future increment, append or downstream action needs a stable operation identity and reconciliation contract.
The full local harness passed 437 checks, including a seeded 300-step independent logical-value comparison, accounting checks, invalid-input rejection, restart reads, the six child crashes and the synchronized concurrency scenario. These checks exercise the stated contract. They do not measure production throughput or prove arbitrary storage-failure safety.
Remove disk work from cache locks deliberately
For the linked exercise’s stronger latency requirement, use a dedicated ordered persistence worker and bounded admission. Assign each accepted mutation a sequence and immutable payload outside the shard lock. The persistence worker commits the queued mutation before publishing its applied version to the RAM shard; only then complete its acknowledgement.
Readers must use the shard’s applied state. If persistence is ahead of RAM, a backing-store read must not silently jump to a version that has not been published. Keep a versioned state or wait for publication. A read after a completed write observes at least that applied version. Failed admission must leave state unchanged, and failure after commit needs reconciliation before replay.
A single persistence sequencer simplifies ordering but limits write throughput. Group commit can amortize sync cost: acknowledge a batch only after its shared commit succeeds. Asynchronous acknowledgement changes the durability promise and needs a stated loss window; it is not a free speedup.
Sharding gives per-shard locks and recency, replacing exact global LRU. A hot key can still overload one shard. Budget by measured entry cost, including keys and object overhead, and handle values larger than a shard capacity. Stable routing and a strict lock order become necessary if operations touch multiple shards.
WAL, snapshots and recovery choices
SQLite’s WAL mode supports concurrent readers and a single writer, with checkpointing moving committed pages into the database. Its documentation requires same-host coordination and explains how long readers can hold back checkpoint progress. Selecting WAL does not automatically make the application’s RAM cache coherent with another writer.
For a custom log, define record framing, version, sequence, operation, length and corruption detection. Recovery accepts complete valid records in order and treats a torn tail differently from corruption in the middle. Test delete records, overwrites and duplicate operation IDs, not just inserts.
A custom snapshot must identify the last included sequence. Persist the snapshot and its publication metadata before reclaiming log segments needed for recovery. A crash at every publication boundary must recover either the old snapshot plus log or the new snapshot plus its suffix. A filename rename alone does not settle every persistence requirement.
The runnable fixture implements neither custom WAL nor snapshots; SQLite owns its storage recovery. Those alternatives are design follow-ups with distinct obligations, not features hidden in the code.
Diagnose a slow or incorrect cache
Separate lock wait, database transaction time, RAM hit rate, eviction work and recovery time. A high hit rate can coexist with poor latency if hits wait behind a commit. A byte counter within its payload budget can coexist with high process memory if keys and retained returned values dominate.
For stale reads, inspect ownership of the backing store and commit-to-apply ordering before adding TTLs. For restart discrepancies, first identify whether the requirement was durable values or exact resident membership. For uncertain writes, inspect committed state and operation identity before issuing retries.
Choose a bounded repair and a verification condition. Examples include limiting persistence admission, measuring the longest critical section, or introducing a sequenced apply barrier and replaying the failing trace. Measure correctness alongside latency.
Project deep dive and preparation schedule
Use a true project to explain the user problem, constraints, your decision, rejected alternative, personal contribution and observed result. If you selected a global lock first, explain the workload that made it acceptable and the evidence that would trigger a redesign. Do not claim this local fixture as production employment experience.
On day one confirm your modules and environment. Use days two and three to implement the byte trace and process-crash harness. On day four draw the persistence-worker redesign and work through an uncertain commit. Use day five to measure lock wait and discuss sharding. On day six run a timed mixed mock; on day seven rehearse a truthful project and repeat the weakest explanation.
Frequently asked questions
What process does Databricks officially describe for backend engineers?
The April 2025 engineering preparation guide describes a 30-minute recruiter screen, one-hour technical screen, internal team matching, a panel of 4–6 one-hour interviews, committee review, references and offer. It is dated guidance; confirm your current role’s invitation.
What does a persistent-cache exercise test?
It connects API behavior, memory accounting, recency, concurrency, acknowledgement and recovery. The original fixture below implements a smaller synchronous contract; it does not meet the linked practice question’s no-disk-under-lock constraint.
Does LRU eviction delete the durable value?
Not in this fixture. Eviction removes only the RAM copy, while Delete removes the durable row. A miss can reload an evicted value, and restart begins with an empty RAM cache.
Can a failed request have committed its write?
Yes. The child-process tests demonstrate a write committed before acknowledgement. After restart the new value remains even though the caller did not receive success. Reconcile uncertain outcomes or add stable operation IDs.
Do the crash tests prove power-loss durability?
No. Six tests terminate a child process at defined boundaries and reopen the database. The selected SQLite settings provide a documented durability mechanism, but actual power loss, faulty storage and production loads were not tested.
Sources and scope
- Databricks engineering interview preparation, April2025: dated official backend and other engineering tracks.
- SQLite atomic commit: rollback-journal recovery and storage assumptions.
- SQLite synchronous settings: the chosen EXTRA configuration and documented durability differences.
- SQLite write-ahead logging: alternative concurrency, checkpoint and same-host constraints.
Checked October 9, 2026. The cache, trace and harness are original practice material. Tests use local Python and child-process termination; no Databricks service, production workload, OS crash or power loss is exercised. The invitation controls your current interview details and tool permissions.