Datadog interview preparation should connect code to the behavior of a running service. Can you implement a clear contract, investigate latency with incomplete evidence, and explain what happens when a destination stops responding? Those are useful preparation goals for an observability company, even when your actual interview focuses on ordinary data structures.
This guide includes an original buffered-writer incident, a concurrency repair, log-query examples, and a week of concrete practice outputs. The incident is fictional; the Python checks were run locally. It is not a leaked Datadog assessment or a description of the company's internal systems.
What is confirmed about the Datadog interview process?
Datadog's public candidate-experience page describes an initial recruiter or hiring-manager screen, further interviews, role-dependent take-home work, and executive conversations for some positions. These are possible stages, rather than six mandatory technical rounds. The company says one step is expected to happen in person; confirm the location and arrangements for your role with recruiting.
Before allocating preparation time, ask which stages include coding, practical debugging, system design, or a project discussion. Confirm the language and tools you can use, the length of each session, and whether any assessment permits AI. Avoid building your schedule around an assumed coding platform or an exact number of questions.
For a practical starting point, use PracHub's buffered file writer with concurrency support. Define the writer's contract before coding; then compare your choices with the incident below.
Can you use AI during the interview?
Datadog's AI guidelines, updated May 13, 2026, distinguish assessment types. Some roles explicitly include an AI coding interview, with permission communicated beforehand. Other live coding or technical assessments prohibit AI unless Datadog explicitly says otherwise. Nontechnical interviews also prohibit it. For permitted take-home work, you remain responsible for your conclusions and must explain the submission live.
Use the instructions attached to your specific assessment. Practice reproducing your reasoning without an assistant, including the tests and limitations of any code you submit.
Which preparation route fits your interview?
| Expected discussion | Practice task | Evidence to bring |
|---|---|---|
| Coding | Group logs, maintain a bounded queue, traverse a graph | Working code, input contract, edge cases, complexity |
| Practical debugging | Investigate blocked writes while CPU stays low | Hypotheses, thread-state evidence, a regression check |
| Backend design | Ingest, buffer, route, and query telemetry | Capacity arithmetic, overload policy, failure recovery |
| Project discussion | Explain a service you changed | Your decisions, an incident, a measured outcome |
| Behavioral or team discussion | Describe disagreement and ownership | A specific action, its tradeoff, and what you learned |
Choose the route recruiting confirms. For an early-career coding loop, implement and test the queue before studying multi-region routing. For a senior backend conversation, extend it to delivery semantics and operational decisions. These are preparation recommendations, not a private Datadog scoring rubric.
Debugging mock: why are writes slow when the buffer is nearly empty?
Imagine a service that accepts log records into an in-memory buffer. A background thread periodically sends a batch to a destination. Users report slow requests after the destination's response time increases.
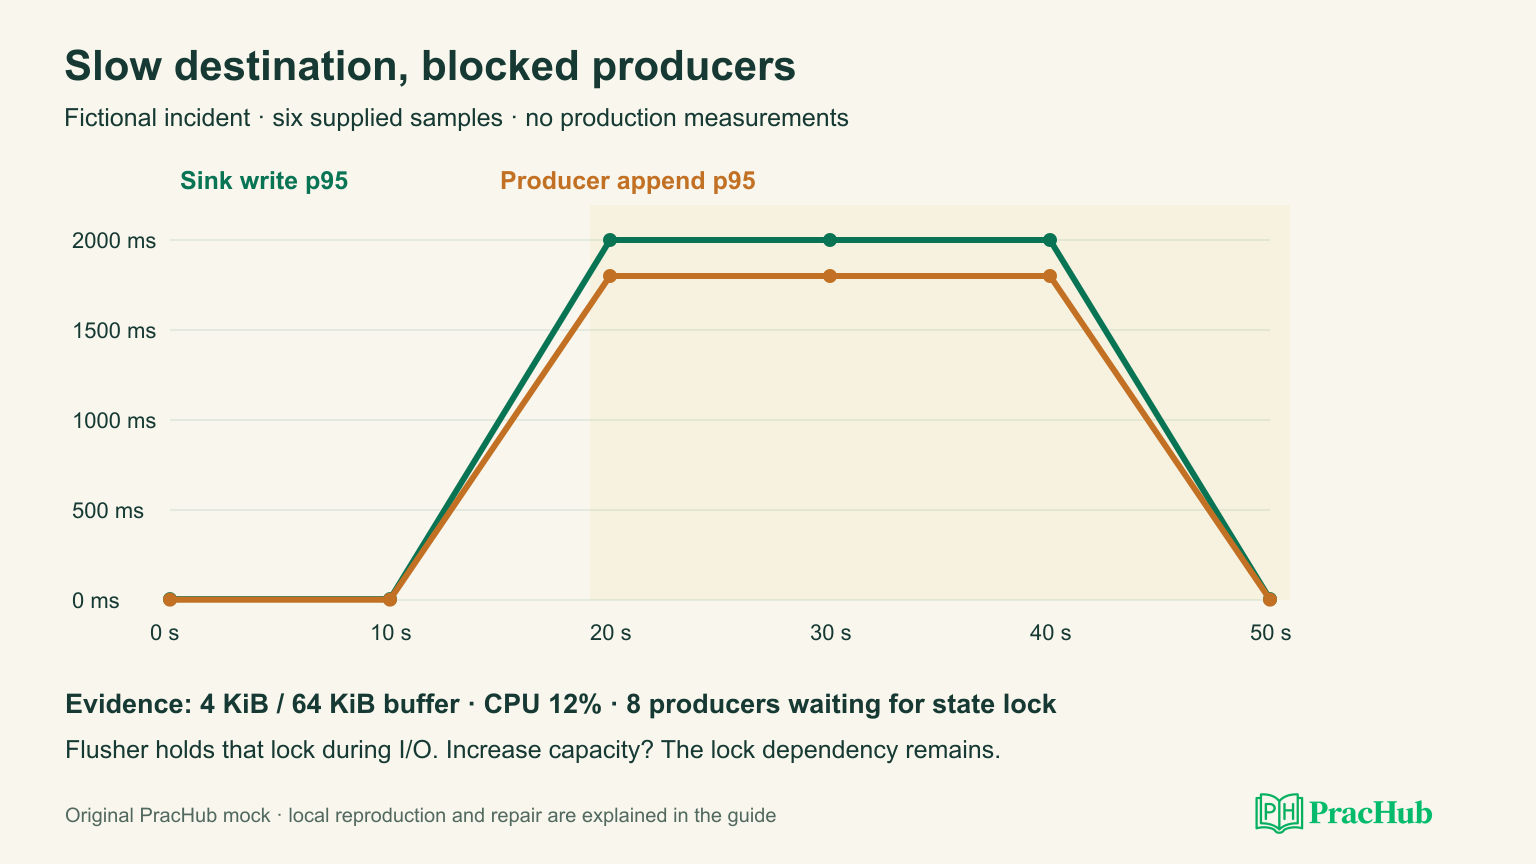
Supplied fictional evidence: the buffer contains 4 KiB against a 64 KiB cap. CPU is 12%. Eight producer threads are waiting for the writer's state lock. The flusher is inside a destination write while holding that lock. There is no evidence of a full buffer.
The graph uses six supplied samples, not measured Datadog telemetry. Sink-write latency rises from 5 ms to 2,000 ms; append latency rises from 2 ms to 1,800 ms during the same interval. Correlation suggests a shared bottleneck. The thread states identify the mechanism.
The faulty operation is small enough to inspect:
with self._state:
    batch = tuple(self._queue)
    self._sink(batch)        # destination I/O while holding the state lock
    self._queue.clear()
    self._bytes = 0
Every producer needs _state to append. A slow sink therefore blocks producers even with spare capacity. Low CPU is compatible with waiting; it does not prove the service is healthy. Increasing the byte cap leaves this lock dependency intact.
Start with the hypothesis, “Destination I/O is inside the producer critical section.” Check the thread dump and lock owner. Reproduce the issue with a controlled sink that signals when it starts and waits for release. Start a producer after that signal. The faulty version cannot complete the append until the sink returns. This isolates the lock dependency without treating a random sleep as proof of a race.
Repair the writer without losing new arrivals
This incident uses a separate contract from the linked C++ file-writer exercise, which forwards bytes when a threshold is reached. Here, the writer accepts nonempty immutable byte records, and a background caller invokes flush. Capacity counts every accepted byte, including records currently being flushed. A full buffer returns False; an oversized record is invalid. Successful sink return acknowledges the whole supplied batch. An exception leaves that batch queued.
A state lock protects the queue and byte count. A separate flush lock serializes destination calls. Producers never need the flush lock. Keeping the selected prefix in the queue until acknowledgement avoids prematurely freeing capacity.
from collections import deque
from threading import Lock

class BufferedWriter:
    def __init__(self, sink, capacity):
        if type(capacity) is not int or capacity <= 0:
            raise ValueError("capacity must be a positive integer")
        self._sink = sink
        self._capacity = capacity
        self._queue = deque()
        self._bytes = 0
        self._state = Lock()
        self._flush = Lock()

    def write(self, record):
        if type(record) is not bytes or not record:
            raise ValueError("record must be nonempty bytes")
        if len(record) > self._capacity:
            raise ValueError("record exceeds capacity")
        with self._state:
            if self._bytes + len(record) > self._capacity:
                return False
            self._queue.append(record)
            self._bytes += len(record)
            return True

    def flush(self):
        with self._flush:
            with self._state:
                batch = tuple(self._queue)
            if not batch:
                return 0
            self._sink(batch)
            with self._state:
                for record in batch:
                    assert self._queue.popleft() == record
                    self._bytes -= len(record)
            return len(batch)

    def pending_bytes(self):
        with self._state:
            return self._bytes
Suppose the queue initially contains alpha, five bytes. The flusher snapshots it and starts a slow sink call. A producer appends bravo, another five bytes, before the sink returns. Pending capacity remains ten bytes. On acknowledgement, the flusher removes only alpha; bravo stays queued for the next flush. Clearing the whole queue would silently discard the new record.
The local test suite passed 46 checks, including the blocked-producer reproduction, appending during destination I/O, exact-capacity acceptance, invalid records, retained batches after failure, two concurrent flushers, and 20 runs with concurrent producers. The repaired producer completed before the controlled sink was released; the faulty producer did not. These are local functional checks, not throughput measurements or a production load test.
Queue operations cost O(1) per append. A flush snapshots and removes O(n) records in that batch; sink work depends on the destination. The byte cap bounds payload bytes, while record objects, deque entries, and snapshot references add memory overhead. The snapshot shares immutable record objects rather than copying their payloads.
What does this code still fail to guarantee?
It is an in-memory writer. A crash can lose accepted records. A sink can commit a batch and then lose its response; retrying the retained batch can duplicate external effects. Normal return means acknowledgement under the supplied sink contract, not automatically an operating-system fsync or replicated durability guarantee.
Do not call this exactly-once delivery. To add stronger semantics, define stable record identities, destination deduplication or reconciliation, acknowledgement meaning, and persistence boundaries. Avoid callbacks that recursively call flush, because the flush lock is not reentrant. A production writer also needs deadlines, shutdown behavior, and a bounded batch policy.
Decide how the service should recover
Fixing the critical section removes one cause of latency. It cannot make a slow destination drain faster than incoming traffic. Define the overload decision separately.
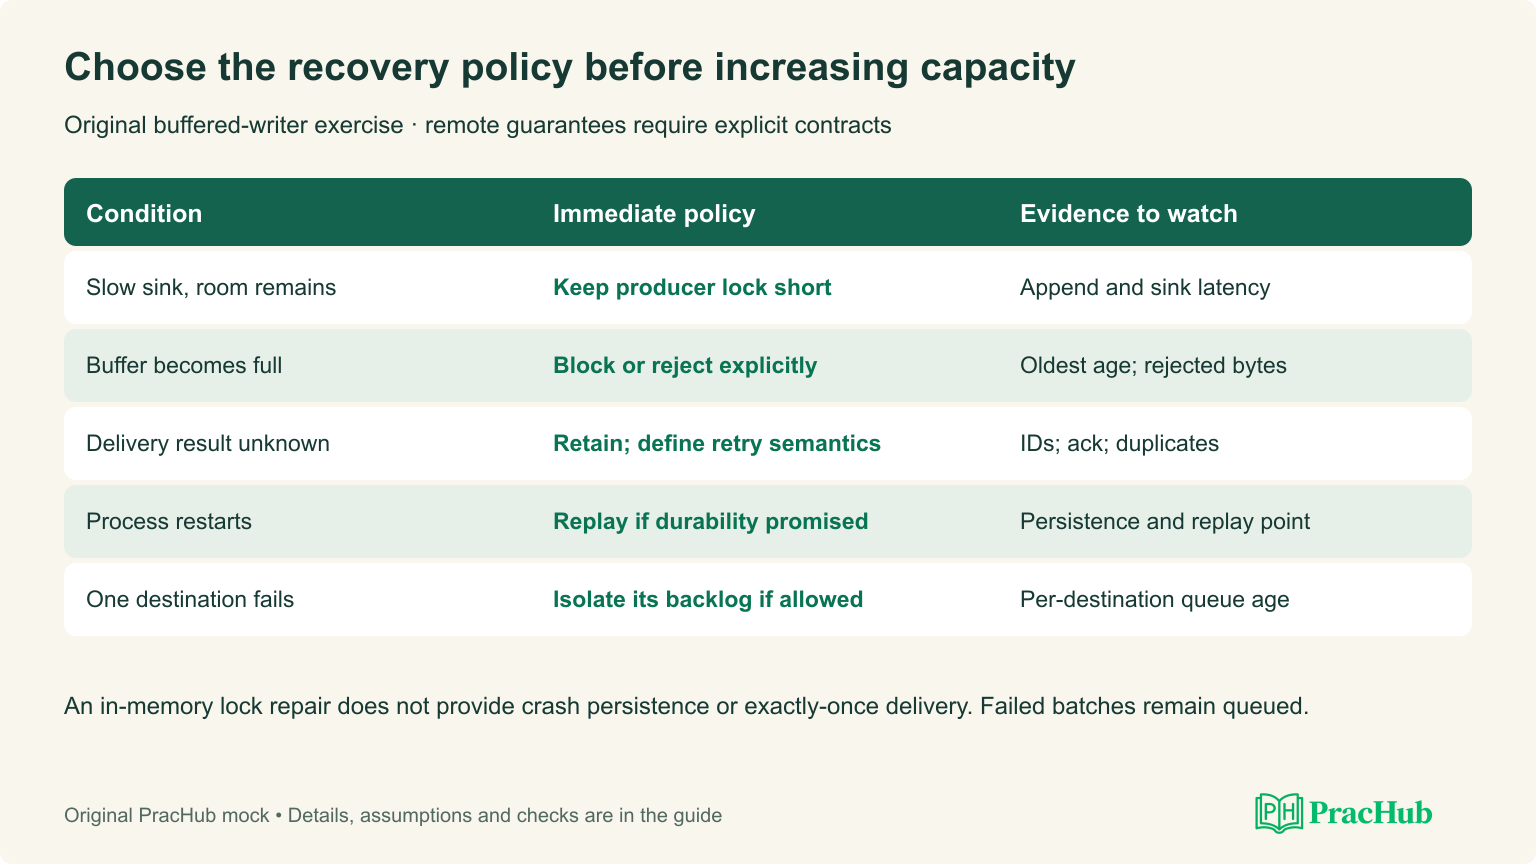
| Failure | Immediate decision | Evidence to watch |
|---|---|---|
| Sink slow, buffer has room | Keep producer lock short; bound sink duration | Append latency, lock wait, sink latency |
| Buffer full | Block upstream or reject/drop explicitly | Rejected bytes and oldest queued-record age |
| Sink outcome unknown | Retain records; retry only under defined delivery semantics | Stable identities, acknowledgements, duplicate handling |
| Process restart | Recover durable records if persistence was promised | Replay position and durable acknowledgement |
| One destination unavailable | Isolate its backlog where the contract allows | Per-destination backlog and healthy-route latency |
Datadog's Observability Pipelines documentation describes how full buffers can propagate backpressure upstream, how memory and disk buffering differ, and how destination behavior affects fan-out. A memory buffer is not restart persistence. Disk durability requires the appropriate persistent storage configuration.
For a fictional sizing exercise, assume arrivals of 10,000 records/s at an average 500 bytes: 5 MB/s of payload. A destination that stops draining for 30 seconds adds approximately 150 MB before metadata or replication overhead. If it recovers at 15,000 records/s while new traffic stays at 10,000, the net drain is 5,000 records/s; clearing the 300,000-record backlog takes about 60 seconds. The recovery rate matters as much as the outage length.
Explain whether rejection is acceptable, whether producers can tolerate blocking, and whether different tenants have separate budgets. A single unbounded retry loop can turn one failing destination into a wider incident.
Practice a log query with a precise answer
Use half-open time windows: include the start timestamp and exclude the end. For this original fixture, query service checkout during [12:00:00, 12:01:00):
| Timestamp | Service | Status | Duration |
|---|---|---|---|
| 12:00:00 | checkout | 200 | 20 ms |
| 12:00:15 | checkout | 500 | 900 ms |
| 12:00:40 | checkout | 200 | 80 ms |
| 12:00:50 | search | 500 | 700 ms |
| 12:01:00 | checkout | 500 | 1,200 ms |
The answer is three checkout records, one error, and an error proportion of 1/3. With the explicitly chosen nearest-rank definition, p95 is the largest of the three durations: 900 ms. The search error and the record at the upper boundary are excluded.
State the percentile definition and warn that three records provide weak statistical evidence. Do not combine averaged host percentiles into a supposed global percentile. Discuss timestamp parsing, malformed records, late arrivals, high-cardinality labels, and privacy before expanding the exercise into a streaming query processor.
Build a short week of preparation outputs
| Day | Work | Finished output |
|---|---|---|
| 1 | Confirm your loop; solve the log-query fixture | Recruiter questions, exact expected result, boundary tests |
| 2 | Implement a byte-bounded writer | Contract, FIFO tests, explicit rejection behavior |
| 3 | Reproduce the lock incident and repair it | Thread-state explanation and a regression check |
| 4 | Design ingestion under a destination outage | Capacity calculation, overload policy, recovery timeline |
| 5 | Rehearse a project and incident discussion | A concise opening plus technical follow-up notes |
| 6 | Run a mock matched to the confirmed stage | Working artifact and three observed weaknesses |
| 7 | Repair those weaknesses | A rerun showing what improved and what remains |
Use the mock to choose additional preparation time. There is no universal number of weeks that makes every candidate ready. Readiness means you can repeat the work, explain a failure, and respond to changed constraints without relying on a rehearsed answer.
For your project discussion, prepare a brief account of the service, your responsibility, the decision you made, and the result you actually measured. Then expand on alternatives, rollout, failure recovery, and collaboration. If you did not own a production incident, use an honest development or coursework example; do not invent on-call experience.
Sources and scope
Reviewed October 8, 2026. Recruiting instructions govern your actual assessment. The exercises and graphs are original practice material; no private question frequency or hiring outcome is claimed.
- Datadog candidate experience — public stages and in-person expectation.
- Datadog interview AI guidelines — permission differs by assessment type.
- Observability Pipelines buffering and backpressure — buffering and upstream flow control.
- Datadog engineering: reliable log delivery — published June 23, 2025; useful context for endpoint isolation and backlog recovery, rather than an interview specification.