Capgemini AI-Assisted Coding Assessment: Practice Debugging, Feature Changes, and Verification
Quick Overview
Practice a reported Capgemini AI-assisted variant by defining the contract yourself, requesting bounded changes and verifying both the fix and the new feature. The article includes Original buggy visible_tasks function and owner feature; Prompt-decision log and failing/passing regression evidence. It distinguishes official documentation, candidate accounts when available, and original preparation exercises.
An AI assistant can produce a plausible patch while leaving you with the same wrong output and less time to diagnose it. For a reported Capgemini AI-assisted coding assessment, prepare to define the behavior, explain the intended approach, inspect the code diff, and compare its output with the written contract. Prompt wording cannot replace that reasoning.
Official fact: Capgemini India's recruitment guidance describes coding or technical assessment among the possible fresher hiring stages. It does not establish one universal AI-assisted format, language, token budget, or feature-development task. Capgemini recruitment process
Recent candidate reports describe debugging and AI-assisted coding variants. This guide separates those accounts from official guidance and uses an original Python practice task. Before an assessment, start your practice with PracHub's How to prepare for AI-assisted coding interviews?, then use the example below to make your own decisions observable.
What do the recent reports actually support?
Candidate report, October 5, 2026: A poster writing as True-Faxx described a completed campus assessment with a debugging section and an on-screen coding assistant. The account emphasizes providing an approach, constraints, and required input/output behavior. The poster explicitly labels their reconstructed debugging code as a memory-based reconstruction. October 5 account
Candidate report, September 29, 2026: A different account, named_isme, described a syntax error in their debugging task and said they needed to supply the problem statement, approach, and desired output for the AI-assisted task. September 29 comment
These are independent usernames discussing the same broad recent period. Their identity, employer instructions, and membership in the same recruiting cohort are not independently established. A repost of the October 5 account would not count as a third independent report.
Preparation inference: Practice diagnosing a small failure and directing a bounded implementation change. Neither account establishes that every candidate receives feature development. We include it as a transfer exercise that checks whether a fix survives a changed requirement.
Use your invitation and assessment instructions for the permitted language and assistant. Availability of an on-screen assistant in one report does not establish permission to use an external assistant in your own assessment.
Define the original task before editing code
Our original practice task, not a reported Capgemini question, selects open tasks for a project. Every input record has a unique string ID, a project, a status, an integer priority, and an owner. Status is exactly open or closed, and project comparison is exact.
The initial interface is visible_tasks(tasks, project, limit). It must return only open tasks for the requested project, ordered by descending priority and then ascending ID. It must leave the input list's order unchanged.
A nonnegative integer limit caps the result. Zero returns an empty list; a negative limit raises ValueError. The returned records can share the original dictionaries because this contract requires preserving list order, not a deep copy of every record.
Use this fixture:
tasks = [
    {"id": "A1", "project": "P", "status": "open",
     "priority": 2, "owner": "Lea"},
    {"id": "A2", "project": "P", "status": "closed",
     "priority": 5, "owner": "Lea"},
    {"id": "B1", "project": "Q", "status": "open",
     "priority": 9, "owner": "Kai"},
    {"id": "A3", "project": "P", "status": "open",
     "priority": 2, "owner": "Kai"},
]
For project P and limit 10, predict IDs ["A1", "A3"]. A2 is closed and B1 belongs to Q. State that expected answer before reading the buggy function.
Reproduce the failure and separate its causes
Here is the deliberately faulty version:
def visible_tasks(tasks, project, limit):
    tasks.sort(key=lambda t: t["priority"], reverse=True)
    return [
        t for t in tasks
        if t["project"] == project or t["status"] == "open"
    ][:limit]
On the fixture, the returned IDs are ["B1", "A2", "A1", "A3"]. The predicate admits an open task from another project and a closed task from the requested project. Replacing or with and addresses that membership error.
There are two additional contract failures. Sorting modifies the caller's list order, and negative slicing does not enforce our negative-limit policy. Fixing the predicate alone would leave both problems.
Official language behavior: Python distinguishes in-place list.sort() from sorted(), which produces a new list. Sorting keys can express several ordering fields. Python sorting guide
Record each failing observation separately so the patch and regression checks address every contract failure: wrong membership, changed input order, and missing rejection for a negative limit. The record is more useful than saying “the function is broken,” because each observation leads to a specific change and regression check.
For the priority tie, use reversed input containing A3 before A1. The required ID order stays A1, A3. This tests the explicit tie rule instead of relying on the fixture's original order.
Ask for a bounded patch after choosing the approach
Original practice prompt:
Repair visible_tasks without changing its three-argument calling interface. Keep only records whose project matches and status is open. Return a new list sorted by (-priority, id). Reject a negative limit with ValueError; zero returns an empty list. Do not mutate the input list. Use only the standard library. Show the minimal function change and explain which behavior each change fixes.
The prompt includes the contract and approach you have already reasoned through. It avoids asking the assistant to redesign the task or invent an output format.
Inspect the response as a proposal. Check the predicate, list mutation, tie ordering, and limit behavior. If the assistant sorts before filtering, assess whether it still preserves the contract; if it changes the interface, reject that part of the proposal.
Do not accept an unsupported sentence such as “all edge cases are handled.” Ask which inputs were checked, then execute the relevant checks yourself in your practice environment.
Keep the scope of the change explicit. One concise request plus a targeted follow-up can make the reasoning easier to inspect than a long conversation that changes requirements without recording them.
Add one feature while preserving old callers
The next original requirement adds an optional owner filter. Existing three-argument calls must still work. An owner value filters by exact equality; None means no owner restriction.
For project P and owner Kai, expect only ["A3"]. For owner Lea, expect only ["A1"]. A missing owner should return an empty list. The other membership, ordering, limit, and input-preservation rules remain.
Here is the completed practice implementation:
def visible_tasks(tasks, project, limit, *, owner=None):
    if limit < 0:
        raise ValueError("limit must be nonnegative")
    selected = [
        t for t in tasks
        if t["project"] == project
        and t["status"] == "open"
        and (owner is None or t["owner"] == owner)
    ]
    ordered = sorted(
        selected, key=lambda t: (-t["priority"], t["id"])
    )
    return ordered[:limit]
This example assumes the defined input types and required record fields. It does not claim comprehensive validation of arbitrary dictionaries, mixed ID types, or malformed limits.
The keyword-only owner parameter preserves the earlier call shape while making the new option explicit. A positional fourth argument is outside this chosen contract. Explain that decision if a practice reviewer proposes a different interface.
Filtering before sorting limits the ordering work to eligible records. For n input records and m selected records, the reasoning is a linear filter followed by sorting m records. The complexity discussion is a code-level analysis; no runtime benchmark or Capgemini scoring rule is established.
Keep a prompt-decision log with evidence
Use this original log to preserve what you decided and how you checked it:
| Decision | Instruction or review action | Evidence required |
|---|---|---|
| Repair membership | Require project match and open status together | P returns A1 and A3 |
| Preserve caller data | Replace in-place sorting with a new sorted list | Input IDs remain in the original order |
| Define the boundary | Reject negative limit and retain zero behavior | Error for -1; empty result for 0 |
| Add the feature | Optional keyword owner, default None | Old call passes; owner Kai returns A3 |
| Resolve ties | Use descending priority, ascending ID | Reversed tie input still returns A1 then A3 |
This log documents an exercise; it does not establish that a particular Capgemini grader evaluates prompt quality separately. Its benefit is letting you explain the relationship between each requirement, code change, and observation.
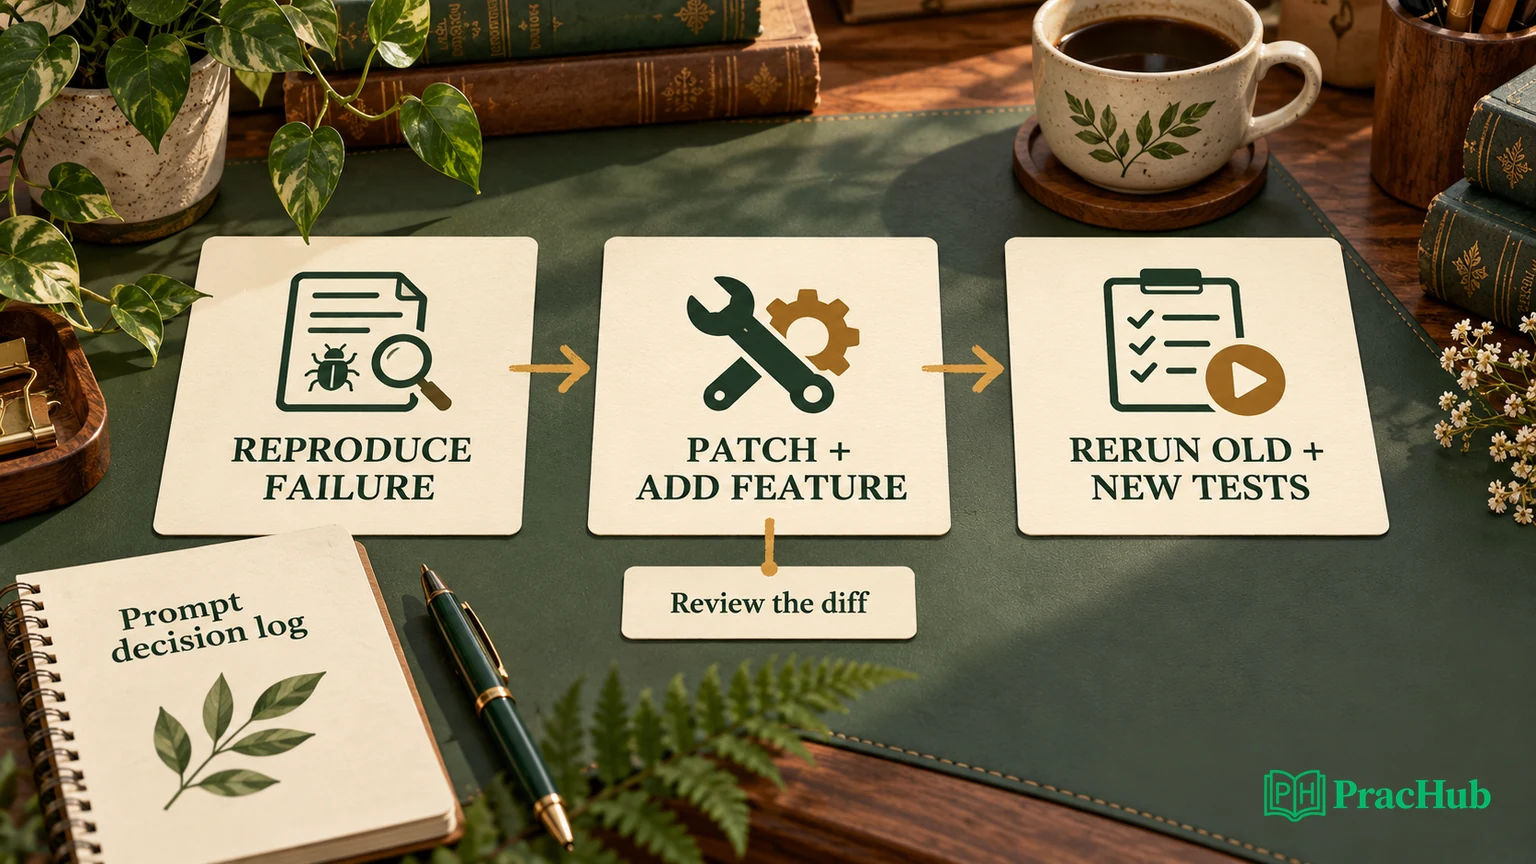
If you change a requirement during practice, record it. For example, case-insensitive owner matching changes expected outputs and should not be silently introduced as a “helpful” assistant improvement.
If the assistant supplies a new test, inspect the assertion. A test that simply compares the function with itself cannot establish correctness. Expected values should come from the written contract and fixture.
Verify old behavior and the new feature
The following checks make the exercise reproducible:
from copy import deepcopy

def ids(rows):
    return [row["id"] for row in rows]

sample = deepcopy(tasks)
before = deepcopy(sample)
assert ids(visible_tasks(sample, "P", 10)) == ["A1", "A3"]
assert sample == before
assert visible_tasks(sample, "P", 0) == []
assert ids(visible_tasks(sample, "P", 1)) == ["A1"]
assert ids(visible_tasks(sample, "P", 10, owner="Kai")) == ["A3"]
assert visible_tasks(sample, "P", 10, owner="Missing") == []
assert visible_tasks([], "P", 10) == []
assert ids(visible_tasks(list(reversed(sample)), "P", 10)) == ["A1", "A3"]

try:
    visible_tasks(sample, "P", -1)
except ValueError:
    pass
else:
    raise AssertionError("negative limit was accepted")
These checks cover the defined fixture and boundary changes. The accompanying local CPython checks reproduce the buggy output and verify the corrected fixture; they do not validate an assessment platform, a production service, or every possible input.
When a test fails, report the input, expected output, and actual output before making another edit. When the checks pass, review the final diff for unrelated changes and explain the remaining assumptions.
For the initial buggy version, isolate checks with fresh fixture copies. Otherwise, one in-place sort can contaminate later observations and obscure which assertion exposed the problem.
Rehearse a concise explanation of your change
Explain the failure in causal order: the permissive predicate admitted the wrong records, in-place sorting changed caller data, and negative slicing did not enforce the limit contract. Then explain how each part of the patch addresses its corresponding observation.
For the feature, state that owner filtering narrows eligible records before the existing ordering and limit behavior. Mention that old three-argument calls remain valid and show the regression evidence.
During preparation, vary one requirement at a time. Add a higher-priority open P task, use a limit larger than the number of matches, or reverse equal-priority inputs. Predict the result before running the check.
If your actual invitation supplies a different language or a repository task, transfer the same reasoning: locate the contract, reproduce the problem, choose a small change, inspect generated code, and verify it in the permitted environment.
Five questions for assisted debugging practice
These PracHub questions provide related AI-assisted coding, debugging, filtering, and prompt practice. They are not claimed as Capgemini assessment questions.
| PracHub question | Follow-up to rehearse |
|---|---|
| How to prepare for AI-assisted coding interviews? | Define what the assistant may change and how you will verify it. |
| Debug and extend an expense reimbursement reporting codebase with an AI coding assistant | Reproduce a bug, add one feature and rerun old behavior; this is adjacent practice. |
| How to debug a Python loop-condition bug | Give the failing input and explain the condition that changes. |
| Debug Failing Tests in a Django Movie Search and Filter API | Inspect filtering semantics and regressions in an existing codebase. |
| Choose best prompt for AI code debugging | Include constraints, approach and required output in a bounded prompt. |
Begin with How to prepare for AI-assisted coding interviews?. Bring one failure reproduction, a bounded change request, and a verification record to your practice session.
The goal is to explain what you asked the assistant to do and why the resulting code satisfies the stated requirements. Keep official instructions, candidate anecdotes, and your own practice choices distinct throughout that explanation.
Comments (0)