For an Oracle software engineer interview, prepare the job you are actually applying for. A database-engine role, a cloud control-plane service and an enterprise application can share coding fundamentals while needing different follow-up depth. Knowing that distinction is more useful than memorizing one supposed company-wide loop.
This guide turns the broad preparation map into three routes and one complete technical rehearsal. The transactional store, traces and review scenarios are original PracHub practice material, not proprietary Oracle questions or a reproduction of Oracle Database.
Establish the role before choosing the preparation route
Oracle’s software-engineering careers page describes work across cloud infrastructure, platform engineering and product development, with requirements varying by role. Its September 4, 2024 technical-interview article discusses core data structures, algorithms, complexity, coding and communicating a solution. Those are useful foundations; neither page establishes the same rounds, durations or difficulty for every opening.
Ask the recruiter for the team, level, technical focus, coding language/editor, design expectations and permitted tools. Confirm whether an assessment and project discussion are included. Treat any timeline as specific to that process. The question-bank stage labels and automatically generated preparation estimate on this page are organizational aids, not an official Oracle hiring schedule.
| Route suggested by the posting | Add depth in | Artifact to prepare |
|---|---|---|
| Database/storage engine | Version visibility, indexing, concurrency, memory and recovery | A concrete transaction trace and tested data structure |
| Cloud/platform service | API state, retries, leases, capacity and partial failure | An operation state machine with a recovery decision |
| Application/backend | Domain rules, SQL, validation, authorization and integration | A schema/API example with boundary tests |
These are editorial study routes, not Oracle’s internal job taxonomy. A posting can span more than one. A frontend-heavy role deserves browser, accessibility and state-management practice beyond this backend example. Do not stretch one exercise into evidence for every specialization.
For the project discussion, rehearse PracHub’s Oracle-tagged unfamiliar-problem and project deep-dive prompt. It asks about scope, personal contribution, trade-offs and measurable outcomes. The tag provides practice context, not a frequency estimate or a prediction of your interview.
Coding rehearsal: a small transactional key-value store
Contract: callers share one in-memory Store. Each transaction belongs to a single caller and begins at the current committed version. It reads that snapshot plus its own staged changes. A successful multi-key commit makes all staged changes visible together. If any point key it read or wrote changed after its snapshot, commit raises Conflict and publishes nothing.
Keys are nonempty strings of at most 100 characters. Values are integers from minus one billion through one billion; booleans, floats and None are rejected by put. None represents missing or deleted data. Delete creates a tombstone rather than removing change history. There is no range scan, SQL parser, networking or persistence.
First explain a broken solution: copy the latest dictionary at begin, then overwrite the live dictionary at commit. Two writers can read count 0, each calculate 1, and both report success while the final count remains 1. Adding a lock only around assignment prevents torn publication but does not detect that the second computation used stale data.
A single lock around the entire transaction would avoid that race but hold the lock while the caller thinks. This mock instead keeps committed versions and validates touched keys briefly at commit. It trades retained history and copying for straightforward snapshot visibility. It is a teaching implementation, not a production performance recommendation.
Complete Python implementation
from threading import RLock

class Conflict(Exception):
    pass

def key_ok(key):
    if type(key) is not str or not 1 <= len(key) <= 100:
        raise ValueError('key must be 1..100 characters')

class Store:
    def __init__(self):
        self.lock, self.version, self.history = RLock(), 0, {}

    def begin(self):
        with self.lock:
            return Txn(self, self.version)

class Txn:
    # Each transaction belongs to one caller; share Store, not Txn.
    def __init__(self, store, snapshot):
        self.store, self.snapshot = store, snapshot
        self.reads, self.writes, self.closed = set(), {}, False

    def active(self):
        if self.closed:
            raise RuntimeError('transaction is closed')

    def get(self, key):
        self.active()
        key_ok(key)
        if key in self.writes:
            return self.writes[key]
        self.reads.add(key)
        with self.store.lock:
            versions = self.store.history.get(key, ())
            lo, hi = 0, len(versions)
            while lo < hi:
                mid = (lo + hi) // 2
                if versions[mid][0] <= self.snapshot:
                    lo = mid + 1
                else:
                    hi = mid
            return versions[lo - 1][1] if lo else None

    def put(self, key, value):
        self.active()
        key_ok(key)
        if type(value) is not int or not -10**9 <= value <= 10**9:
            raise ValueError('value must be a bounded integer')
        self.writes[key] = value

    def delete(self, key):
        self.active()
        key_ok(key)
        self.writes[key] = None  # Tombstone retains the change version.

    def abort(self):
        self.active()
        self.closed = True

    def commit(self):
        self.active()
        with self.store.lock:
            self.closed = True
            for key in self.reads | self.writes.keys():
                versions = self.store.history.get(key, ())
                if versions and versions[-1][0] > self.snapshot:
                    raise Conflict(key)
            if not self.writes:
                return self.store.version
            version = self.store.version + 1
            prepared = dict(self.store.history)
            for key, value in self.writes.items():
                prepared[key] = prepared.get(key, ()) + ((version, value),)
            self.store.history = prepared
            self.store.version = version
            return version
The binary search returns the last key version at or before the snapshot. Reading a staged key returns the transaction’s own value. Immutable integers and tuples prevent a caller from mutating committed state through a returned object.
Commit validates the union of read and written point keys. Validating only writes would miss a decision based on a different key that changed meanwhile. Validation and publication use the same Store lock, so another commit cannot slip between them. The prepared dictionary and new version are installed while that lock is held; readers also acquire it.
Preparing a replacement dictionary keeps ordinary preparation errors from publishing a partly built write set. That is not crash durability. The process can lose every version on exit, and this code makes no power-loss, storage or replica guarantee. A transaction is consumed by commit, including a conflict; begin again before retrying.
Trace the version and conflict, not just the final value
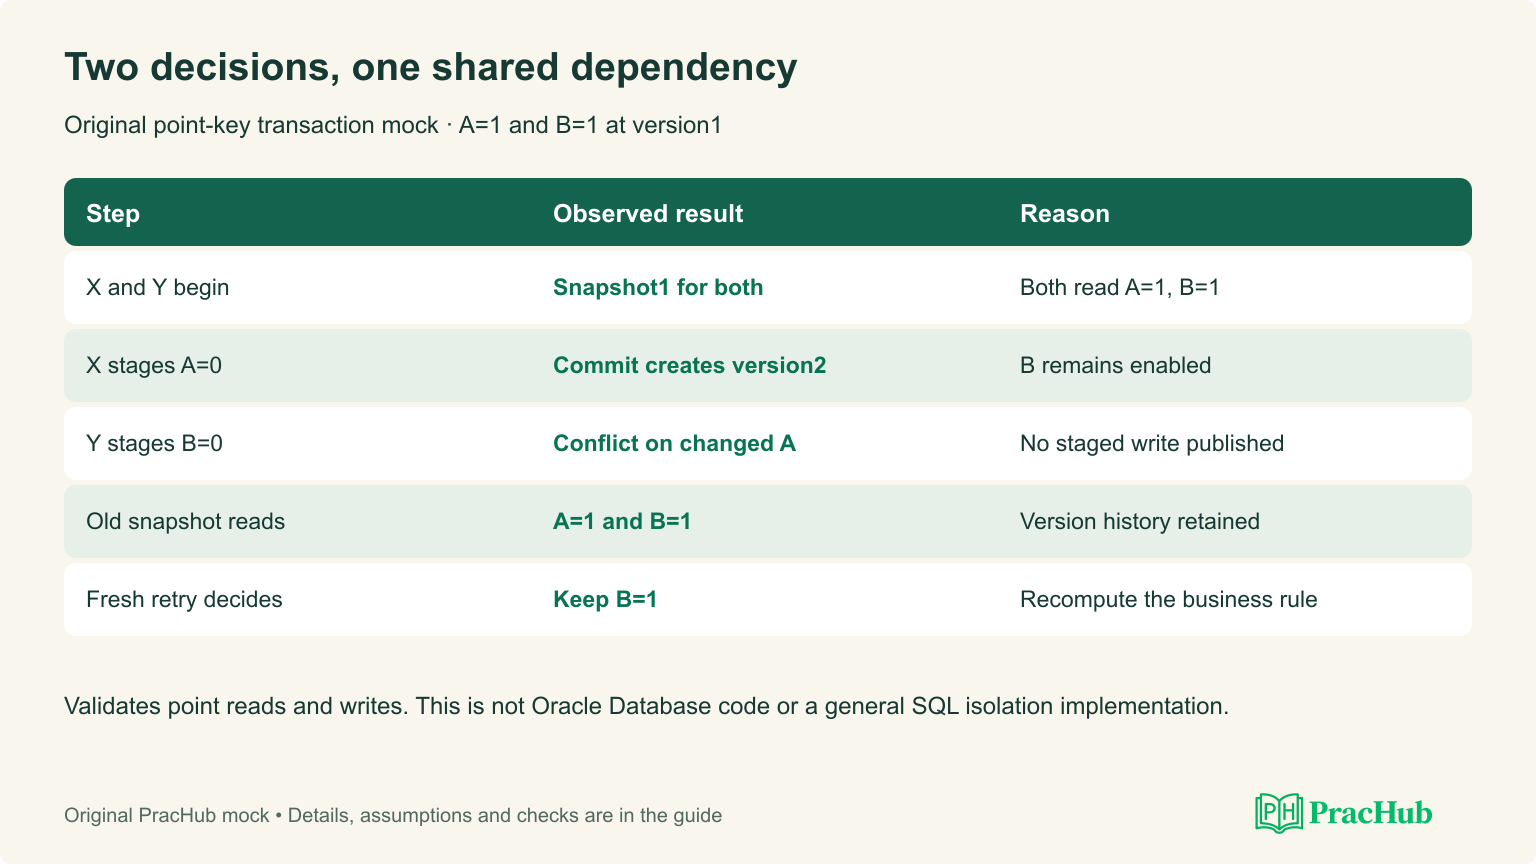
Start with A=1 and B=1 at version 1. Two transactions, X and Y, begin at version 1 and read both keys. The fictional rule is that at least one flag must remain enabled. X proposes A=0; Y proposes B=0.
| Step | Visible state or action | Why it matters |
|---|---|---|
| X reads A and B | Both are 1 in snapshot 1 | X bases its decision on both keys |
| Y reads A and B | Both are 1 in snapshot 1 | Y independently makes the same assumption |
| X commits A=0 | Version becomes 2; B remains 1 | One flag remains enabled |
| Y attempts commit B=0 | Conflict on A, changed after snapshot 1 | Y publishes nothing |
| New transaction retries Y’s decision | Reads A=0 and B=1 | It must keep B enabled to preserve the rule |
The retry is a business-decision replay, not merely a repeated put. If the caller blindly writes B=0 in a fresh transaction, the store cannot infer the unexpressed rule. Read the dependencies and recompute before deciding whether to write.
A transaction begun before X’s commit continues reading A=1 and B=1. A new transaction reads A=0 and B=1. This distinction is the point of retaining versions. The snapshot reader may later fail this mock’s conservative commit validation even when it made no writes; returning a consistent view and allowing every read-only commit are different promises.
Why a missing key still needs a change version
Transaction R reads missing X at version 0. Another transaction inserts X=7 at version 1, then a third deletes it at version 2. X looks absent again, but something changed after R’s snapshot. Keeping the deletion tombstone means R’s commit detects version 2 and conflicts.
Erasing the key and its history would make that insert-delete sequence invisible to validation. The problem resembles an ABA change: equal-looking values do not prove there was no intervening update. A per-key monotonic version answers a different question from value equality.
What was actually tested
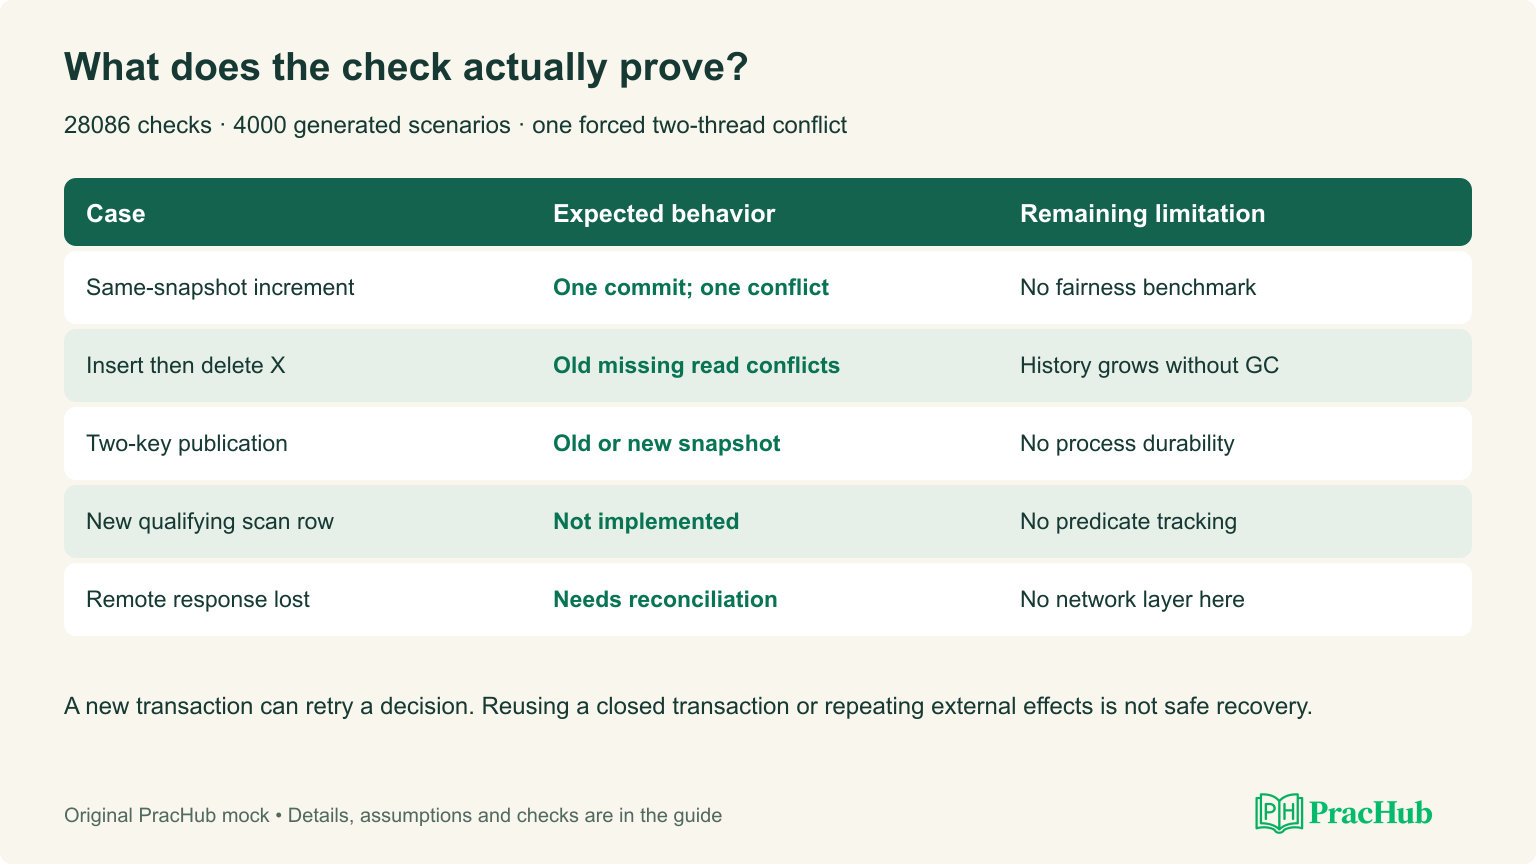
The local Python run passed 28086 checks, including 4000 generated transaction scenarios across 40 seeds. An independent dictionary snapshot and changed-key model predicts reads, successful commits and conflicts; after each scenario, all five test keys are compared with the expected live state. The oracle does not call the implementation’s binary-search or conflict helper.
Focused checks cover the two-flag conflict, an old snapshot after a newer commit, insert-delete history, rejected value types, an aborted write and operations on a closed transaction. Two actual threads synchronize after reading the same counter snapshot: one commits and one conflicts. A new transaction retries the increment and the final value is 2.
That thread result verifies a particular forced interleaving, not throughput or fairness. The generated cases exercise a bounded model; they do not prove arbitrary concurrent correctness. No Oracle server, disk failure, distributed replica or network timeout was exercised. State those limits before presenting the result as engineering evidence.
Complexity and the next design limit
For a key with h retained versions, a snapshot read uses O(log h) search. A commit checks r touched keys, copies the dictionary of k known keys and copies each written key’s history tuple. Its cost is O(r + k + the sum of touched history lengths), with additional memory for that prepared state. It is not O(1) because dictionary lookup alone is O(1) on average.
History grows without bound and deletion retains a tombstone. A real retention scheme would need the oldest active snapshot and a safe reclamation rule. Reclaim too early and a reader can no longer reconstruct its view; forget a relevant deletion version and conflict validation can miss a change. Describe that follow-up before optimizing the tuple append.
Connect the model to databases without conflating them
Oracle AI Database 26ai documentation distinguishes statement-level read consistency from transaction-level consistency. Under the default read committed level, the statement’s opening time determines its view. Under serializable or read-only transactions, the documented view is anchored to transaction start, with visibility of the transaction’s own changes. Its explanation uses undo data for consistent reads.
The Python mock always anchors point reads to begin and validates read keys as well as writes. It has a process lock and retained tuples, not Oracle’s block/undo and locking implementation. Do not call it an implementation of Oracle READ COMMITTED or Oracle SERIALIZABLE. Its point-key API has no predicate or range tracking, so it cannot support general SQL phantom-protection claims.
A useful interview follow-up is: “If I add scan(balance > 0), what new dependency must validation represent?” Checking only the keys returned by the first scan misses a newly inserted qualifying key. Possible designs include range/predicate tracking or a coarser collection version; both need an explicit correctness argument and contention trade-off. Neither is implemented here.
Extend the same discussion for cloud and application roles
For a cloud-service version, imagine a request starts a long-running provisioning operation. Separate the API acceptance record from the worker’s attempts. Define an operation ID, observable states, retry ownership and what a client should do after a timeout. This in-memory commit cannot prevent two external resources from being created: an external side effect is outside its lock and lifetime.
For an application version, imagine a transfer between accounts. Use integer minor units, a transaction that reads both balances, validates the business rules and stages both updates. Then ask about authorization, request deduplication and durable audit records. The teaching store lacks all three; using it as a financial service would require a different boundary and implementation.
For either route, distinguish a definite conflict from an uncertain remote outcome. Here Conflict proves staged writes were not published. A lost network response from a real service does not, by itself, prove failure. Reconciliation and idempotency are separate design tasks, not properties automatically supplied by a retry loop.
Prepare a project answer with evidence
Use a real project you can discuss without exposing confidential material. Start with the user problem and one constraint, then state your own contribution. Walk through one decision, an alternative you rejected and the check that informed the choice. End with the observed result and its limits.
For a rehearsal based on this mock, a precise statement would be: “Validating written keys alone missed a dependency on another flag. The point-read validation rejects that stale decision, and a forced two-thread counter test produced one commit and one conflict.” That is stronger than claiming the system is fully database-grade. For your real project, replace the mock with evidence you actually collected.
Expect questions such as: Which part did a teammate own? What result was measured versus estimated? What failure remains possible? What would change at ten times the data size? A credible answer can include uncertainty and a concrete next experiment. Do not borrow the local mock’s check count as your employment history.
A focused seven-session plan
- Route: annotate the posting, confirm format and identify the largest skill gap.
- Coding: solve one unfamiliar problem, explain complexity and test an empty, boundary and repeated-input case.
- Transactions: run the complete mock and manually predict both flag decisions before reading the trace.
- Failure: remove read-key validation in a local copy and construct the unsafe two-flag outcome; restore it and rerun.
- Design: explain a role-relevant service boundary, its durable state and an uncertain-outcome recovery path.
- Project: record a concise real project answer, then challenge one claim with evidence.
- Mock: combine a timed coding task and a design/project discussion; choose the next session from the actual miss.
This is a study sequence, not a hiring timeline or pass guarantee. Oracle’s January 2026 preparation article discusses AI practice tools; it does not authorize their use in a live assessment. Confirm the rules for your invitation and practice explaining any assisted change independently.
Sources and scope
Checked October 9, 2026. The following official sources support the company and database context; the exercise and preparation plan are original editorial material.
- Oracle software-engineering careers — role breadth and variable requirements.
- Oracle: Ace your technical interview — September 2024 fundamentals, coding, testing and communication advice.
- Oracle AI Database 26ai: Data Concurrency and Consistency — read-consistency and isolation context, distinct from the Python model.
- Oracle: Top tips to prepare for an interview — January 2026 preparation context, not live-tool permission.