Google Software Engineer Interview Prep Guide
Everything Google actually asks Software Engineer candidates — concept walkthroughs, worked examples, and the real interview questions, drawn from candidate reports. Free to read.
Last updated
Focus most on timed Karat-style coding for tomorrow: core arrays/hash maps, graph traversal, DP, intervals, heaps, and clear problem-solving narration, plus behavioral stories where your ratings are mostly new or shaky. There are no strong solved-history signals to justify skipping areas; large-input/log-processing is the lightest review because it was not explicitly selected. For Google, the highlighted concepts are distributed storage/messaging consistency, idempotency/delivery semantics, and leadership/ownership signals; for OnePay, the addendum adds payment-ledger data modeling. With less than a week—and a Karat interview tomorrow—treat this as a 3-hour crash plan: Technical Screen first, then Online Assessment patterns, then only high-yield onsite review.
Technical Screen — 81 min
Coding & Algorithms
-
Karat Technical Screen Execution and Communication (Focus) — covered in depth under Online Assessment below.
-
Core Array, String, Hash Map, Sliding Window, and Binary Search Patterns (Focus) — covered in depth under Online Assessment below.
-
BFS/DFS Graph and Tree Traversal and Shortest Paths (Focus) — covered in depth under Onsite below.
-
Dynamic Programming and State-Space Optimization (Focus) — covered in depth under Online Assessment below.
-
Intervals, Line Sweep, and Difference Arrays (Focus) — covered in depth under Onsite below.
-
Heaps, Streaming Median, and Top-K Selection (Focus) — covered in depth under Onsite below.
-
Trie and Prefix Indexing (Focus) — covered in depth under Onsite below.
System Design
-
Payment Ledger Data Modeling and Money Movement Invariants (Focus) — covered in depth under Onsite below.
-
Idempotency, Deduplication, and Delivery Semantics (Focus) — covered in depth under Onsite below.
-
Secure Distributed Storage, Messaging, and Consistency (Focus) — covered in depth under Onsite below.
Behavioral & Leadership
- Behavioral Leadership, Ownership, and Stakeholder Management (Focus) — covered in depth under Onsite below.
Software Engineering Fundamentals
-
Reliability, Observability, and Incident Diagnostics (Focus) — covered in depth under Onsite below.
-
Concurrency, Scheduling, and State Machines (Focus) — covered in depth under Online Assessment below.
Onsite — 75 min
Coding & Algorithms
- Core Array, String, Hash Map, Sliding Window, and Binary Search Patterns (Focus) — covered in depth under Online Assessment below.
Focus area — Graph/tree traversal is high-frequency for Google and Karat; your coding rating and solved history show this needs priority.
What's being tested
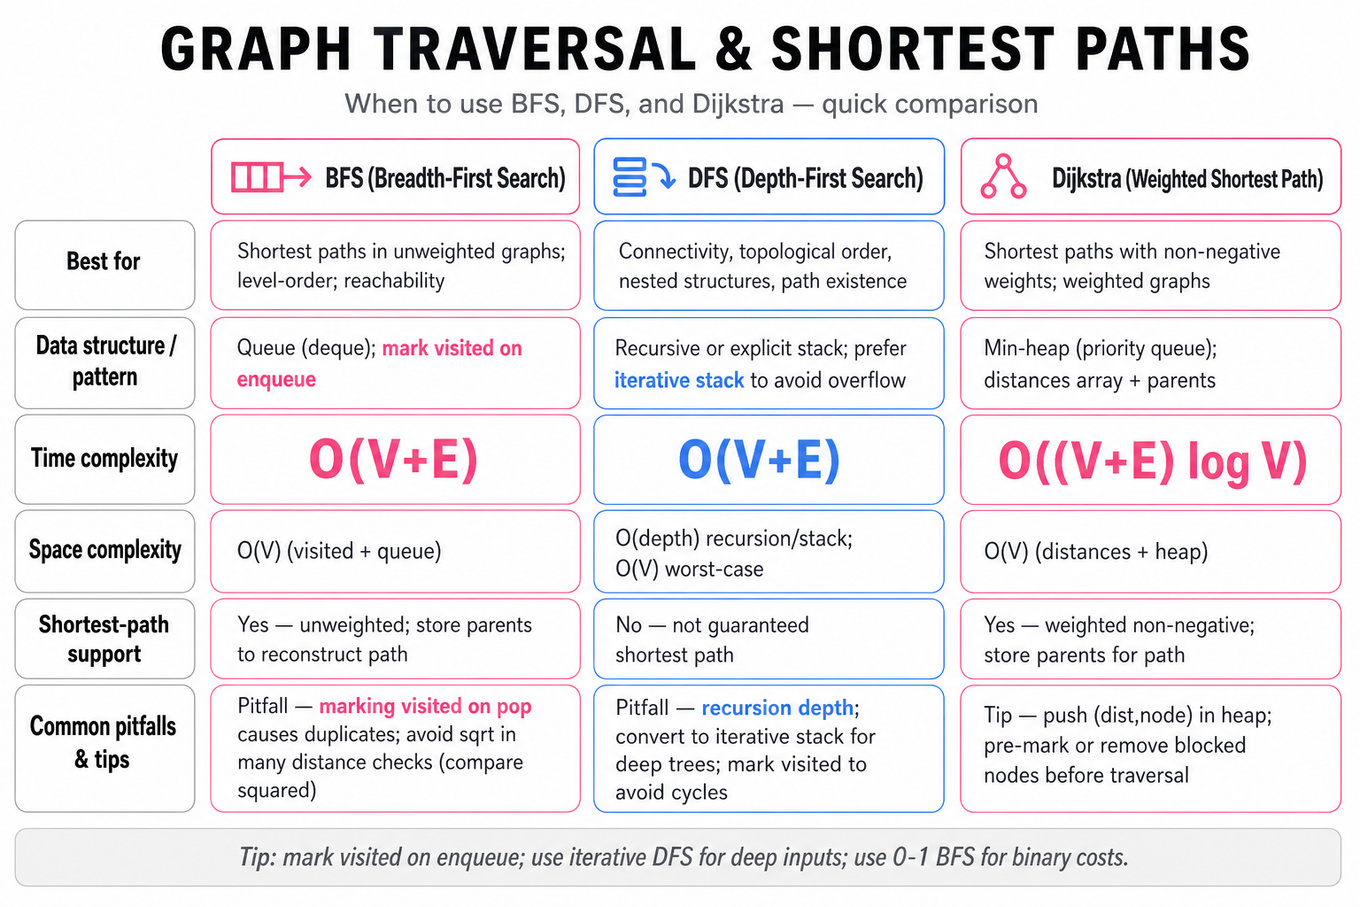
Candidates must demonstrate correct use of BFS and DFS for traversal, reachability, and component counting, plus shortest-path techniques (unweighted BFS, Dijkstra) under constraints. Interviewers probe algorithmic tradeoffs (time/space), correctness with blocked/forbidden nodes, and iterative vs recursive implementations to avoid stack overflow.
Patterns & templates
-
BFS for shortest paths in unweighted graphs — use
dequequeue, mark visited on enqueue, time O(V+E), space O(V). -
DFS (recursive or explicit stack) for connectivity and nested structures; prefer iterative stack to avoid recursion depth issues.
-
Dijkstra with
heapqfor weighted shortest paths; complexity O((V+E) log V); store distances and parents for path reconstruction. -
Multi-criteria shortest path: encode tuple cost (danger_count, steps) and use lexicographic comparison in priority queue or use 0-1 BFS for binary costs.
-
Remove/ignore blocked nodes by pre-marking in
setor deleting adjacency entries before traversal. -
Connected clusters (geometric): build adjacency by threshold distance squared to avoid
sqrt, deduplicate coordinates with aset, then BFS/DFS for components. -
Deleting in a binary search tree: handle leaf, single-child, two-children cases — replace with inorder successor (min in right subtree) and adjust pointers.
Common pitfalls
Pitfall: Marking visited only on pop instead of on enqueue causes duplicate enqueues and exponential blowup on dense graphs.
Pitfall: Using
sqrtfor many distance checks costs CPU and risks floating error — compare squared distances instead.
Pitfall: Recursing on deeply nested lists/trees without converting to an iterative stack risks stack overflow on large inputs.
Practice these
The practice cards below cover the canonical variants — solve all of them and time yourself.
Practice questions
- Dynamic Programming and State-Space Optimization (Focus) — covered in depth under Online Assessment below.
Focus area — Intervals test boundary discipline and tie handling; with coding rated 1/5, this needs deliberate practice before tomorrow.
What's being tested
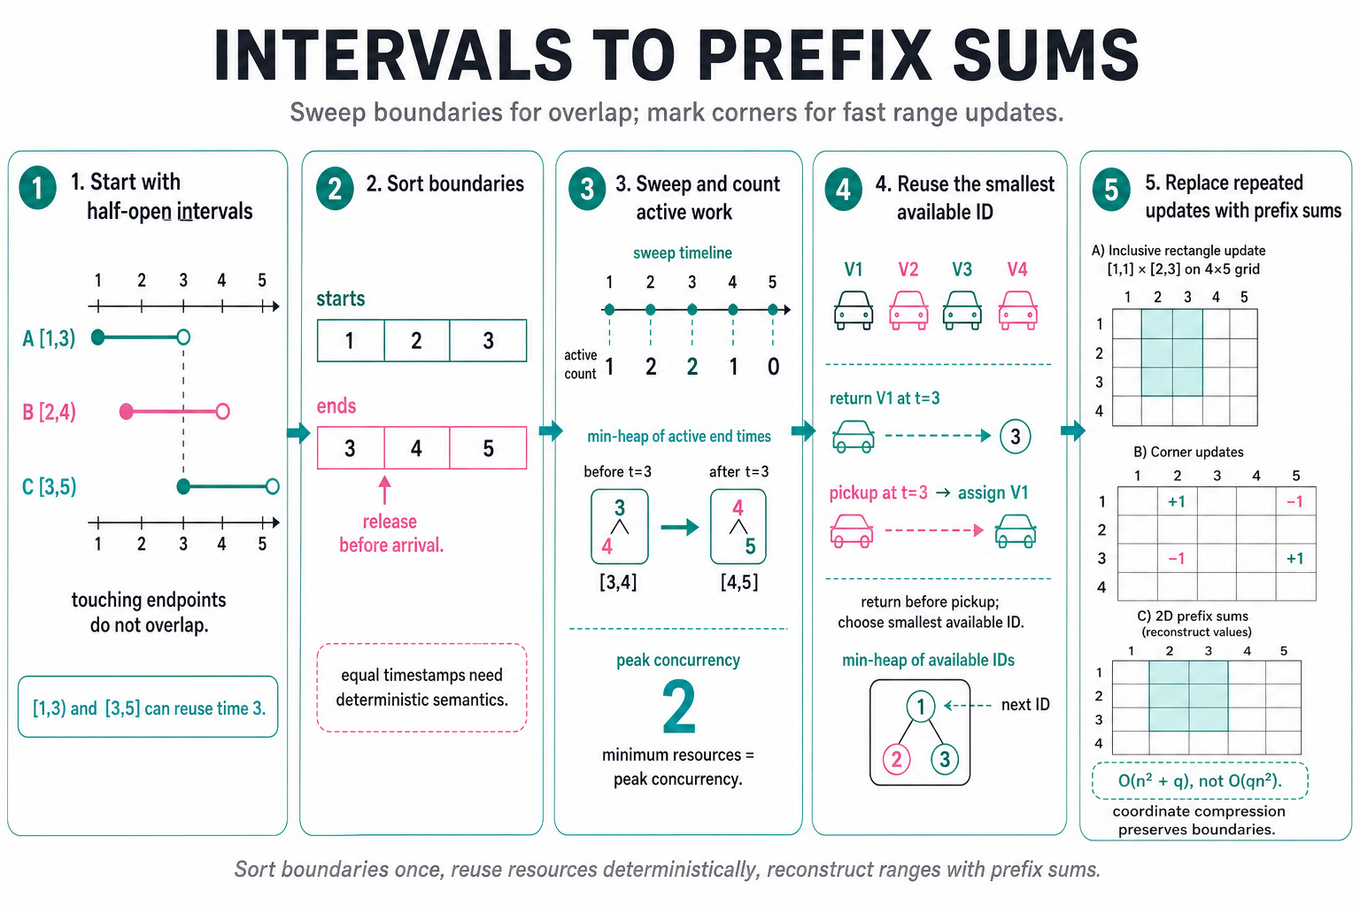
These problems test interval scheduling, line sweep, and difference arrays for detecting overlaps, allocating the minimum resources, and applying many range updates efficiently. You must demonstrate precise endpoint semantics, deterministic tie-breaking, and the ability to replace repeated simulation with sorting or prefix-sum reconstruction.
Patterns & templates
-
Half-open intervals
[start, end)overlap iffmax(starts) < min(ends); touching endpoints such as[1,3)and[3,5)do not conflict. -
Line sweep: sort starts and ends, process equal timestamps according to semantics; release resources before assigning arrivals for reusable half-open intervals.
-
Minimum resources: sort intervals by start time and maintain a min-heap of active end times; heap size is peak concurrency, with
O(n log n)time. -
Deterministic assignment: keep reusable vehicle IDs in a min-heap; assign the smallest available ID, while returning vehicles before processing same-time pickups.
-
Grouped recurring jobs: merge or union intervals by job identifier before capacity counting when repeated occurrences represent one logical resource requirement.
-
2D difference array: for inclusive rectangle
[r1,r2] × [c1,c2], update four corners, then take 2D prefix sums; total work isO(n² + q). -
Coordinate compression maps sparse endpoints to ranks, reducing memory from grid or time range size to
O(n + q); preserve interval boundaries carefully.
Common pitfalls
Pitfall: Treating inclusive and half-open endpoints interchangeably creates false conflicts or misses reuse at an exact return/pickup time.
Pitfall: Simulating every cell for every rectangle costs
O(qn²); mark boundaries once and reconstruct with prefix sums.
Pitfall: Ignoring stable tie-breaking can produce a numerically correct fleet size but an incorrect vehicle assignment.
Practice these
The practice cards below cover the canonical variants — solve all of them and time yourself.
Practice questions
Focus area — Coding is rated 1/5 and Karat screens favor implementable data-structure patterns like top-K, running median, and priority queues.
What's being tested
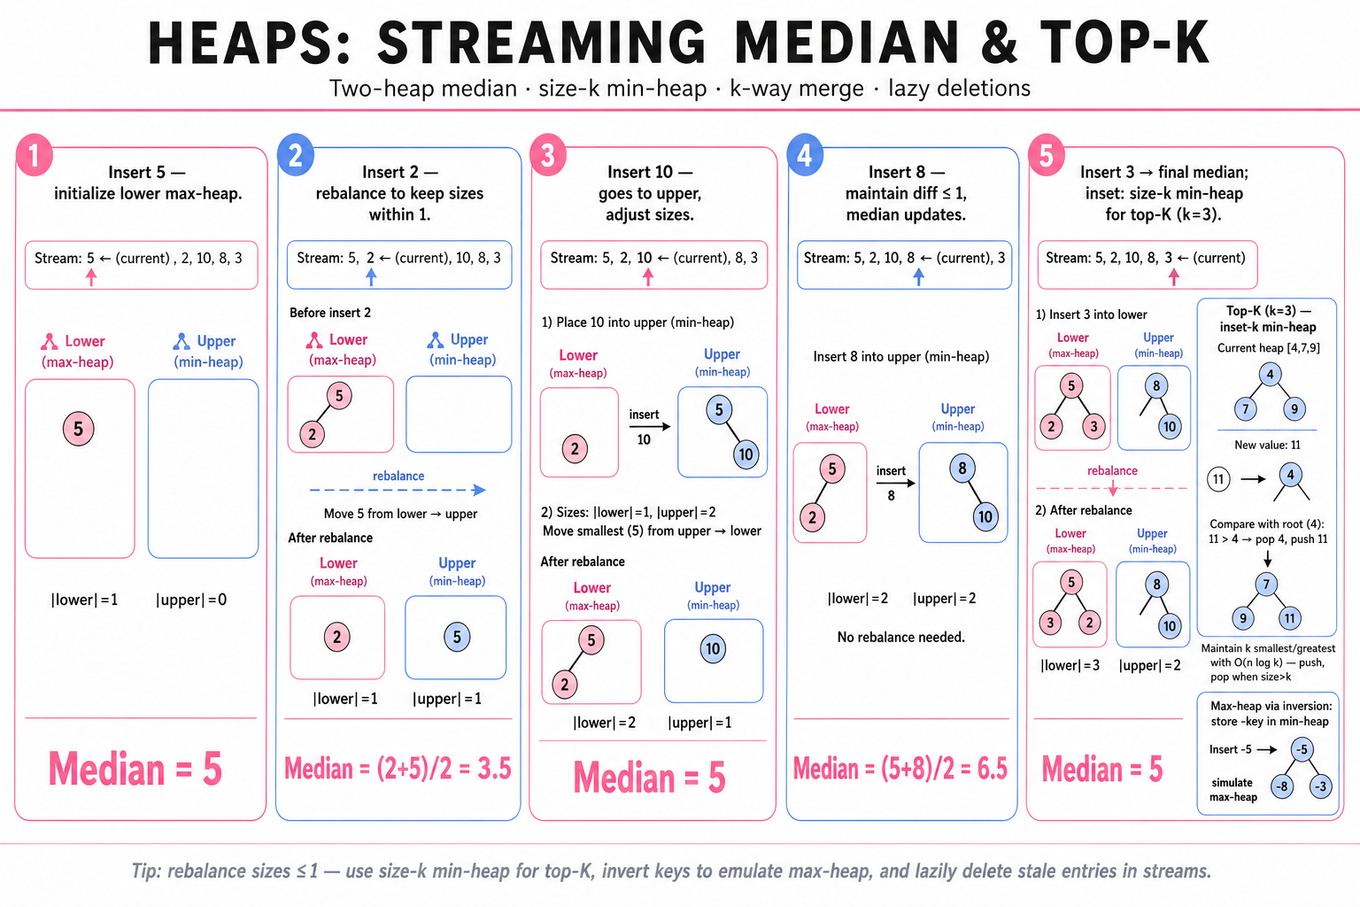
These problems test efficient use of heaps/priority queues and streaming order-statistics to maintain small summaries of large inputs (medians, k-th, top-k). Interviewers probe algorithmic reductions (k-way merge, two-heap median), complexity tradeoffs, and robust handling of duplicates and ties.
Patterns & templates
-
Two-heap median: keep a max-heap for lower half and min-heap for upper half; rebalance sizes to differ ≤1;
O(log n)per insert. -
Min-heap size-k for top-k: push items, pop when size > k; overall
O(n log k)time,O(k)space. -
Max-heap via inversion: if only min-heap available (e.g.,
heapq), insert negated keys to simulate a max-heap. -
K-way merge for k smallest pairs: push initial pairs (i,0), pop smallest, then push (i,j+1); avoid duplicate exploration with indices.
-
Frequency + heap for top-k words: count with
hashmap, then maintain min-heap of(freq, word)with tie-break deterministic ordering,O(n + m log k). -
Lazy deletions for streams: mark removed elements in a hashmap and lazily pop stale heap entries to handle deletions efficiently.
Common pitfalls
Pitfall: Forgetting to rebalance the two heaps correctly — median becomes incorrect by one position after several inserts.
Pitfall: Using full sort instead of size-k heap when k << n, causing unnecessary
O(n log n)work.
Pitfall: Not encoding tie-breakers in heap keys (e.g.,
(freq, word)), producing non-deterministic or wrong ordering.
The practice cards below cover the canonical variants — solve all of them and time yourself.
Practice questions
Trie and Prefix Indexing
Focus areaFocus area — Low coding confidence and no solved-history; tries are less universal than arrays but common in Google prefix/autocomplete prompts.
What's being tested
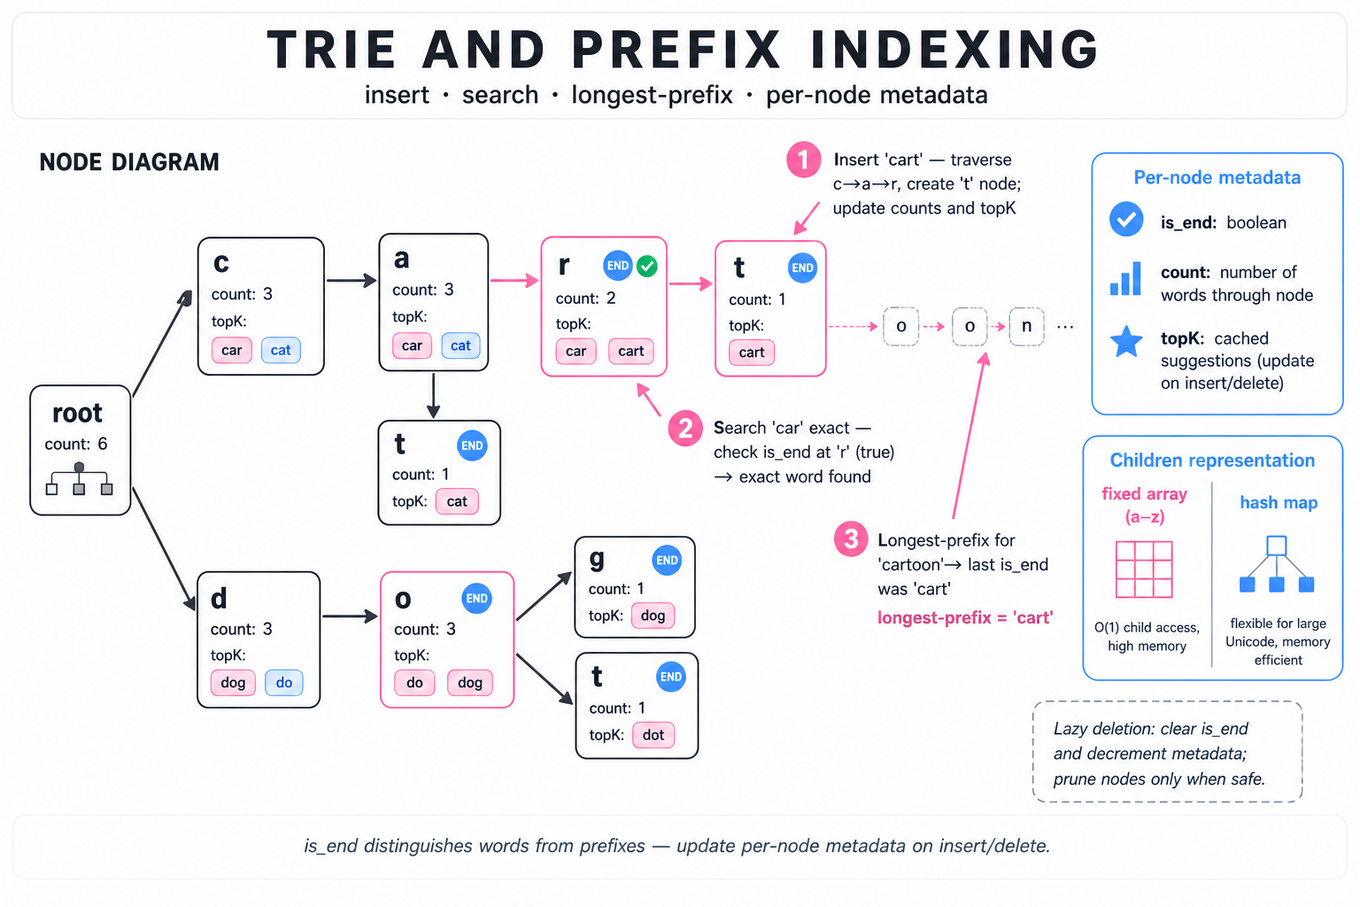
Tests construction and use of a Trie (prefix tree) for efficient prefix indexing, exact-word lookup, and longest-prefix matching. Interviewers probe correctness (terminal vs. prefix), per-node metadata for fast top-K or frequency-aware queries, and time/space complexity tradeoffs.
Patterns & templates
-
insert/search— traverse nodes per character, create child nodes as needed; O(L) time, O(1) extra space beyond nodes, where L is word length. -
Terminal flag vs. prefix — store
is_endboolean and optionally an exact-word payload to distinguish words from mere prefixes. -
Per-node metadata — keep
count,freq, ortopKlist at nodes to answer aggregate queries in O(L + K) time. Update these duringinsert/delete. -
Children representation — use hash map for variable alphabet or fixed array for small alphabets; memory ~O(total_chars) nodes × child-pointer-size.
-
Lazy deletion — clear
is_endand decrement metadata; prune nodes only when safe to avoid expensive recursive deletes. -
Longest-match replacement — greedy scan: advance as long as matching child exists and track last
is_end; overall O(N + M) for text size N and average match M per start. -
Collect/top-K traversal — DFS from prefix node, early-stop with maintained heap for K best; complexity O(nodes_in_subtrie + K log K).
Common pitfalls
Pitfall: Treating every node with children as a word—forgetting to check
is_endleads to false positives for exact search.
Pitfall: Failing to update per-node
topKon deletes/updates, causing stale suggestions.
Pitfall: Assuming constant alphabet; using fixed arrays for large Unicode input wastes memory.
Practice these
The practice cards below cover the canonical variants — solve all of them and time yourself.
Practice questions
System Design
Focus area — OnePay is payment-oriented; model accounts, ledger entries, idempotency keys, and invariants so API/data-model answers feel domain-aware.
What's being tested
This topic tests whether you can model money as an auditable, immutable history rather than as a mutable balance field. The interviewer is probing your understanding of double-entry accounting, idempotency, transaction boundaries, retries, and invariants that must remain true during concurrent or partially failed operations. Google cares because payment-like systems combine correctness, durability, and distributed-systems failure modes: a small modeling error can create duplicated funds, lost funds, or an audit trail that cannot explain what happened.
Core knowledge
-
Double-entry bookkeeping represents every movement with balanced postings: total debits equal total credits. For every journal entry, ; never create money by updating only a sender or recipient balance.
-
Model an immutable journal entry with an
entry_id, operation or transfer ID, creation time, currency, and one or more ledger postings. Each posting identifies an account, direction, amount, and currency; corrections append reversing entries rather than mutating history. -
Store amounts as integer minor units—for example, cents—not floating-point values. Enforce
amount > 0, a supported currency, and currency-specific scale;USD 10.25becomes1025, while zero-decimal currencies require different validation. -
Separate the ledger of record from a materialized balance. The ledger is authoritative and append-only; balances are cached projections that can be rebuilt by summing postings. This makes corruption detectable and supports audit, replay, and backfills.
-
Use a client-supplied idempotency key scoped to the operation and authenticated caller. Persist the key with the normalized request and final result; a retry returns the original result, while reuse with different parameters fails rather than creating another transfer.
-
Define explicit money-movement states, such as
PENDING,POSTED,FAILED, andREVERSED. A payment authorization, capture, settlement, refund, and chargeback are distinct business events; do not overload one status to represent all of them. -
Make the posting transaction atomic in a storage system such as
Spanner,Postgres, or another strongly consistent database: validate accounts and currency, insert the journal entry and postings, and update any balance projection in one commit. -
State invariants precisely: postings for one committed transfer balance to zero; account balances equal opening balance plus posted signed postings; a transfer cannot be posted twice; and no account may become negative unless overdraft is explicitly supported.
-
Handle concurrency with serializable transactions, conditional writes, or per-account version checks. A check-then-update sequence under weaker isolation can allow two withdrawals to observe the same balance and both succeed.
-
Treat external effects separately from ledger commits. Use an outbox pattern to publish a durable “transfer posted” event after the database transaction; consumers must also be idempotent because delivery can be duplicated.
-
Design reconciliation as an independent correctness boundary. Compare internal postings with processor settlement files or bank statements using stable external IDs, then represent discrepancies as explicit cases or correcting entries—not silent balance edits.
-
Decide what “atomic” means across system boundaries. Internal accounts can commit atomically, but a bank or card network cannot join your transaction; use a saga, compensating reversal, and durable state transitions for failures after external submission.
Worked example — Payment Ledger Data Modeling and Money Movement Invariants
I would first clarify whether the prompt asks for an internal wallet transfer, card payment, or settlement flow, and whether pending funds, fees, multiple currencies, and overdrafts are required. I would declare that amounts are integer minor units, the ledger is append-only, and a successful transfer must produce balanced postings in one strongly consistent transaction. I would organize the answer around four pillars: the account and posting schema, the transfer state machine, idempotent request handling, and invariant enforcement plus reconciliation. For a wallet transfer, I might create a journal entry with debit and credit postings, reserve or validate available funds, commit the entry, and derive balances from the ledger or a verified projection. I would explicitly choose serializable isolation or optimistic version checks to prevent concurrent withdrawals from violating the nonnegative-balance rule. I would also flag that publishing notifications is not part of the database transaction, so an outbox and idempotent consumers are needed. I would close by saying that, with more time, I would specify retention, audit access, disaster recovery, multi-region consistency, and reconciliation workflows.
A second angle
The same model applies differently to a card payment, where authorization may place a hold before capture creates final ledger postings. The key distinction is that a processor timeout does not prove failure, so retries require an idempotency key and lookup by the processor’s external reference. A strong design separates authorization, capture, refund, and chargeback events instead of treating them as balance updates. It also models fees and currency conversion explicitly so the merchant, customer, processor, and fee accounts remain balanced.
Common pitfalls
Pitfall: Treating
balanceas the source of truth and updating sender and recipient rows independently can lose money when one write succeeds and the other fails. Use an immutable balanced journal and derive or verify projections.
Pitfall: Saying “use a unique idempotency key” without defining its scope, stored response, parameter mismatch behavior, and lifecycle leaves retries underspecified. Explain what happens when the first request is still processing or the client retries after a timeout.
Pitfall: Claiming a distributed transaction makes a bank transfer atomic overstates the guarantee. Distinguish atomic internal posting from asynchronous external movement, then describe durable states, reconciliation, and compensating reversals.
Connections
An interviewer may pivot to distributed transactions, serializability, and the outbox pattern, or ask how to design replayable event consumers. Be ready to connect this model to event sourcing, reconciliation, fraud holds, multi-currency exchange, and disaster recovery without weakening the core invariants.
Further reading
-
Martin Fowler, “Accounting Patterns” — a practical treatment of immutable accounting entries, balances, and corrections.
-
Stripe, “Idempotent requests” — concrete guidance on safely retrying payment API operations.
-
Martin Kleppmann, Designing Data-Intensive Applications — strong coverage of consistency, transactions, logs, and reliable event delivery.
Practice questions
Focus area — OnePay/payment contexts often probe retries and duplicate requests; this base concept covers that angle without adding a duplicate.
What's being tested
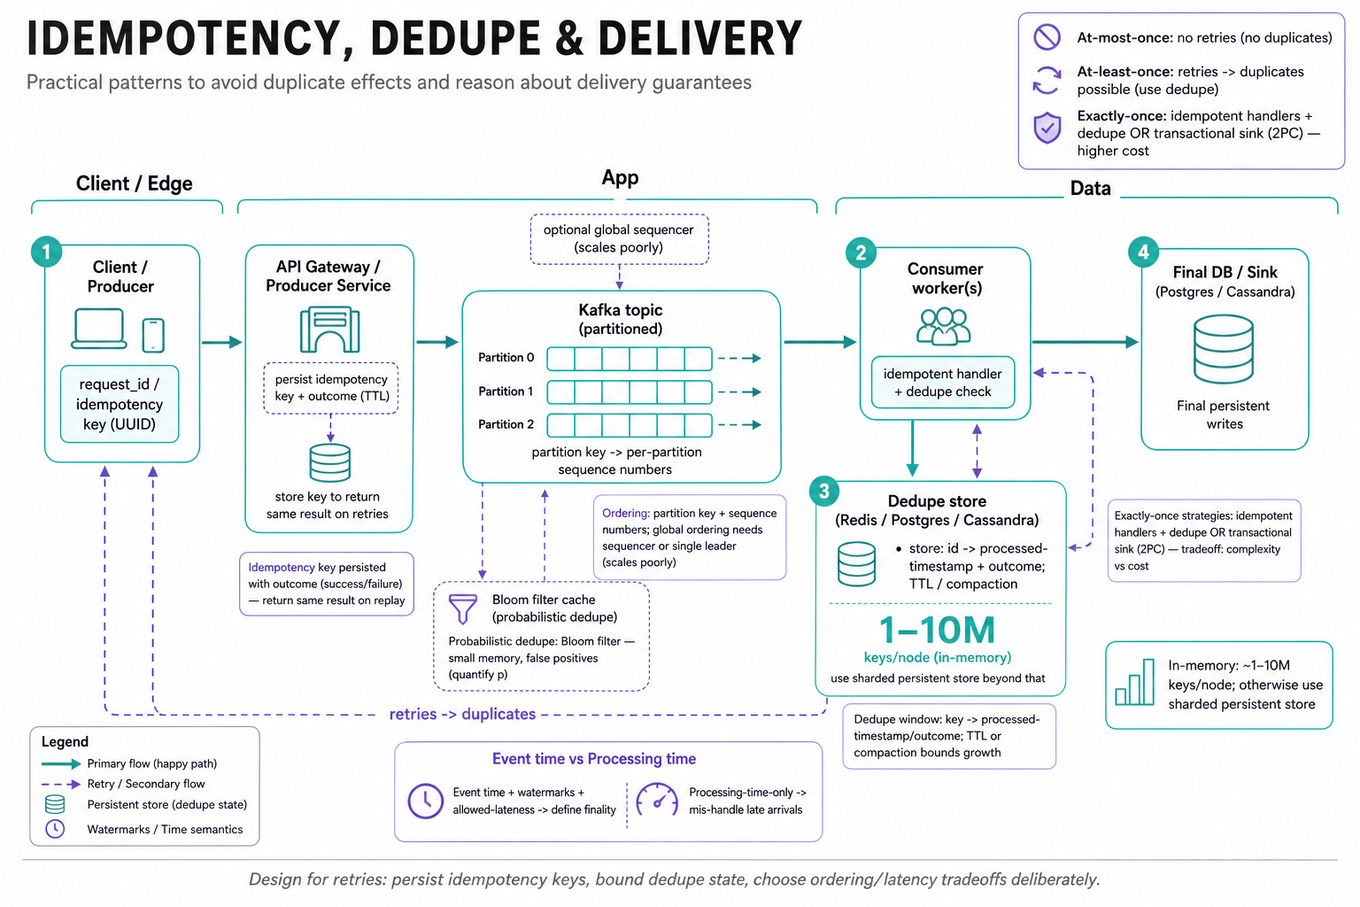
Candidates must demonstrate practical mastery of idempotency, deduplication, and delivery semantics in distributed systems: how to prevent duplicate effects, how to detect and discard duplicate events, and how to reason about at-most-once / at-least-once / exactly-once tradeoffs. Interviewers look for clear scoping questions, pragmatic designs that tolerate partial failures, measurable bounds (memory, latency), and concrete choices for sequencing, finality, and late-arriving data.
Core knowledge
-
Delivery semantics: know definitions and tradeoffs: at-most-once (no retries), at-least-once (retries, duplicates possible), exactly-once (strongest, expensive). Exactly-once often implemented via idempotent handlers plus dedupe, or via transactional sinks (
2PC) — cost vs complexity tradeoff. -
Idempotency key: a unique client- or producer-supplied token (e.g., request UUID) persisted for TTL to make handlers safe to retry; store it with outcome (success/failure) to return same result for replays.
-
Deduplication window and state: dedupe requires state mapping (key -> processed-timestamp/outcome). In-memory maps handle ~1–10M keys per node; beyond that use sharded persistent store (
Postgres,Redis,Cassandra) with TTLs or compaction to bound growth. -
Hash vs explicit id: do not dedupe by payload hash alone unless content-addressable semantics are intended — hash collisions and semantically-equivalent-but-distinct events can mislead. Prefer monotonic sequence numbers or explicit event IDs.
-
Ordering vs partitioning: deterministic ordering requires a partition key and sequence numbers per partition. Global ordering across partitions implies single leader or global sequencer (scales poorly). Use
Kafkapartitions for per-key order guarantees. -
Event time vs processing time: for windows and finality, use event time with watermarks and allowed-lateness; processing-time-only designs mis-handle late arrivals leading to retractions/updates.
-
Late arrivals & finality: define “final” (e.g., watermark + allowed lateness). Use tombstones or compensating events rather than trying to retroactively reorder already-acknowledged delivers.
-
Probabilistic dedupe: Bloom filters or approximate set caches reduce memory but have false positives; acceptable when occasional dropped duplicate is tolerable. Always quantify false positive rate: .
-
Concurrency and uniqueness: for “one claim per user” use a unique DB constraint (e.g., unique(user_id, deal_id)) or atomic
INSERT IF NOT EXISTS/UPSERTwith conditionalWHEREfor optimistic concurrency. Relying solely on application-level locks is risky under failures. -
State compaction & GC: persist dedupe keys with TTL; implement compaction via background jobs or log compaction (e.g.,
Kafkalog compaction), and garbage-collect stale state once finality is reached. -
Exactly-once streaming: frameworks like
Flink/Kafka Streamsimplement “exactly-once” by combining checkpointed operator state with transactional sinks; but they trade latency for consistent snapshots and increased operational complexity. -
Dead-letter queues and poison messages: on repeated retries, move problematic messages to a DLQ and record diagnostic context; do not block foreground processing on a few stuck events.
-
Instrumentation & SLAs: measure duplicate-rate, delivery-latency,
p99retry amplification, dedupe store size. Set TTLs and window sizes based on expected throughput and acceptable memory (e.g., TTL = expected max delivery delay + margin).
Worked example: Design a Personalized Weekly Deals Service
First 30s framing: ask traffic volume, deal claim semantics (one claim per user-deal), latency requirements for personalization, expected sources and correction patterns, and whether eventual corrections are acceptable. Skeleton pillars: (1) ingestion + deduplication for multi-source feeds, (2) active-window selection and ranking with stable pagination, (3) claim-handling with idempotency and concurrency controls, (4) expiration/garbage collection and metrics. For ingestion dedupe, accept canonical event ID or compute stable event key; persist dedupe keys in a sharded Redis with TTL equal to correction window. For claim handling, prefer a unique DB constraint on (user_id, deal_id) and perform INSERT with explicit idempotency key; if synchronous confirmation is needed, combine with conditional update (WHERE status IS NULL) to avoid races. One tradeoff to call out: synchronous strong consistency for claims (simple correctness) vs higher availability and throughput using async processing plus compensation (complexity in refunds/rollbacks). Close: “If I had more time I’d prototype DB schema, quantify dedupe cache sizing for peak QPS, and sketch metrics and backfill/repair paths.”
A second angle: Design at-least-once notification delivery
Same primitives apply but constraints differ: delivery is per-recipient, often low-latency and retry-heavy. Use idempotency keys per notification per device and store outcome per (recipient, notif_id). Implement exponential backoff and a DLQ for persistent failures. Ordering is often relaxed — prefer per-recipient FIFO queues if recipient order matters, otherwise parallelize. For push (APNs/FCM) vs email/SMS, dedupe window and retry strategy change; for push, de-duplicating identical payloads can reduce cost, while for email dedupe must avoid sending multiple emails. For scaling, partition per recipient and shard dedupe state; for extremely high fanout, offload idempotency checks to the client where possible (e.g., include message-id and client dedupe) to reduce server state.
Common pitfalls
Pitfall: Treating payload-equality as a correct dedupe key. Payloads may be semantically different or reordered; dedupe must use an authoritative ID or sequence, not just content hash.
Pitfall: Proposing “exactly-once” as an off-the-shelf property without explaining costs. Exactly-once requires transactional sinks or coordinated checkpoints; the practical alternative is idempotent processing plus dedupe.
Pitfall: Not bounding dedupe state. Failing to set TTLs or compaction leads to unbounded memory growth; always quantify expected keys and choose LRU/Bloom or persistent sharding with GC.
Connections
Interviewers may pivot to stream processing (e.g., Flink state backends, checkpointing), event sourcing and log compaction strategies (Kafka), or database concurrency controls (unique constraints, serializable isolation) to probe deeper consistency tradeoffs.
Further reading
-
Designing Data-Intensive Applications — Martin Kleppmann — excellent chapters on messaging, deduplication, and consistency tradeoffs.
-
Exactly-once delivery semantics in Kafka Streams — Confluent blog — practical explanation of transactional producers and sink semantics.
Practice questions
Focus area — System design is 2/5 and you selected API design and data modeling, so storage, consistency, and API trade-offs need emphasis.

What's being tested
Candidates must show practical mastery of designing scalable, durable, and consistent distributed storage and messaging systems: partitioning, replication/consensus, durability vs latency tradeoffs, client-facing APIs, and multi-tenant operational concerns. Interviewers probe whether you can frame correctness constraints (ordering, delivery semantics, isolation), pick appropriate algorithms (consensus, MVCC, CAS), and justify tradeoffs for availability, performance, and cost in realistic failure modes. They also expect concrete engineering choices — data models, garbage collection, metadata placement, and how to observe and recover systems.
Core knowledge
-
Partitioning (sharding): split data by key to scale throughput; choose consistent hashing or range partitioning depending on hot-key risk; each partition should be independently replicated and rebalanced.
-
Replication & consensus: use leader-follower (e.g.,
Kafka) for high-throughput append logs or quorum consensus (RAFT,Paxos) for strong consistency; quorum = for n replicas. -
Durability & storage tiers: persist writes to WAL/append-only segments on local SSD, then tier cold objects to object stores (
S3); segment sizes commonly 100MB–1GB for efficient compaction and recovery. -
Delivery semantics: clearly separate at-least-once, at-most-once, exactly-once; exactly-once typically requires idempotency + transactional writes (two-phase commit or idempotent producer with sequence numbers).
-
Ordering & offsets: order guarantees usually per-partition; store consumer offsets in a durable, low-latency store (
etcd/Zookeeper/internal offsets topic); allow manual/automatic offset management for replay. -
Deduplication & content-addressable storage: map content to hash-based IDs (e.g., SHA-256) for dedup; use reference counts or reachability GC; avoid counting race conditions with atomic CAS or distributed transactions.
-
Large-payload handling: keep metadata in the log/queue and store large blobs in object store; pass pointers in messages to avoid broker memory spikes.
-
Retention & compaction: support time/size-based retention and log compaction for latest-key semantics; compaction is CPU and IO heavy — plan background compaction windows and backpressure.
-
Transactions & isolation: distributed transactions use coordinated commit (2PC) or transactional log with multi-writer epochs; prefer application-level idempotency or single-partition transactions to avoid cross-partition 2PC complexity.
-
Authentication, authorization, encryption: require mutual TLS (
mTLS) at the transport, RBAC for tenant isolation, and encryption-at-rest for sensitive blobs; keep token lifetimes short and log access-control decisions for audit. -
Monitoring & SLOs: instrument
p99/p95latency, throughput, tail-recovery time, replication lag, and GC pauses; SLOs drive choices: e.g., synchronous replication increasesp99but improves durability. -
Failure & recovery playbooks: design for fast leader failover, replica catch-up, and safe truncation; ensure metadata (topic list, partition assignment) is itself replicated and versioned.
Worked example — Design distributed message queue service
First 30s framing: ask about expected throughput, latency SLOs, message size distribution, ordering guarantees (global vs per-topic-partition), retention semantics, multi-tenancy, and exactly-once needs. Declare assumptions: per-partition ordering is OK, message sizes small (<1MB), throughput 100k msgs/sec per topic.
Skeleton pillars to present:
- API model:
Publish(topic, key, payload)andSubscribe(topic, partition)with consumer-group semantics and offset commit API. - Partitioning & routing: consistent hashing on key → partition to provide per-key ordering and balance.
- Durability & persistence: append-only segmented logs on local disks, immediate fsync for durability when required, async replication.
- Replication & failover: leader-follower per partition with
RAFT-style majority for critical topics and configurable replication factor for others. - Consumer offset & delivery semantics: offsets stored durably; support at-least-once by default, exactly-once via idempotent producers + transactional commit for consumer offsets.
One concrete tradeoff: synchronous replication guarantees durability but increases end-to-end latency; offer topic-level policy to choose sync vs async replication. For large payloads, use pointers to external object store to prevent broker memory/IO explosion.
How to close: summarize SLOs and deployment assumptions, mention operational concerns (compaction windows, monitoring), and say "if I had more time I'd design the metadata service, simulate leader failover scenarios, and sketch client retry/backoff and quota enforcement."
A second angle — Design distributed transactions protocol
The same fundamentals (consensus, durable logs, coordination) apply but constraints shift: cross-shard atomicity demands a coordination protocol. For small-scale, prefer single-partition transactions to avoid distributed commit. For cross-partition, present coordinator-based 2PC built on a replicated log plus leader election; reduce blocking using optimistic concurrency control or cohort-prepared leasing and use timeouts and idempotent commit records to recover. Call out costly failure modes: coordinator crash leaves prepared state requiring careful GC. Tradeoffs: 2PC gives atomicity but sacrifices availability; consider sagas for looser consistency with compensating actions.
Common pitfalls
Pitfall: Designing for global total ordering by default. Total ordering across all keys kills scalability; prefer per-partition ordering and explain why the app actually needs global order.
Pitfall: Ignoring metadata scalability. Storing topic/partition metadata in a single node becomes a bottleneck; design metadata as a small replicated service and quantify limits (metadata ops/sec, number of partitions).
Pitfall: Over-promising exactly-once without implementation detail. Saying "we support exactly-once" without explaining idempotent producers, sequence numbers, and atomic offset commits will lose credibility; show the mechanism (transactional writes + offset commit).
Connections
Interviewers may pivot to adjacent topics like stream processing (stateful processing and time semantics), object storage design (cold-storage lifecycle and GC), or multi-region replication (geo-consistency models and conflict resolution). Be ready to discuss monitoring/playbooks and cost tradeoffs (e.g., hot-spot mitigation vs replication cost).
Further reading
-
[Designing Data-Intensive Applications, Martin Kleppmann] — deep treatment of logs, replication, consensus, and transactions.
-
The Kafka Papers & Confluent Blog — practical patterns for log-based messaging, partitioning, and storage tradeoffs.
Practice questions
Behavioral & Leadership
Focus area — Behavioral is rated 1/5 and many selected concepts are new: conflict, influence, ownership, prioritization, ethics, and stakeholder framing.
What's being tested
Interviewers are probing your ability to take ownership of a technical area while managing ambiguity, tradeoffs, and multiple stakeholders. They want to see clear problem framing, evidence-based tradeoff analysis, pragmatic delivery plans (including risk mitigation), and effective communication under pressure. For a Software Engineer this means demonstrating technical judgment that leads to shipping reliable code, resolving incidents, and aligning cross-functional partners without delegating the engineering responsibilities you own.
Core knowledge
-
Ownership vs. accountability: Ownership means owning technical decisions, rollout, monitoring, and remediation; accountability is accepting follow-through until metrics show recovery or launch success.
-
Clarifying goals fast: Ask for the success metric (e.g.,
p95latency, error rate, adoption %, revenue impact), the deadline, and non-negotiable constraints (privacy, compliance, infra limits). -
Stakeholder map: Identify approvers, implementers, and consumers; capture names, acceptance criteria, and communication cadence in a one-page decision log or RFC.
-
Risk assessment formula: Use Risk = Probability × Impact; quantify impact (user count, revenue/hour, SLA penalty) and use it to prioritize fixes vs. features.
-
Incremental delivery patterns: Use feature flags, canary rollout, and progressive exposure to limit blast radius; require rollback plan and quick toggle in
Git-driven CI/CD. -
Observability and SLOs: Define dashboards and alerts tied to
SLO/SLAandp99/p95metrics; ensure alerts map to on-call viaPagerDutyand have runbooks. -
Incident & postmortem hygiene: Run blameless postmortems, list corrective actions with owners and deadlines, and track them in
JIRA. Include root cause, contributing factors, and time-to-detect/repair. -
Tradeoff language: Frame decisions as three-part: benefit, cost (engineering/time/opportunity), and mitigation. Quantify when possible (e.g., "adds 2 engineer-weeks, reduces error rate by 60%").
-
Communication primitives: Use asynchronous docs (
Google Docs/RFC) for detailed tradeoffs, short syncs for alignment, and single-owner status updates for escalation; summarize decisions in a TL;DR at top. -
When to escalate: If risk > threshold (e.g., potential customer-facing outage or >X% revenue impact), escalate to product or SRE managers immediately; otherwise handle within the squad with clear checkpoints.
-
Code-quality gates: Define minimal acceptable CI checks (unit tests, linters, integration smoke) and when to accept tech debt with a remediation timeline.
-
Ambiguity tactics: Propose explicit assumptions, prototype the riskiest unknown for one sprint, and agree on acceptance criteria to prevent rework.
Worked example — "Answer leadership and ambiguity scenarios"
First 30 seconds: ask for the measurable outcome ("which metric moves define success?"), timeline, and constraints (privacy, infra, dependent teams). Declare assumptions you will use if not specified (e.g., "assume existing API throughput handles +30% load"). Structure your answer around three pillars: (1) clarify and scope — write a one-paragraph objective and list open questions; (2) build & mitigate — deliver a minimal increment behind a feature flag with monitoring and rollback; (3) align & communicate — convene stakeholders for an initial decision and send an RFC summarizing choices and risks. Call out a central tradeoff explicitly: speed-to-production vs. long-term maintainability — choose incremental delivery if you must meet a deadline, but require a follow-up tech task to eliminate temporary scaffolding. Close by stating next steps and what you'd do with more time: broaden tests, run load tests, and coordinate a staged rollout with PagerDuty runbook updates.
A second angle — "Answer leadership and quality tradeoff questions"
The same framing applies but the emphasis shifts to explicit quality thresholds: begin by quantifying acceptable risk (e.g., target p99 latency and minimum test coverage). Use the risk formula to justify cutting scope: prefer shipping a narrower feature with strong observability and rollback capability over a full-featured release with brittle tests. Propose a temporary mitigation (rate limit, circuit breaker) and a technical debt ticket with priority and estimated cost. In negotiation, offer concrete alternatives and associated timelines so stakeholders choose based on quantified tradeoffs rather than abstract assurances.
Common pitfalls
Pitfall: Focusing solely on the technical solution and ignoring stakeholder alignment.
If you produce a great technical plan but haven't secured stakeholder buy-in, the project stalls or gets blocked. State who needs to approve what, surface tradeoffs early, and propose a sync cadence so technical work and stakeholder expectations remain aligned.
Pitfall: Claiming unconditional ownership without delegation or follow-through.
Ownership isn't doing everything alone — it's making clear who owns which subtasks and tracking them until resolution. Use JIRA tickets with owners and due dates; escalate only when commitments miss agreed checkpoints.
Pitfall: Over-engineering to avoid ambiguity.
Building a full solution to remove all unknowns wastes time. Instead, prototype the riskiest unknown, iterate, and use feature flags and canaries to reduce blast radius while you refine the design.
Connections
Interviewers can pivot into incident response and SRE practices (runbooks, SLO design), system design tradeoffs (latency vs. throughput), or cross-team influence topics (how you get alignment without authority). Demonstrating fluency in those adjacent areas makes your behavioral answers more actionable.
Further reading
-
Site Reliability Engineering (Google SRE book) — practical guidance on incident response, SLOs, and blameless postmortems.
-
Accelerate (DORA) — evidence on delivery metrics, tradeoffs between speed and stability, and measurable engineering performance.
Practice questions
Software Engineering Fundamentals
Focus area — You marked reliability new and root-cause analysis shaky; emphasize observability, debugging, postmortems, and resilience vocabulary.
What's being tested
Interviewers expect you to demonstrate practical reliability engineering judgment: define measurable service health, design observability that surfaces real faults, and run diagnostics that map telemetry to root causes. They want concrete tradeoffs (cost vs. coverage, signal-to-noise), familiarity with distributed consistency and replication failure modes, and an incident-driven troubleshooting approach. For a Software Engineer role, focus on designing and instrumenting the service, choosing SLI/SLO targets, reasoning about alert thresholds, and proposing safe remediation paths—not organizational or SRE team staffing.
Core knowledge
-
SLI / SLO / SLA — an SLI is a measurable signal (e.g.,
p99latency); an SLO is a target for that SLI over a window; an SLA is a contractual penalty tied to SLO violations and error budget consumption. -
Error budget math — error_budget = 1 − SLO (e.g., 99.9% availability → error_budget = 0.001); use rolling windows and partition by customer tier when enforcing.
-
Latency percentiles — prefer
p50/p95/p99for user-impact; calculate percentiles on aggregated distributions (HDR histograms) to avoid misinterpretation from averages. -
Metrics vs logs vs traces — metrics are numeric time-series for alerting, logs for event detail and forensic search, traces for request causality; instrument with correlation IDs for cross-signal joins.
-
Instrumentation primitives — use client-side and server-side timers, structured JSON logs, and distributed context propagation (trace-id, span-id); expose metrics via
Prometheus-compatible endpoints or push gateways. -
Alerting strategy — prefer alerting on symptoms with automated noise-reduction (rate-limited, aggregation windows, dynamic baselines); avoid alerting on single-instance internal counters unless they imply customer impact.
-
Health checks & readiness — implement separate liveness and readiness probes; readiness gates for in-flight migrations and leader elections prevent traffic to partially initialized nodes.
-
Replication & consistency — know leader-based replication (e.g.,
Raft,etcd) and leaderless quorum models (e.g., Dynamo-style with vector clocks), and root causes like split-brain, stale reads, and write reordering. -
Diagnostics signals — correlate
replication_lag, commit-index, election-count, GC pauses, CPU steal, syscall errors, and network RTT; sudden divergence patterns often point to networking or leader mis-election. -
Automated remediation patterns — safe steps: circuit breakers, traffic-shaping, progressive rollbacks (canaries), and self-healing (auto-restart) with kill-switches and manual override paths documented in runbooks.
-
Cost/coverage tradeoff — high-cardinality traces and logs are expensive; use sampling, adaptive tracing, and retain raw logs for a short time while long-term aggregates and derived metrics persist.
-
Post-incident hygiene — capture timeline, hypotheses tried, root cause, corrective action, and follow-ups; quantify operational impact in SLI terms and update SLOs or instrumentation gaps accordingly.
Worked example — Explain SLI/SLO/SLA and design monitoring
Frame: start by clarifying user-visible actions and tenants — "Which API calls define customer experience? Are there tiers with different availability promises?" Declare assumptions about request routing, data consistency, and acceptable windows.
Pillars: (1) choose 3–5 core SLIs (successful request rate, p99 latency, error-rate by endpoint), (2) set SLOs per user-impact and business tolerance (e.g., 99.9% p99 latency over 30 days), (3) design alerting and dashboards that map SLI breaches to runbooks and escalation, (4) define automated short-term remediation (circuit breaker) and rollback policy.
Tradeoff: explicitly discuss balancing alert sensitivity vs. noisy paging — choose a multi-tier alert scheme (actionable page for customer-impacting SLO breach; internal tickets for degradations).
Close: state how you'd validate—run chaos tests, synthetic traffic, and measure alert precision; "If I had more time, I'd add per-customer SLI aggregation and adaptive alerts using short-term anomaly detection."
A second angle — Diagnose distributed database inconsistency
This framing shifts emphasis to low-level replication telemetry: first ask which consistency model the system promises (strict serializability vs. eventual). Organize diagnostics around (1) leader health and election logs, (2) replication offsets / watermark comparisons across replicas, (3) client-side write-path tracing and idempotency keys, and (4) network partitions and clock skew metrics.
A strong answer argues for safe mitigation: stop accepting writes to suspect partition, promote stable replica, or perform controlled reconciliation using deterministic merge or compensation operations. Highlight tradeoffs between consistency repair cost and customer-visible rollback: sometimes serving stale reads is preferable to data loss; other times write-rollback with reconciliation is better.
Common pitfalls
Pitfall: Confusing symptom and root cause.
Many candidates jump to "scale more" when p99 spikes, whereas root causes are often latency amplification from a downstream dependency or GC pauses; always correlate traces, GC, and network metrics before capacity actions.
Pitfall: Designing alerts on internal counters.
Alerting on a single queue-length or thread-count without mapping to user-facing SLI causes pager fatigue; instead alert on user-visible degradation and attach internal counters to the dashboard for diagnostics.
Pitfall: Overengineering remediation.
Proposing fully autonomous rollback with no human-in-loop is tempting, but neglects blast-radius controls; prefer staged automation (canary, circuit-breaker, manual escalation) and explicit abort criteria.
Connections
Interviewers may pivot to capacity planning (load forecasting, autoscaling policies), security & multi-tenancy (isolation of telemetry and remediation), or deeper distributed-systems theory (consensus algorithms, clocks, and anti-entropy). Be prepared to connect monitoring decisions to deploy processes and CI/CD safeguards.
Further reading
-
Site Reliability Engineering (Google SRE book) — practical guidance on SLI/SLO, incident response, and postmortems.
-
Designing Data-Intensive Applications by Martin Kleppmann — solid coverage of replication, consistency models, and repair strategies.
Practice questions
- Concurrency, Scheduling, and State Machines (Focus) — covered in depth under Online Assessment below.
Online Assessment — 24 min
Coding & Algorithms
Focus area — Special note says Karat interview tomorrow; prioritize think-aloud, clarifying assumptions, runnable code, edge tests, and complexity in a timed screen.
What's being tested
A Karat technical screen tests whether you can turn an ambiguous programming prompt into a correct, efficient implementation while keeping the interviewer aligned with your reasoning. The interviewer is evaluating problem decomposition, algorithmic judgment, code quality, testing discipline, and your ability to recover when an initial approach fails. Google cares because engineers must make sound decisions under incomplete requirements and communicate those decisions clearly during design, implementation, review, and debugging.
Core knowledge
-
Clarification converts an underspecified prompt into an executable contract: define input and output types, ordering guarantees, duplicate behavior, mutation rules, invalid-input expectations, and constraints before selecting an algorithm.
-
Constraint analysis drives complexity. For , may be acceptable; for or more, target or and state the expected time and auxiliary-space bounds explicitly.
-
Invariant-based reasoning makes solutions explainable. State what remains true after every loop iteration—for example, “the window contains exactly the currently valid subarray”—then use that invariant to justify pointer movement and termination.
-
Hashing commonly reduces lookup from to expected using a hash map or set. Mention collision assumptions, memory cost, duplicate-key handling, and whether the language’s map preserves insertion order.
-
Sorting plus scanning often turns pair, interval, and deduplication problems into solutions. Clarify whether sorting the input is allowed; otherwise copy it, preserving an additional-space cost.
-
Two pointers fit sorted arrays, opposing-end searches, and monotonic windows. A sliding window is valid only when expanding or contracting preserves a monotonic condition; negative values often invalidate the familiar “sum too large, move left” reasoning.
-
Stacks and queues encode deferred decisions and breadth-first order. A monotonic stack can solve next-greater or interval-boundary problems in because each element is pushed and popped at most once.
-
Recursion and graph traversal require explicit handling of visited state, cycles, disconnected components, and depth limits. Prefer iterative DFS when recursion depth could approach ; BFS uses time and typically queue space.
-
Testing strategy should cover a minimal valid case, empty input, singleton input, duplicates, already-sorted and reverse-sorted data, maximum-size data, and a case designed to break the proposed invariant—not merely a few happy-path examples.
-
Language-level correctness includes integer overflow, aliasing, iterator invalidation, null handling, and mutation during iteration. In languages such as Java, use
longwhen intermediate arithmetic can exceed 32-bit range even if final values appear small. -
Communication checkpoints prevent silent divergence: restate the plan, announce the invariant, narrate meaningful implementation choices, and pause after coding to dry-run examples and analyze complexity.
-
Recovery behavior is part of the signal. If a test fails, reproduce it with the smallest counterexample, identify which assumption broke, revise the invariant or data structure, and explain why the fix does not introduce a new failure mode.
Worked example
For a representative prompt under Karat Technical Screen Execution and Communication—implement a function that returns the first character in a string that appears exactly once—a strong candidate first asks whether case, Unicode, whitespace, and empty strings are significant, then declares that the result will be a character or a sentinel when none exists. The answer should be organized around four pillars: frequency counting, preserving the original order, handling edge cases, and verifying complexity. The candidate would propose one pass to build a frequency map and a second pass to return the first character whose count is one. They would explicitly choose a hash map because it gives expected time at the cost of space, where is the number of distinct characters. They should call out that sorting would lose original order unless paired with extra index bookkeeping, making it less direct. While coding, they should state the loop invariant: after processing the first characters in the second pass, no earlier character qualifies. Before closing, they should test an empty string, "a", "aabb", "swiss", and repeated Unicode characters if Unicode is in scope. They should finish with: “If I had more time, I would clarify the API’s no-result convention and add property-based tests asserting that any returned character has frequency one and every earlier character does not.”
A second angle
The same execution principles apply to an interval-merging prompt, but the dominant issue becomes choosing and defending an ordering invariant rather than preserving string order. Clarify whether touching intervals such as [1,3] and [3,5] should merge, then sort by start time and maintain that the output is already merged through the current interval. The key tradeoff is in-place sorting versus copying the input: in-place mutation saves space but may violate caller expectations. Communication should emphasize why each interval is examined once after sorting, yielding time and output space.
Common pitfalls
Pitfall: Jumping into code before defining constraints often produces a locally correct but asymptotically wrong solution, such as nested scans for . State the target complexity and the data structure that achieves it before implementation.
Pitfall: Narrating every keystroke is not communication. Prefer milestone updates—clarification, algorithm, invariant, implementation, tests, complexity—so the interviewer can evaluate decisions without being buried in syntax.
Pitfall: Saying “the code looks right” is not a verification strategy. Dry-run a boundary case, test the failure-prone branch, and explain whether the result matches the invariant; this demonstrates depth beyond memorized patterns.
Connections
An interviewer may pivot from execution to code review, debugging, API design, or system design. They may also ask how the same solution changes under streaming input, concurrency, memory limits, adversarial inputs, or stricter latency requirements.
Further reading
-
Cracking the Coding Interview — Practical coverage of algorithm patterns, complexity analysis, and interview communication.
-
Google Engineering Practices: Code Review — A concrete framework for correctness, clarity, maintainability, and review communication.
-
The Algorithm Design Manual, Steven S. Skiena — Strong treatment of problem decomposition, invariants, and selecting algorithms from constraints.
Practice questions
Focus area — Coding self-rating is 1/5 with only one viewed problem; Karat tomorrow makes core patterns the highest-return practice.

What's being tested
These problems test frequency-counting and anagram/signature reasoning for strings, efficient sliding-window checks over substrings, and membership lookups using hash maps. Interviewers probe algorithmic choices (O(n) vs O(n·k)), correct edge-case handling, and clean iteration/parsing for large inputs.
Patterns & templates
-
Sliding window on contiguous substrings — O(n) two-pointer expand/contract; maintain counts and window invariants to avoid re-scanning.
-
Frequency signature via fixed-size arrays or
Counter— store counts as tuples or serialized keys for O(1) comparison on alphabet-limited strings. -
Hash set / map for membership — pre-hash dictionary words or signatures to get average O(1) membership tests during enumeration.
-
Bitmask / digit mask for digits 0–9 — represent presence with a 10-bit int, enabling O(1) union/intersection checks across numbers.
-
Two-pointer on arrays for monotonic constraints — move left/right and maintain aggregate (sum/count) for O(n) feasibility checks.
-
Binary search over answer space — convert "max size" questions to monotone predicate, run O(n) check per mid for total O(n log n).
-
Single-pass string parsing for snake_case→camelCase — build result in-place, handle separators and capitalization in O(n) time and O(1) extra space.
Common pitfalls
Pitfall: Comparing full count arrays per window naïvely makes algorithms O(n·k); instead update counts incrementally on pointer moves.
Pitfall: Forgetting to canonicalize signatures (order or normalized tuple) causes false negatives when checking anagram membership.
Pitfall: Not validating separators/edge cases (empty string, consecutive underscores) in parsing tasks leads to incorrect outputs or crashes.
Practice these
The practice cards below cover the canonical variants — solve all of them and time yourself.
Practice questions
Focus area — DP appears in both Google and online screens, and low coding confidence means state definition and transitions need focused review.
What's being tested
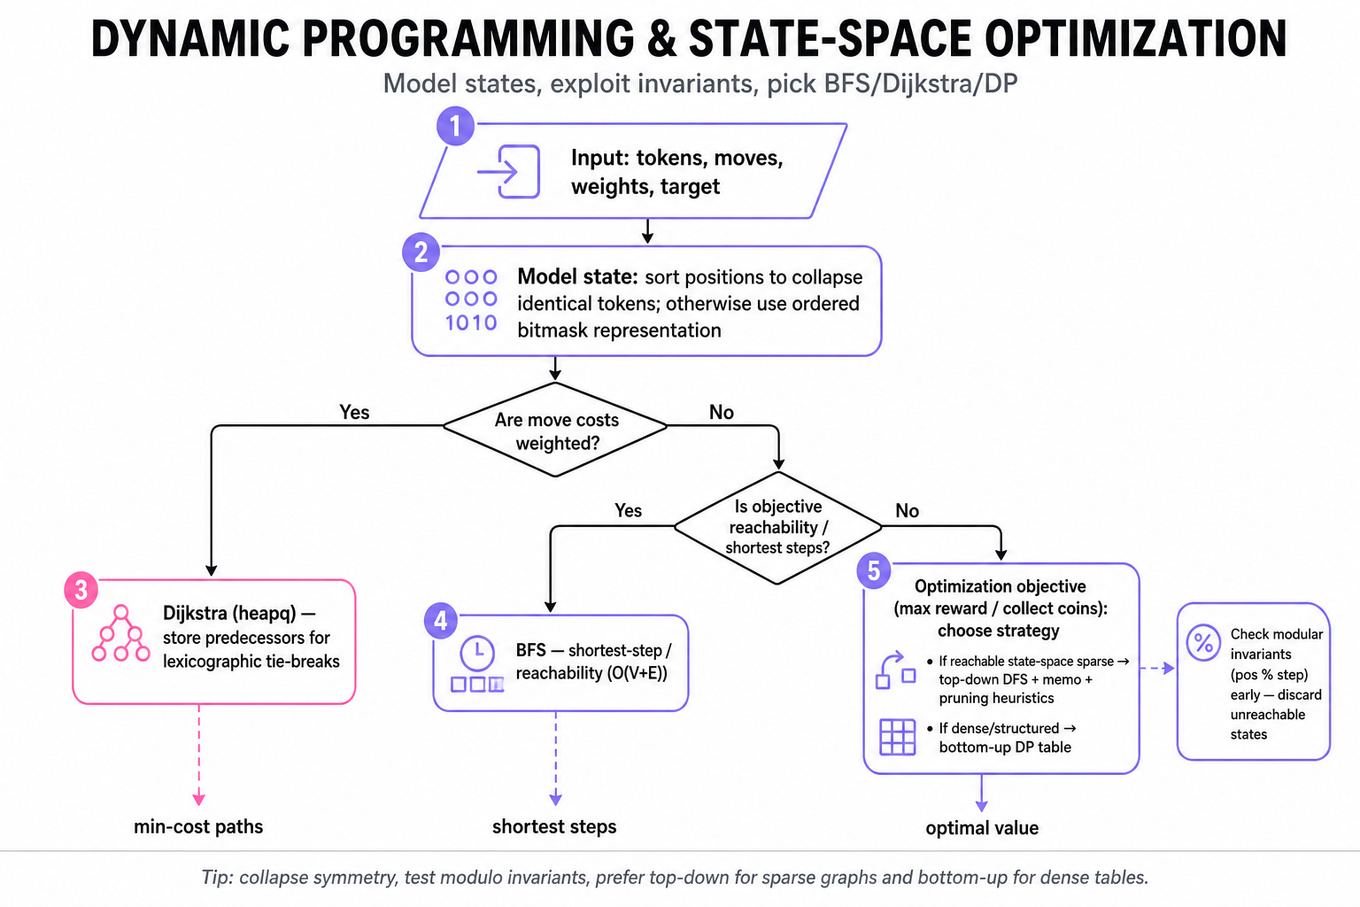
These problems test state-space modeling and dynamic programming (DP): defining compact states, transitions, and value propagation under movement and collision constraints. Interviewers probe whether you can exploit invariants (e.g., modulo classes, symmetry) to reduce exponential state blowup and choose the right search/optimization primitive (memoized dfs, bottom-up dp, bfs, or dijkstra).
Patterns & templates
-
Bitmask DP for small numbers of tokens — represent occupied cells as bits; typical complexity
O(states * transitions)and memoryO(2^k * n). -
Canonical ordering: sort token positions (or canonicalize symmetric states) to avoid counting permutations; reduces state-space by
k!when tokens indistinguishable. -
Modular invariants: reduce positions using modulo classes (e.g., moves of +3 preserve
pos % 3), immediately discarding unreachable targets. -
Use top-down memoization (
dfs+ cache) for sparse reachable state graphs; bottom-updpwhen transition ordering is clear and states dense. -
For weighted single-path problems, use Dijkstra with
heapqfor min-cost; store predecessor to reconstruct lexicographically tiebroken paths. -
Use BFS for reachability or shortest-step counts on unweighted graphs; complexity
O(V+E). -
Tip: prune states with an upper-bound heuristic (e.g., remaining coins max) to speed search when exact optimum needed.
Common pitfalls
Pitfall: Treating identical tokens as distinct causes factorial state explosion; canonicalize positions to collapse equivalent permutations.
Pitfall: Ignoring movement invariants like
pos % step == constantleads to wasted work on unreachable states and wrong feasibility answers.
Pitfall: Assuming greedy local coin collection is optimal; without proof, fallback to DP/search and justify complexity tradeoffs.
Practice these
the practice cards below cover the canonical variants — solve all of them and time yourself
Practice questions
Software Engineering Fundamentals
Focus area — You marked this concept new and selected resource management; focus on explicit states, races, locking, and scheduling trade-offs.
What's being tested
These problems test building and reasoning about an async primitive (like CompletableFuture) and scheduling: safe callback registration, correct completion state machine, and efficient timer/task multiplexing onto a thread-pool. Interviewers probe race-free state transitions, cancellation, ordering guarantees, and scalable timer/scheduler data structures.
Patterns & templates
-
State machine with explicit states (e.g., PENDING → COMPLETING → COMPLETED/FAILED/CANCELLED) and a single CAS transition per completion to avoid races.
-
Callback list appended atomically with
compareAndSetand drained by the thread that wins completion, avoiding locking on hot path. -
Use volatile for result/state visibility and minimal locking; prefer lock-free for low-latency futures, fallback to short critical sections when necessary.
-
Implement timers with a min-heap priority queue for correctness, or a timer wheel for large-scale (~10^6 timers) amortized O(1) ticks.
-
Use ForkJoinPool / work-stealing for parallel array processing; prefer divide-and-conquer recursively to maximize locality and CPU utilization.
-
Cancellation: mark state then attempt to remove scheduled tasks; for heap-based timers, use lazy deletion flags to avoid O(n) removals.
-
Batch wakeups: coalesce scheduled callbacks and run them on a worker thread (
execute()), avoid running user callbacks under internal locks to prevent deadlocks.
Common pitfalls
Pitfall: Failing to make state transitions atomic leads to double-completion or lost callbacks when two threads try to complete concurrently.
Pitfall: Running user callbacks while holding internal locks causes deadlocks or long GC pauses; always invoke callbacks outside locks.
Pitfall: Assuming
notify()without rechecking condition — handle spurious wakeups and always loop on the predicate when usingwait()/notify().
Practice these
The practice cards below cover the canonical variants — solve all of them and time yourself.
Practice questions