Upstart Software Engineer Interview Prep Guide
Everything Upstart actually asks Software Engineer candidates — concept walkthroughs, worked examples, and the real interview questions, drawn from candidate reports. Free to read.
Last updated
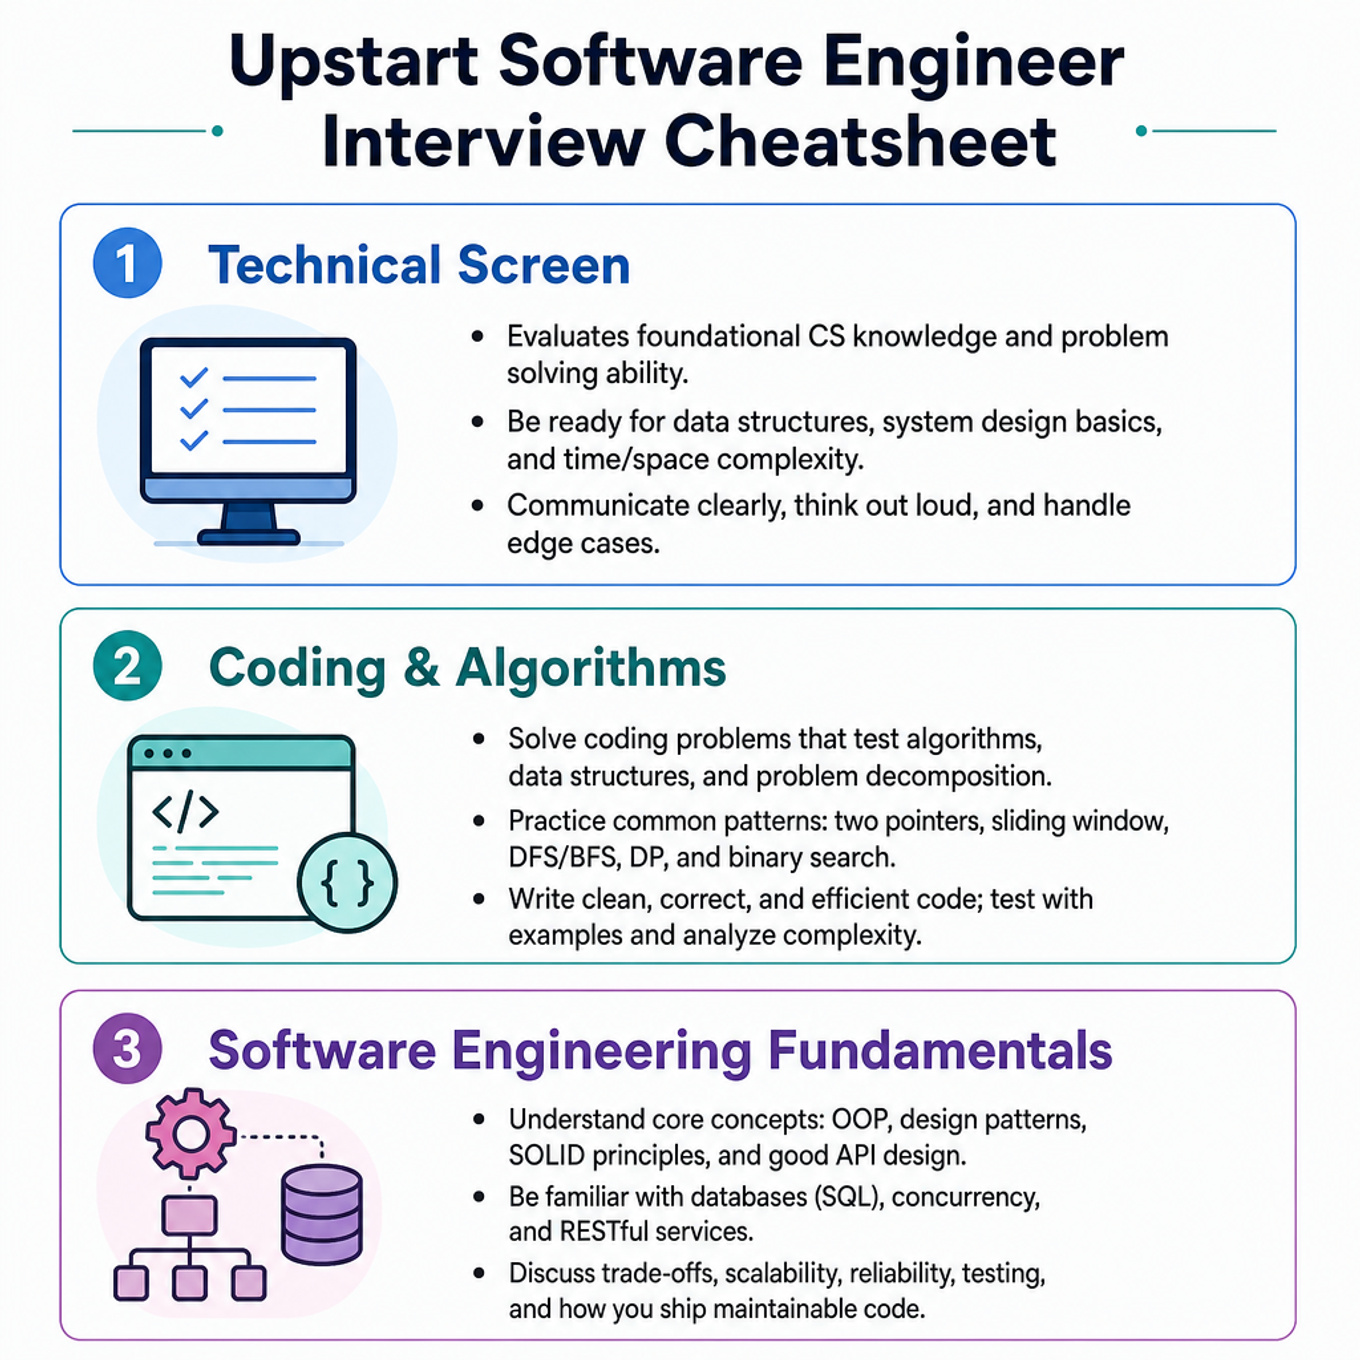
Focus most on event-driven queue simulations, record aggregation, and fintech-safe numerical handling; you rated Coding & Algorithms 3/5, viewed 21 coding items, and have no solved-signal history here. Merely review simpler string, array, coordinate, grid, and recruiter-screen material because you selected no extra subtopics and skipped concept ratings, which default to solid. The Upstart-specific emphasis is production Python in services, backend fintech reliability, and precise financial calculations for lending workflows. With 1–2 weeks, spend the first pass on the 30-minute Technical Screen plan, then repeat timed implementations of the emphasized coding patterns.
Technical Screen — 30 min
Coding & Algorithms
Event-Driven Simulation And Queue State
Focus areaFocus area — Stateful simulations are easy to miscount under time pressure; emphasize arrivals, ordering, capacity, and billing boundaries.
What's being tested
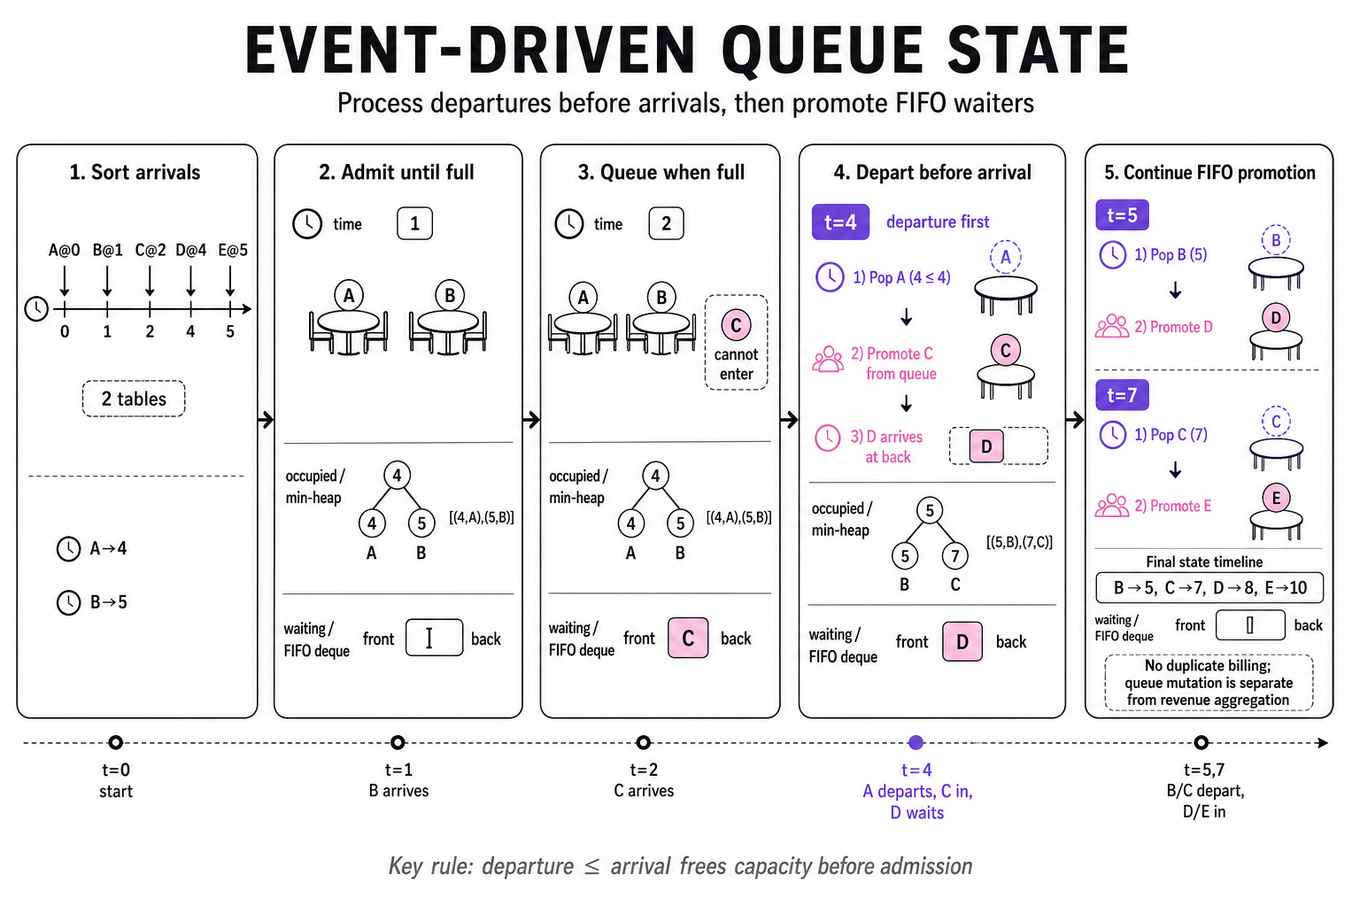
This tests event-driven simulation with explicit lifecycle state: processing arrivals and departures in chronological order while enforcing capacity and FIFO waiting. You must preserve event ordering, update occupancy correctly, and aggregate revenue without double-counting customers or mishandling simultaneous events.
Patterns & templates
- Sort customers by arrival time and maintain a departure-time min-heap for occupied tables; target
O(n log n)time andO(n)space. - For each arrival, pop departures with
departure <= arrivalbefore admitting the customer; this makes capacity available at exact departure timestamps. - Use a FIFO queue for waiting customers, storing arrival time and any immutable customer metadata required for later billing.
- Model state explicitly:
occupied,waiting,revenue, and each customer’s service/departure information; avoid inferring state from partial fields. - After every departure, admit queued customers in order while capacity remains; decide whether waiting time changes revenue or only service timing.
- Group or carefully order same-timestamp events; process departures before arrivals when a departing customer frees capacity immediately.
- Keep revenue aggregation separate from queue mutation, and use integer or decimal-safe currency arithmetic rather than binary floating point.
Common pitfalls
Pitfall: Treating the waiting queue as a priority queue by party size or departure time violates FIFO behavior; use a deque.
Pitfall: Processing arrivals before same-time departures incorrectly rejects customers when capacity should already be available.
Pitfall: Charging based on arrival time instead of actual service completion, or charging queued customers twice during promotion from the queue.
Practice these
The practice cards below cover the canonical variants — solve all of them and time yourself.
Practice questions
Coding is 3/5 and this is in the screen; practice careful edge cases, but concept ratings default solid.
What's being tested
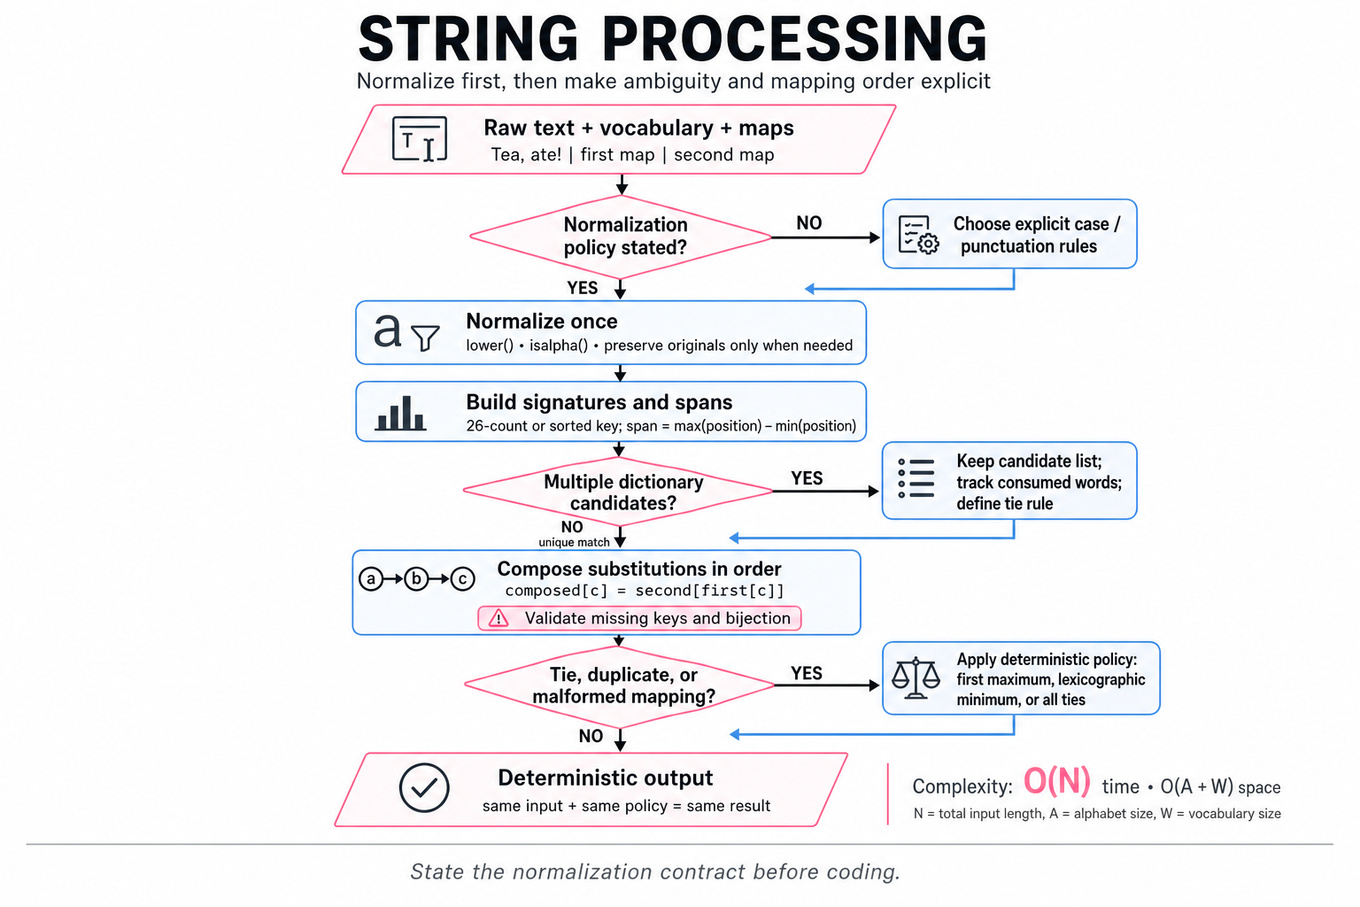
These problems test character-level string processing: normalization, frequency counting, positional mapping, anagram detection, and composing substitution dictionaries. You must translate ambiguous requirements—case, punctuation, duplicate words, ties, malformed mappings—into deterministic algorithms with clear time and space bounds.
Patterns & templates
-
Normalize once with
lower(),isalpha(), or an explicit character policy; preserve original tokens only when output or tie-breaking requires them. -
Anagram detection uses a 26-count vector, sorted-character key, or
Counter; prefer counting for fixed alphabets:O(k)per word. -
Dictionary-constrained decoding groups vocabulary by signature, then backtracks or validates candidates while tracking consumed words and ambiguity.
-
Character substitution maps use
dictlookups; compose mappings ascomposed[c] = second[first[c]], validating bijection and missing keys. -
Per-word letter span is
max(position) - min(position)over normalized letters; initialize bounds safely and ignore punctuation explicitly. -
Stable tie handling should be specified before coding: retain first maximum, lexicographically smallest word, or return every tied result.
-
Complexity accounting should use total input length
N; one-pass scans areO(N)time andO(A + W)space for alphabet sizeAand vocabulary sizeW.
Common pitfalls
Pitfall: Treating punctuation or uppercase letters inconsistently can produce different signatures, spans, or decoded output; state the normalization contract first.
Pitfall: Assuming an anagram has one dictionary match; preserve candidate lists and define how repeated words or ambiguity are resolved.
Pitfall: Composing substitutions in the wrong order; test a character through both transformations and verify injectivity when mappings claim to be bijective.
Practice these
The practice cards below cover the canonical variants—solve all of them and time yourself.
Practice questions
Core screen material with 21 coding views but no solved signal; focus on clean implementation and complexity.
What's being tested
These problems test array filtering, stable reordering, and pairwise computation using clear iteration and appropriate data structures. You should demonstrate correct handling of empty inputs, duplicates, ordering requirements, and time/space complexity without overengineering straightforward transformations.
Patterns & templates
-
Filter then reverse — collect qualifying values in one pass, then reverse with
[::-1]or two pointers; typicallyO(n)time andO(k)space. -
In-place compaction — use a write index to retain selected elements while scanning; reduces auxiliary space to
O(1)when mutation is allowed. -
Preserve stable order — append values as encountered unless explicitly asked to reorder; never sort when reversal or original-relative ordering is required.
-
Hash-set membership — store seen or target values for expected
O(1)lookup; useful for pair-sum identification inO(n)time andO(n)space. -
Pairwise difference — compare every unordered pair with nested loops for
O(n²)time; track the minimum rather than storing all differences. -
Sort for pair optimization — sorting enables adjacent comparisons or two pointers in
O(n log n)time; only use it when original indices/order do not matter. -
Edge-case checklist — test empty and singleton arrays, no matches, all matches, duplicates, negatives, zero, and pairs that reuse or cannot reuse an element.
Common pitfalls
Pitfall: Sorting to find a result can silently violate requirements to preserve input order or return original indices.
Pitfall: Treating duplicate values as the same element can miss valid pairs or accidentally reuse one array position twice.
Pitfall: Claiming
O(1)space while constructing a filtered or reversed output array; distinguish auxiliary space from the returned result.
Practice these
The practice cards below cover the canonical variants — solve all of them and time yourself.
Practice questions
Software Engineering Fundamentals
Focus area — Upstart operates in lending; precise cents, rates, rounding, and deterministic comparisons matter even in coding discussions.
What's being tested
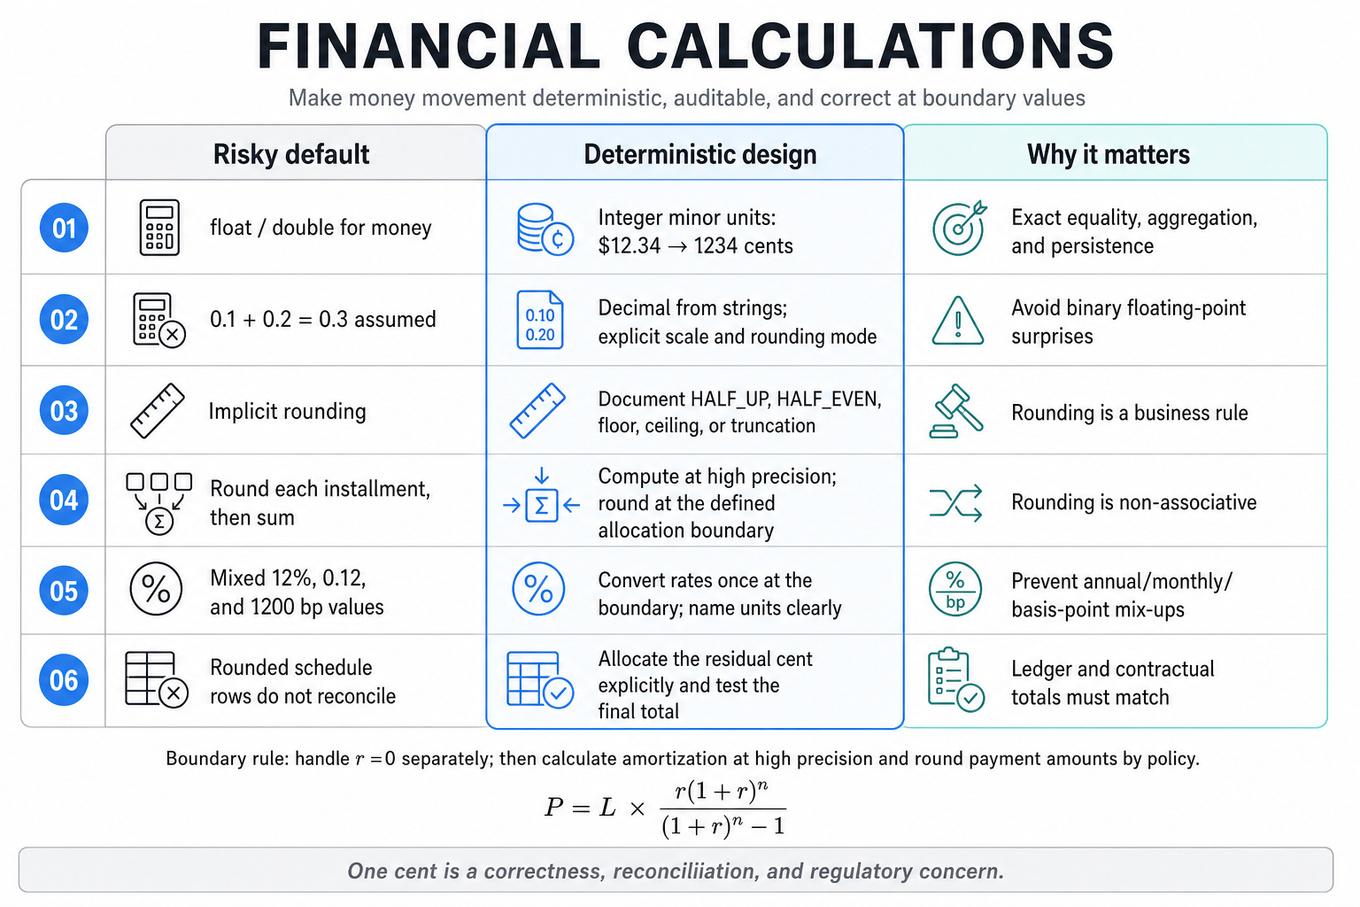
This topic tests whether you can design financial computations that are deterministic, auditable, and correct at boundary values—not merely produce a plausible numerical answer. You should demonstrate judgment about numeric representation, rounding policy, overflow, ordering of operations, and how to test calculations independently. Upstart handles lending decisions, payment schedules, and money movement, so a one-cent discrepancy can become a reconciliation failure, incorrect customer balance, or regulatory issue.
Core knowledge
-
Money representation should use integer minor units, such as cents, when the currency has a fixed two-decimal scale:
$12.34becomes1234. This avoids binary floating-point surprises and makes equality, aggregation, and persistence straightforward. -
IEEE 754 floating point cannot represent many decimal fractions exactly; for example,
0.1 + 0.2 != 0.3in common languages. Never usefloatordoublefor balances, rates, repayment amounts, or ledger totals without a deliberate error analysis. -
Decimal arithmetic is appropriate when calculations require fractional cents or configurable precision. Use language-native decimal types such as Java
BigDecimalor PythonDecimal, construct values from strings, and specify both scale and rounding mode explicitly. -
Rounding policy must be a business rule, not an implementation accident. Distinguish
HALF_UP,HALF_EVEN, floor, ceiling, and truncation; document when rounding occurs and whether intermediate values retain extra precision. -
Order of operations matters because rounding is generally non-associative: rounding each installment and then summing can differ from calculating a total and rounding once. Define whether allocation occurs per transaction, payment, day, or schedule line.
-
Rates need explicit units and scales. A 12% annual rate may be represented as
0.12,12, or1200basis points. Convert once at the boundary, name units clearly, and avoid silently mixing annual, monthly, daily, percentage, and basis-point values. -
Amortization calculations commonly use where is principal, is periodic interest rate, and is the number of payments. Handle separately, then round payment amounts according to policy.
-
Residual allocation is required when rounded schedule rows do not sum to the contractual total. Compute the high-precision target, round ordinary rows, and assign the remaining cent to a defined row—often the final payment—while preserving nonnegative principal and interest.
-
Overflow and scale growth are practical risks even with integer units. Use a sufficiently wide type, such as 64-bit integers for ordinary currency ranges or arbitrary-precision integers for aggregate ledgers; check multiplication before it overflows.
-
Determinism and reproducibility require fixed inputs, explicit timezone and date rules, stable iteration order, and the same arithmetic implementation across services. Avoid platform-dependent decimal conversions and ensure serialization preserves scale, sign, currency, and rounding metadata.
-
Ledger invariants provide stronger validation than example outputs. Useful checks include debits equaling credits, opening balance plus signed transactions equaling closing balance, total principal equaling original principal, and rounded schedule amounts equaling the contractual repayment total.
-
Property-based testing can generate rates, terms, principal values, and boundary amounts to verify invariants. Add examples for zero interest, one payment, half-cent values, very large balances, negative or invalid inputs, leap days, and currencies with different minor-unit scales.
Worked example
Representative question: “Calculate a loan repayment schedule with correct precision and rounding.” In the first 30 seconds, clarify the currency, annual-rate convention, payment frequency, day-count convention, whether interest compounds, and whether the requested output is a displayed schedule or a legally binding repayment plan. I would state that monetary values use integer cents or BigDecimal, while rates retain sufficient precision until the prescribed rounding point. I would organize the answer around input validation, periodic-rate conversion, amortization or installment calculation, per-row principal and interest allocation, and invariant-based testing. I would explicitly flag the tradeoff between rounding each row immediately for customer display and retaining extra precision internally to prevent cumulative drift. The implementation should handle zero interest separately, define the final-payment residual rule, reject overflow and invalid terms, and expose a deterministic result. Tests would compare principal and payment totals, exercise half-cent boundaries, and verify that the final balance is exactly zero or the documented residual. If I had more time, I would also discuss versioning the calculation policy so historical loans remain reproducible after a business-rule change.
A second angle
Representative question: “Compute the total payoff amount from transactions, fees, and interest.” The same precision principles apply, but the dominant concern shifts from schedule generation to aggregation and reconciliation. I would clarify whether transactions arrive in chronological order, whether duplicate events are possible, and whether fees can be refunded or partially applied. A robust design uses immutable ledger entries, integer minor units or decimal values with explicit scale, idempotency keys, and a deterministic ordering for interest and fee application. I would test that replaying the same transaction stream does not change the balance and that every adjustment has an auditable source.
Common pitfalls
Pitfall: Using
doublebecause the result “looks correct” for ordinary values. Binary floating-point can produce incorrect comparisons and one-cent drift; use minor units or decimal arithmetic with an explicit policy.
Pitfall: Rounding every intermediate expression without explaining why. This may create cumulative errors or make the final schedule fail to reconcile; retain precision internally and round at the domain-defined boundary.
Pitfall: Jumping directly into formula code without clarifying rate units, day-count rules, currency scale, and final-payment behavior. A strong answer states assumptions first and identifies which requirements must come from the contract or product specification.
Connections
The interviewer may pivot to idempotency, event sourcing, ledger reconciliation, or property-based testing. They may also ask about database numeric types, serialization contracts, or how to safely migrate a rounding rule without changing historical results.
Further reading
-
Java
BigDecimaldocumentation — precise decimal arithmetic, scale, and rounding behavior. -
Martin Fowler, “Accounting Patterns” — useful background on immutable entries, ledgers, and financial auditability.
-
IEEE 754 Floating-Point Standard — why binary floating-point behaves differently from decimal arithmetic.
Practice questions