Google Software Engineer Interview Prep Guide
Everything Google actually asks Software Engineer candidates — concept walkthroughs, worked examples, and the real interview questions, drawn from candidate reports. Free to read.
Last updated
Focus most on Google L7 system design: API contracts, sharding, replication, quotas, idempotency, distributed scheduling, plus graph/grid/interval refreshers where your concept ratings are mostly shaky. Review rather than relearn observability, core concurrency, GPU primitives, and general coding foundations because your category self-ratings are 4/5 and several related concepts are marked solid. The Google-specific emphasis is cloud-scale reliability, rate/quota enforcement, consistency trade-offs, GPU backend serving, embedded-to-cloud interfaces, and L7 architectural judgment. With only 1–2 weeks, concentrate study time on emphasized sections and use brief concepts as fast sanity checks rather than full practice tracks.
Technical Screen — 70 min
Coding & Algorithms
-
BFS/DFS Graph and Tree Traversal and Shortest Paths (Focus) — covered in depth under Onsite below.
-
Intervals, Line Sweep, and Difference Arrays (Focus) — covered in depth under Onsite below.
-
Core Array, String, Hash Map, Sliding Window, and Binary Search Patterns — covered in depth under Online Assessment below.
System Design
-
Secure Distributed Storage, Messaging, and Consistency (Focus) — covered in depth under Onsite below.
-
GPU Backend Serving and Scheduling for Cloud (Focus) — covered in depth under Onsite below.
-
L7 Technical Leadership and Architecture Trade-offs (Focus) — covered in depth under Onsite below.
Software Engineering Fundamentals
-
Concurrency, Scheduling, and State Machines (Focus) — covered in depth under Onsite below.
-
Embedded-to-Cloud Backend Integration (Focus) — covered in depth under Onsite below.
Behavioral & Leadership
- Behavioral Leadership, Ownership, and Stakeholder Management (Focus) — covered in depth under Onsite below.
Onsite — 70 min
Coding & Algorithms
Focus area — You selected graphs/grids and marked several shortest-path, topo, union-find, and augmented-grid concepts shaky; prioritize refresher drills.
What's being tested
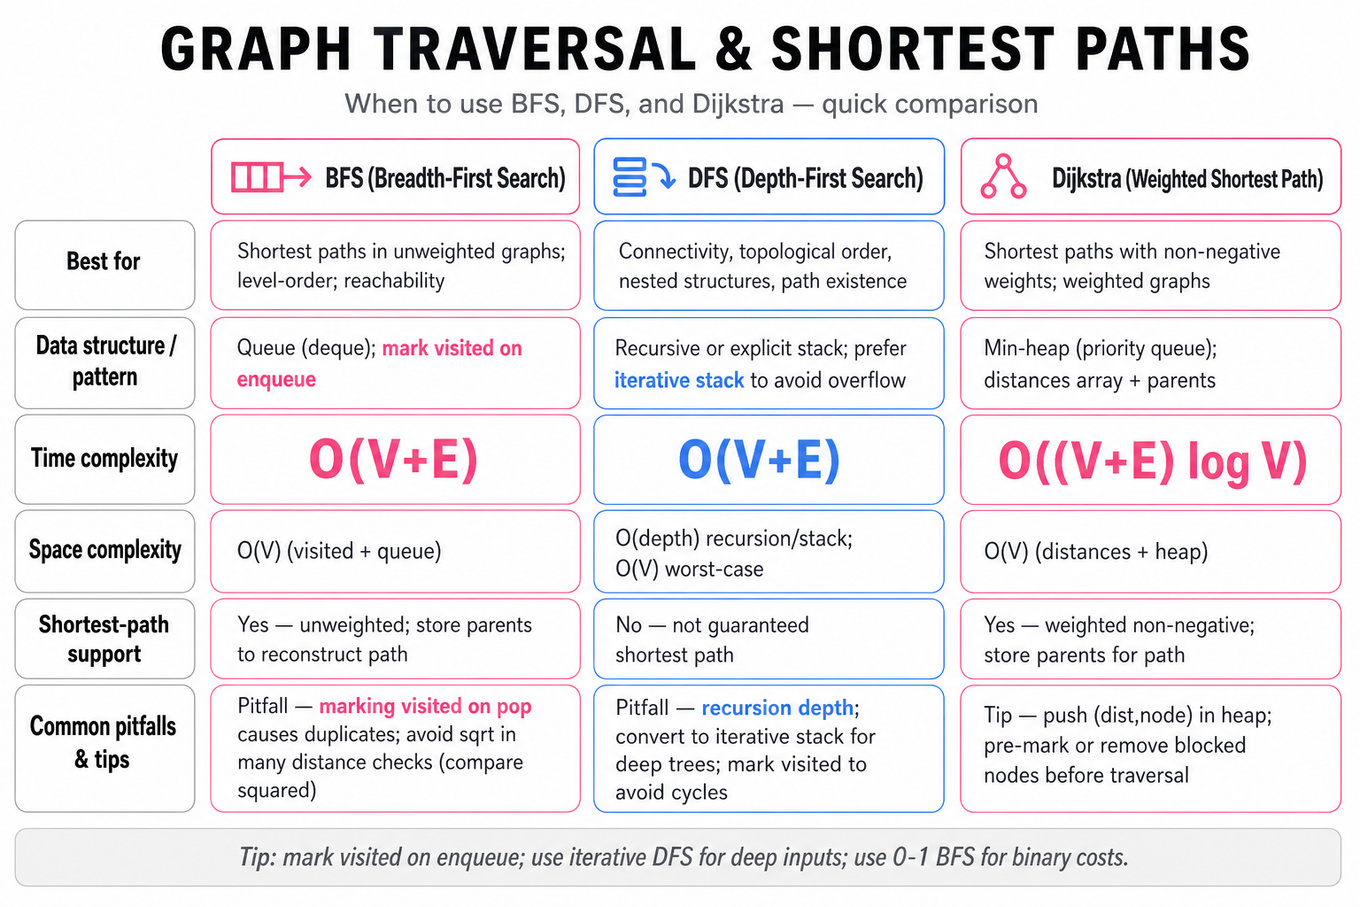
Candidates must demonstrate correct use of BFS and DFS for traversal, reachability, and component counting, plus shortest-path techniques (unweighted BFS, Dijkstra) under constraints. Interviewers probe algorithmic tradeoffs (time/space), correctness with blocked/forbidden nodes, and iterative vs recursive implementations to avoid stack overflow.
Patterns & templates
-
BFS for shortest paths in unweighted graphs — use
dequequeue, mark visited on enqueue, time O(V+E), space O(V). -
DFS (recursive or explicit stack) for connectivity and nested structures; prefer iterative stack to avoid recursion depth issues.
-
Dijkstra with
heapqfor weighted shortest paths; complexity O((V+E) log V); store distances and parents for path reconstruction. -
Multi-criteria shortest path: encode tuple cost (danger_count, steps) and use lexicographic comparison in priority queue or use 0-1 BFS for binary costs.
-
Remove/ignore blocked nodes by pre-marking in
setor deleting adjacency entries before traversal. -
Connected clusters (geometric): build adjacency by threshold distance squared to avoid
sqrt, deduplicate coordinates with aset, then BFS/DFS for components. -
Deleting in a binary search tree: handle leaf, single-child, two-children cases — replace with inorder successor (min in right subtree) and adjust pointers.
Common pitfalls
Pitfall: Marking visited only on pop instead of on enqueue causes duplicate enqueues and exponential blowup on dense graphs.
Pitfall: Using
sqrtfor many distance checks costs CPU and risks floating error — compare squared distances instead.
Pitfall: Recursing on deeply nested lists/trees without converting to an iterative stack risks stack overflow on large inputs.
Practice these
The practice cards below cover the canonical variants — solve all of them and time yourself.
Practice questions
Focus area — You selected interval/scheduling and marked merge, sweep-line, meeting rooms, and weighted intervals shaky; emphasize boundary and tie rules.
What's being tested
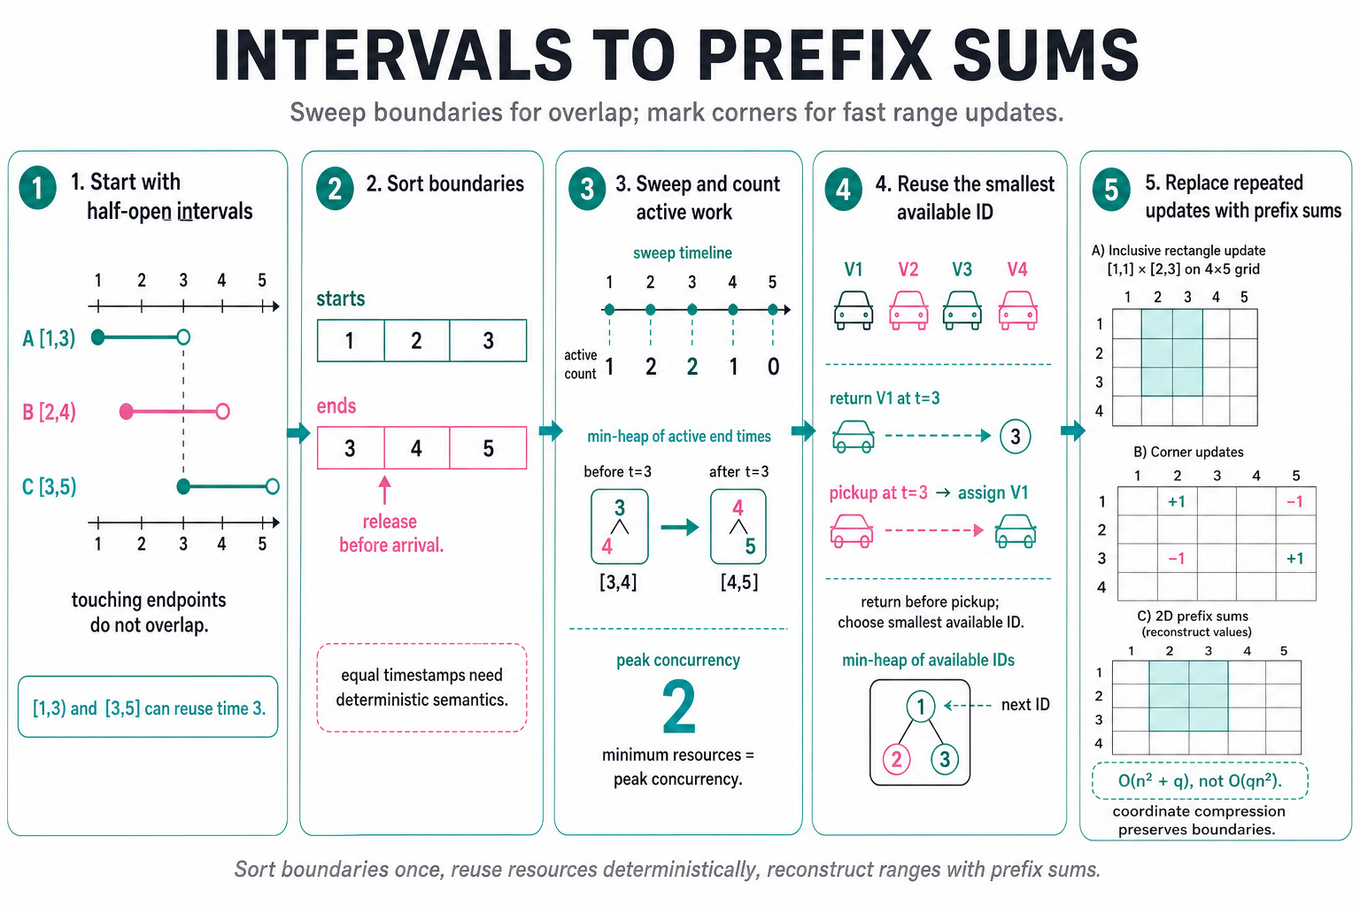
These problems test interval scheduling, line sweep, and difference arrays for detecting overlaps, allocating the minimum resources, and applying many range updates efficiently. You must demonstrate precise endpoint semantics, deterministic tie-breaking, and the ability to replace repeated simulation with sorting or prefix-sum reconstruction.
Patterns & templates
-
Half-open intervals
[start, end)overlap iffmax(starts) < min(ends); touching endpoints such as[1,3)and[3,5)do not conflict. -
Line sweep: sort starts and ends, process equal timestamps according to semantics; release resources before assigning arrivals for reusable half-open intervals.
-
Minimum resources: sort intervals by start time and maintain a min-heap of active end times; heap size is peak concurrency, with
O(n log n)time. -
Deterministic assignment: keep reusable vehicle IDs in a min-heap; assign the smallest available ID, while returning vehicles before processing same-time pickups.
-
Grouped recurring jobs: merge or union intervals by job identifier before capacity counting when repeated occurrences represent one logical resource requirement.
-
2D difference array: for inclusive rectangle
[r1,r2] × [c1,c2], update four corners, then take 2D prefix sums; total work isO(n² + q). -
Coordinate compression maps sparse endpoints to ranks, reducing memory from grid or time range size to
O(n + q); preserve interval boundaries carefully.
Common pitfalls
Pitfall: Treating inclusive and half-open endpoints interchangeably creates false conflicts or misses reuse at an exact return/pickup time.
Pitfall: Simulating every cell for every rectangle costs
O(qn²); mark boundaries once and reconstruct with prefix sums.
Pitfall: Ignoring stable tie-breaking can produce a numerically correct fleet size but an incorrect vehicle assignment.
Practice these
The practice cards below cover the canonical variants — solve all of them and time yourself.
Practice questions
- Core Array, String, Hash Map, Sliding Window, and Binary Search Patterns — covered in depth under Online Assessment below.
System Design
Focus area — Selected API, sharding, replication, quotas; many related concepts are new or shaky, so this anchors system design prep.

What's being tested
Candidates must show practical mastery of designing scalable, durable, and consistent distributed storage and messaging systems: partitioning, replication/consensus, durability vs latency tradeoffs, client-facing APIs, and multi-tenant operational concerns. Interviewers probe whether you can frame correctness constraints (ordering, delivery semantics, isolation), pick appropriate algorithms (consensus, MVCC, CAS), and justify tradeoffs for availability, performance, and cost in realistic failure modes. They also expect concrete engineering choices — data models, garbage collection, metadata placement, and how to observe and recover systems.
Core knowledge
-
Partitioning (sharding): split data by key to scale throughput; choose consistent hashing or range partitioning depending on hot-key risk; each partition should be independently replicated and rebalanced.
-
Replication & consensus: use leader-follower (e.g.,
Kafka) for high-throughput append logs or quorum consensus (RAFT,Paxos) for strong consistency; quorum = for n replicas. -
Durability & storage tiers: persist writes to WAL/append-only segments on local SSD, then tier cold objects to object stores (
S3); segment sizes commonly 100MB–1GB for efficient compaction and recovery. -
Delivery semantics: clearly separate at-least-once, at-most-once, exactly-once; exactly-once typically requires idempotency + transactional writes (two-phase commit or idempotent producer with sequence numbers).
-
Ordering & offsets: order guarantees usually per-partition; store consumer offsets in a durable, low-latency store (
etcd/Zookeeper/internal offsets topic); allow manual/automatic offset management for replay. -
Deduplication & content-addressable storage: map content to hash-based IDs (e.g., SHA-256) for dedup; use reference counts or reachability GC; avoid counting race conditions with atomic CAS or distributed transactions.
-
Large-payload handling: keep metadata in the log/queue and store large blobs in object store; pass pointers in messages to avoid broker memory spikes.
-
Retention & compaction: support time/size-based retention and log compaction for latest-key semantics; compaction is CPU and IO heavy — plan background compaction windows and backpressure.
-
Transactions & isolation: distributed transactions use coordinated commit (2PC) or transactional log with multi-writer epochs; prefer application-level idempotency or single-partition transactions to avoid cross-partition 2PC complexity.
-
Authentication, authorization, encryption: require mutual TLS (
mTLS) at the transport, RBAC for tenant isolation, and encryption-at-rest for sensitive blobs; keep token lifetimes short and log access-control decisions for audit. -
Monitoring & SLOs: instrument
p99/p95latency, throughput, tail-recovery time, replication lag, and GC pauses; SLOs drive choices: e.g., synchronous replication increasesp99but improves durability. -
Failure & recovery playbooks: design for fast leader failover, replica catch-up, and safe truncation; ensure metadata (topic list, partition assignment) is itself replicated and versioned.
Worked example — Design distributed message queue service
First 30s framing: ask about expected throughput, latency SLOs, message size distribution, ordering guarantees (global vs per-topic-partition), retention semantics, multi-tenancy, and exactly-once needs. Declare assumptions: per-partition ordering is OK, message sizes small (<1MB), throughput 100k msgs/sec per topic.
Skeleton pillars to present:
- API model:
Publish(topic, key, payload)andSubscribe(topic, partition)with consumer-group semantics and offset commit API. - Partitioning & routing: consistent hashing on key → partition to provide per-key ordering and balance.
- Durability & persistence: append-only segmented logs on local disks, immediate fsync for durability when required, async replication.
- Replication & failover: leader-follower per partition with
RAFT-style majority for critical topics and configurable replication factor for others. - Consumer offset & delivery semantics: offsets stored durably; support at-least-once by default, exactly-once via idempotent producers + transactional commit for consumer offsets.
One concrete tradeoff: synchronous replication guarantees durability but increases end-to-end latency; offer topic-level policy to choose sync vs async replication. For large payloads, use pointers to external object store to prevent broker memory/IO explosion.
How to close: summarize SLOs and deployment assumptions, mention operational concerns (compaction windows, monitoring), and say "if I had more time I'd design the metadata service, simulate leader failover scenarios, and sketch client retry/backoff and quota enforcement."
A second angle — Design distributed transactions protocol
The same fundamentals (consensus, durable logs, coordination) apply but constraints shift: cross-shard atomicity demands a coordination protocol. For small-scale, prefer single-partition transactions to avoid distributed commit. For cross-partition, present coordinator-based 2PC built on a replicated log plus leader election; reduce blocking using optimistic concurrency control or cohort-prepared leasing and use timeouts and idempotent commit records to recover. Call out costly failure modes: coordinator crash leaves prepared state requiring careful GC. Tradeoffs: 2PC gives atomicity but sacrifices availability; consider sagas for looser consistency with compensating actions.
Common pitfalls
Pitfall: Designing for global total ordering by default. Total ordering across all keys kills scalability; prefer per-partition ordering and explain why the app actually needs global order.
Pitfall: Ignoring metadata scalability. Storing topic/partition metadata in a single node becomes a bottleneck; design metadata as a small replicated service and quantify limits (metadata ops/sec, number of partitions).
Pitfall: Over-promising exactly-once without implementation detail. Saying "we support exactly-once" without explaining idempotent producers, sequence numbers, and atomic offset commits will lose credibility; show the mechanism (transactional writes + offset commit).
Connections
Interviewers may pivot to adjacent topics like stream processing (stateful processing and time semantics), object storage design (cold-storage lifecycle and GC), or multi-region replication (geo-consistency models and conflict resolution). Be ready to discuss monitoring/playbooks and cost tradeoffs (e.g., hot-spot mitigation vs replication cost).
Further reading
-
[Designing Data-Intensive Applications, Martin Kleppmann] — deep treatment of logs, replication, consensus, and transactions.
-
The Kafka Papers & Confluent Blog — practical patterns for log-based messaging, partitioning, and storage tradeoffs.
Practice questions
Focus area — Special requirement names GPU backend; connect scheduling, batching, KV cache, placement, and failure isolation to Google-scale serving.
What's being tested
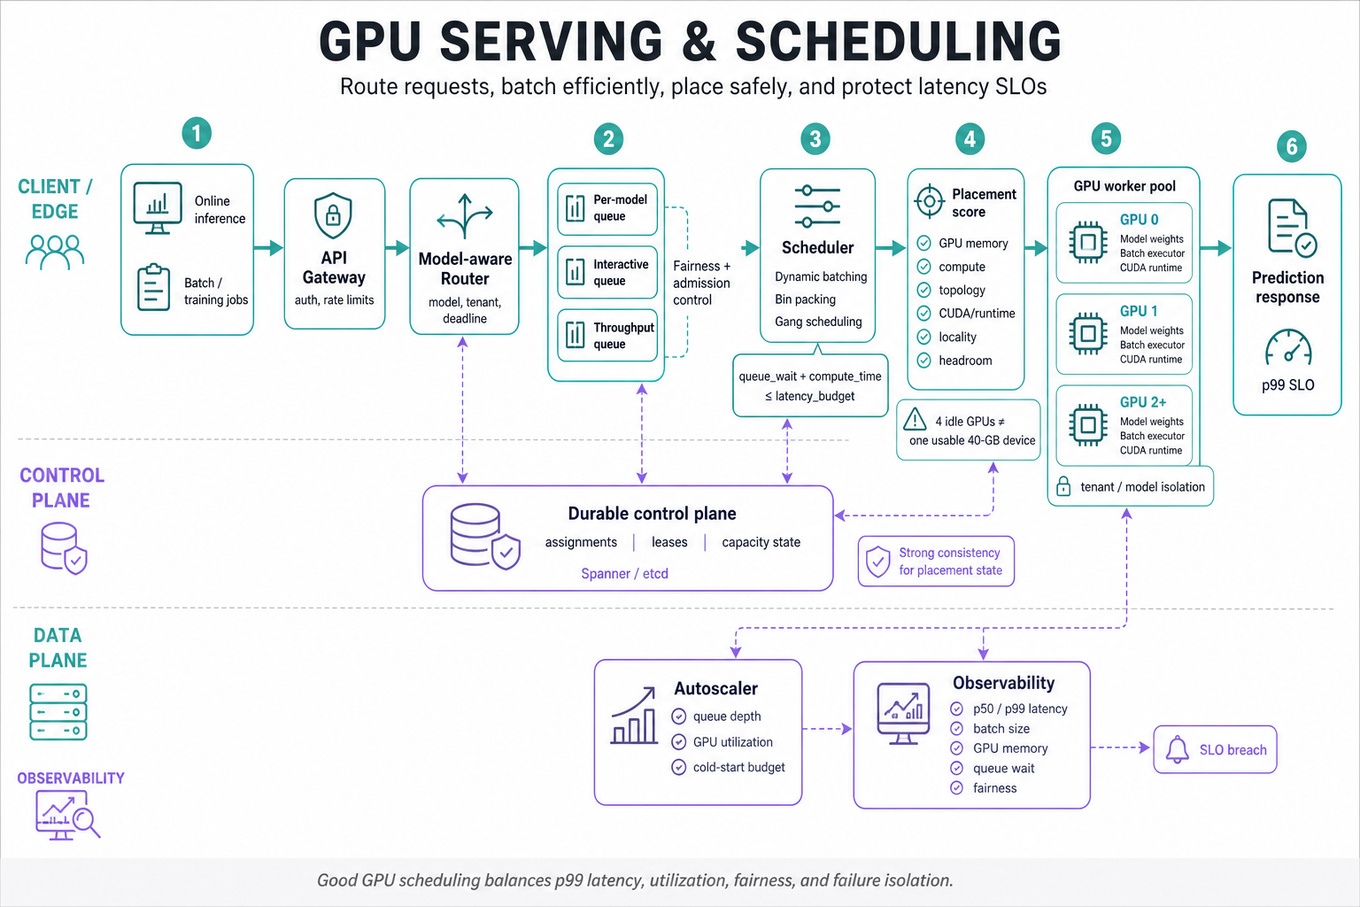
This topic tests whether you can design a reliable distributed backend that schedules scarce accelerators while meeting latency, throughput, and isolation requirements. The interviewer is probing your ability to decompose the system into request routing, queueing, placement, execution, autoscaling, and observability rather than treating “GPU scheduling” as a single queue. Google cares because inefficient GPU utilization directly increases serving cost, while poor scheduling can violate `p99` latency SLOs, starve tenants, or make failures difficult to contain.
Core knowledge
-
Workload characterization determines the scheduler’s objective: online inference usually optimizes admission latency and
`p99`, batch inference optimizes throughput and cost, and training optimizes completion time and gang placement. Ask about model size, GPU memory, request-rate distribution, sequence lengths, deadlines, and preemption tolerance. -
A serving path commonly contains a stateless frontend, model-aware router, per-model queue, scheduler, GPU worker pool, and durable control plane. Keep request metadata and placement state separate from model weights; use systems such as
`Spanner`,`etcd`, or a strongly consistent service for assignments, while data-plane workers remain horizontally scalable. -
Dynamic batching combines requests arriving within a bounded window, amortizing kernel-launch and transfer overhead. The scheduler must cap both maximum batch size and maximum batching delay; a useful constraint is
queue_wait + compute_time <= latency_budget, with separate policies for interactive and throughput-oriented traffic. -
GPU placement is multidimensional: device memory, compute capacity, topology, model weights, CUDA/runtime compatibility, and locality all matter. A node with four nominally idle GPUs may be unusable for a model requiring one contiguous 40-GB device or high-bandwidth peer-to-peer links.
-
Bin packing is the core allocation problem and is generally NP-hard, so production schedulers use heuristics such as first-fit decreasing, best-fit, dominant-resource fairness, or scoring functions over free memory, utilization, topology, and fragmentation. Reserve headroom for runtime allocations; “free memory” from telemetry is not always safely allocatable.
-
Gang scheduling is required when a job needs multiple GPUs simultaneously, such as distributed training or tensor-parallel inference. Reserve all members before launch; otherwise, partial placement creates deadlock-like waste; use leases and rollback when a worker fails during allocation.
-
Multi-tenant fairness requires explicit policy. Weighted fair queuing or DRF (Dominant Resource Fairness) can allocate proportional shares, while priority classes handle production versus best-effort traffic. Add per-tenant quotas, concurrency limits, and aging to prevent low-priority work from starving indefinitely.
-
Preemption improves utilization but has costs: lost GPU cache state, checkpoint overhead, request retries, and tail-latency spikes. Prefer preempting checkpointable batch work rather than active interactive requests, and make retries idempotent with request IDs and bounded retry budgets.
-
GPU execution is often bottlenecked by more than kernels. Account for host-to-device copies, model loading, kernel launch overhead, synchronization, KV-cache growth for generative models, and network transfers. Persistent workers and warm model replicas reduce cold-start latency but consume scarce memory.
-
Autoscaling should use queue depth, queue age, arrival rate, service time, and GPU utilization—not utilization alone. A simple capacity estimate is , where is arrival rate, mean service time, and effective concurrency; validate against
`p95`/`p99`latency because averages hide saturation. -
Backpressure protects the system when demand exceeds accelerator capacity. Bound queues, reject or shed work with an explicit status, enforce deadlines, and avoid unbounded buffering. A queueing-theory warning is that as utilization approaches 1, waiting time rises sharply even when average service capacity still appears sufficient.
-
Fault handling must distinguish request, worker, node, control-plane, and GPU-level failures. Use heartbeats and leases to detect dead workers, quarantine unhealthy devices, replay only safe requests, and reconcile control-plane assignments with actual worker state after a scheduler restart.
-
Observability should expose queue wait, execution time, batch size, admission rejections, GPU memory, SM utilization, device errors, model-load time, and per-tenant fairness. Track
`p50`,`p95`, and`p99`separately by model, region, priority, and request shape; a fleet-wide average can conceal one overloaded model or tenant. -
Isolation can use process boundaries, containers, cgroups, Kubernetes device plugins, or hardware partitioning such as NVIDIA
`MIG`.`MIG`improves predictable partitioning for supported GPUs, but reduces flexibility and may leave unusable slices; time-slicing improves sharing but provides weaker latency and fault isolation. -
Placement should account for failure domains. Spread replicas across hosts, racks, zones, and power domains where availability requires it, but keep distributed jobs within a low-latency GPU topology when performance requires it. Treat locality and resilience as competing objectives, not automatic wins.
Worked example
No titled interview question was supplied, so use this representative prompt: “Design a multi-tenant GPU inference serving platform.” In the first 30 seconds, clarify whether the workload is synchronous inference or batch processing, the target `p99`, model sizes, request rate, GPU types, regional scope, tenant-isolation requirements, and whether stale or rejected requests are acceptable. State an assumption such as synchronous requests with a 200-ms `p99` target, several models, bursty traffic, and multiple GPU classes. Organize the answer around four pillars: request routing and bounded queues, model-aware batching and GPU placement, fairness/autoscaling, and failure handling/observability. Explain that a control plane tracks model versions, worker leases, quotas, and reservations, while workers keep hot model replicas and report health and capacity. Explicitly flag the tradeoff between packing models densely for utilization and reserving spare capacity for fast failover and predictable tail latency. Close by saying that with more time you would quantify capacity using production traces, test overload and node-loss scenarios, and define rollout and rollback behavior for model versions.
A second angle
A related prompt might ask how to schedule distributed training jobs across a heterogeneous GPU fleet. The same principles apply, but the dominant constraint changes from per-request latency to gang placement, checkpoint recovery, and completion time. You would emphasize topology-aware allocation, queue fairness, preemption at checkpoint boundaries, and reservations for all GPUs before launch. Unlike online inference, batching requests is irrelevant, and delayed admission may be preferable to starting a job that cannot obtain its full placement.
Common pitfalls
Pitfall: Treating GPU utilization as the only capacity metric. A device can show low average utilization while queues grow because the wrong GPU memory size, topology, or model-specific workers are saturated; measure queue age, memory pressure, and service time by workload.
Pitfall: Saying “use
`Kubernetes`” without describing the scheduling policy.`Kubernetes`can provide primitives such as device plugins and deployments, but you still need model-aware placement, batching, quotas, gang semantics, leases, and overload behavior.
Pitfall: Ignoring tail latency and failure recovery. “Add more GPUs” is not a complete answer when cold model loads, stragglers, node loss, or unbounded retries create cascading overload; state explicit SLOs and a bounded degradation path.
Connections
The interviewer may pivot to distributed rate limiting, consistent hashing, queueing theory, leader election, distributed tracing, or `Kubernetes` scheduling primitives. For generative models, expect follow-ups on KV-cache placement, continuous batching, tensor parallelism, and admission control.
Further reading
-
Orca: A Distributed Serving System for Transformer-Based Generative Models — introduces iteration-level scheduling and continuous batching for generative inference.
-
Gandiva: Introspective Cluster Scheduling for Deep Learning — useful for GPU-aware scheduling, time slicing, and workload profiling.
-
Dominant Resource Fairness — foundational paper for fair allocation across multiple resource dimensions.
Practice questions
Focus area — Special requirement targets L7; emphasize architectural judgment, migration strategy, capacity, cost, and cross-team decision ownership.
What's being tested
This topic tests whether you can turn ambiguous requirements into a durable architecture and explain the trade-offs behind it. The interviewer is probing for structured reasoning across scalability, reliability, consistency, operability, security, cost, and evolution—not a memorized collection of components. At Google scale, strong Software Engineers must make decisions that remain understandable and safe as traffic, teams, and failure modes grow, while influencing peers through precise technical communication.
Core knowledge
-
Requirements decomposition separates functional requirements from non-functional requirements: traffic, object size, read/write ratio, latency targets, availability, durability, consistency, geographic reach, compliance, and recovery objectives. State assumptions before selecting technologies.
-
Capacity estimation converts vague scale into engineering constraints: requests per second, storage growth, bandwidth, and peak-to-average ratios. Estimate first-order costs such as , then identify the dominant bottleneck rather than optimizing every component.
-
API and data-model design should make invariants explicit. Define ownership, identifiers, idempotency behavior, pagination, versioning, partial failure semantics, and backward compatibility before drawing boxes; a clean API often eliminates architectural complexity downstream.
-
Partitioning distributes load by a stable key, but uneven key popularity creates hotspots. Hash sharding improves balance; range sharding supports ordered scans. For a hot key, consider key salting, read replication, request coalescing, or a deliberately specialized path.
-
Replication and consistency are coupled choices. Synchronous quorum replication improves acknowledged-write durability but adds latency; asynchronous replication reduces write latency but permits stale reads or data loss during failover. Specify which operations require linearizability versus eventual consistency.
-
Consensus systems such as
Spanner-style replicated databases,etcd, orZooKeeperuse protocols such as Raft or Paxos to agree on ordered state changes. Consensus is appropriate for metadata and coordination, not automatically for every high-volume data path. -
Caching reduces backend load and latency but introduces staleness, invalidation, stampedes, and memory pressure. Explicitly choose cache-aside, write-through, or refresh-ahead behavior; use TTLs, request coalescing, bounded negative caching, and jittered expiration where appropriate.
-
Reliability engineering uses redundancy and graceful degradation rather than assuming components never fail. Define an SLO, error budget, timeout budget, retry policy, and load-shedding behavior. Retries require exponential backoff with jitter and strict attempt limits to avoid retry storms.
-
Failure isolation limits blast radius through bulkheads, cell-based architecture, circuit breakers, admission control, and per-tenant quotas. A regional or zonal failure should degrade only the affected partition when possible, not synchronize failure across the entire fleet.
-
Observability must support diagnosis, not merely produce dashboards. Emit structured logs, low-cardinality metrics, traces, dependency health, saturation signals, and correlation IDs. Measure
p50,p95, andp99latency separately; averages hide queueing and tail amplification. -
Deployment and migration strategy are part of the design. Prefer expand-migrate-contract schema changes, dual reads or writes only with reconciliation, feature flags, canaries, and rapid rollback. A design that works only on a clean migration day is incomplete.
-
Trade-off communication should compare alternatives against explicit criteria: latency, availability, consistency, operational burden, cost, implementation risk, and future extensibility. Name the decision, the rejected option, and the condition that would cause you to revisit it.
Worked example
No concrete interview title was supplied, so use this representative prompt: “Design a globally distributed configuration service.” In the first 30 seconds, clarify whether configuration is read-heavy, whether updates require immediate global visibility, the acceptable stale-read window, object size, tenant isolation, and the required availability and durability targets. Organize the answer around four pillars: versioned APIs and data model, regional serving and replication, caching and invalidation, and operational safety. State an invariant such as “a client never observes a version older than the version it has already acknowledged,” if session-level monotonic reads matter. A reasonable design could use a strongly consistent metadata store for configuration versions and regional read replicas or caches for the hot read path. Flag the central trade-off explicitly: synchronous cross-region replication gives stronger visibility guarantees but increases write latency and makes partitions harder to tolerate; asynchronous replication improves availability but requires a defined staleness contract. Discuss rollout controls, audit history, authentication, quotas, and safe rollback rather than treating the service as only a key-value map. Close by saying that, with more time, you would quantify regional failover behavior, model worst-case cache invalidation load, and run a game day for split-brain and stale-configuration scenarios.
A second angle
The same reasoning applies to a globally distributed feature-flag service, but the constraints shift toward fast reads, safe gradual rollout, and tenant-specific evaluation. You would likely favor local evaluation from periodically refreshed snapshots because requiring a remote call on every request creates unacceptable tail latency and a new availability dependency. The design must make flag versions, targeting rules, kill switches, and rollback semantics explicit. A stale flag may be acceptable for ordinary experiments but unacceptable for a security or emergency-disable flag, so consistency should be selected per flag class rather than globally. This illustrates why architecture decisions should follow operation-specific guarantees instead of a single slogan such as “strong consistency everywhere.”
Common pitfalls
Pitfall: Choosing
Kafka,Redis, or a consensus database before defining latency, consistency, and failure requirements is an analytical mistake. Start with invariants and workload shape, then explain why a technology satisfies them.
Pitfall: Presenting a polished diagram without narrating failure behavior is a communication mistake. Walk through timeout, duplicate request, replica loss, partition, overload, and recovery paths so the interviewer can see how the system behaves when components are unhealthy.
Pitfall: Stopping at component selection is a depth mistake. At senior and staff levels, cover migration, observability, capacity growth, ownership boundaries, rollback, and the operational mechanism that prevents a locally reasonable change from creating fleet-wide failure.
Connections
An interviewer may pivot to distributed transactions, CAP trade-offs, cell-based architecture, SLO and error-budget design, or schema and API evolution. Be ready to connect the architecture to concrete algorithms such as quorum reads, consistent hashing, Raft, idempotency keys, and queue-based backpressure.
Further reading
-
Designing Data-Intensive Applications by Martin Kleppmann — rigorous coverage of replication, partitioning, consistency, transactions, and stream processing.
-
Site Reliability Engineering by
Google— SLOs, error budgets, incident response, capacity, and production operational trade-offs. -
The Tail at Scale by Dean and Barroso,
Communications of the ACM(2013) — explains why distributed tail latency requires hedging, isolation, and careful fanout design.
Practice questions
Software Engineering Fundamentals
Focus area — Base concurrency is solid, but leases, fair scheduling, work stealing, and idempotent task execution need L7 cloud refresh.
What's being tested
These problems test building and reasoning about an async primitive (like CompletableFuture) and scheduling: safe callback registration, correct completion state machine, and efficient timer/task multiplexing onto a thread-pool. Interviewers probe race-free state transitions, cancellation, ordering guarantees, and scalable timer/scheduler data structures.
Patterns & templates
-
State machine with explicit states (e.g., PENDING → COMPLETING → COMPLETED/FAILED/CANCELLED) and a single CAS transition per completion to avoid races.
-
Callback list appended atomically with
compareAndSetand drained by the thread that wins completion, avoiding locking on hot path. -
Use volatile for result/state visibility and minimal locking; prefer lock-free for low-latency futures, fallback to short critical sections when necessary.
-
Implement timers with a min-heap priority queue for correctness, or a timer wheel for large-scale (~10^6 timers) amortized O(1) ticks.
-
Use ForkJoinPool / work-stealing for parallel array processing; prefer divide-and-conquer recursively to maximize locality and CPU utilization.
-
Cancellation: mark state then attempt to remove scheduled tasks; for heap-based timers, use lazy deletion flags to avoid O(n) removals.
-
Batch wakeups: coalesce scheduled callbacks and run them on a worker thread (
execute()), avoid running user callbacks under internal locks to prevent deadlocks.
Common pitfalls
Pitfall: Failing to make state transitions atomic leads to double-completion or lost callbacks when two threads try to complete concurrently.
Pitfall: Running user callbacks while holding internal locks causes deadlocks or long GC pauses; always invoke callbacks outside locks.
Pitfall: Assuming
notify()without rechecking condition — handle spurious wakeups and always loop on the predicate when usingwait()/notify().
Practice these
The practice cards below cover the canonical variants — solve all of them and time yourself.
Practice questions
Embedded-to-Cloud Backend Integration
Focus areaFocus area — You called out embedded for cloud; cover device constraints, firmware/API contracts, telemetry, rollouts, and backend reliability boundaries.
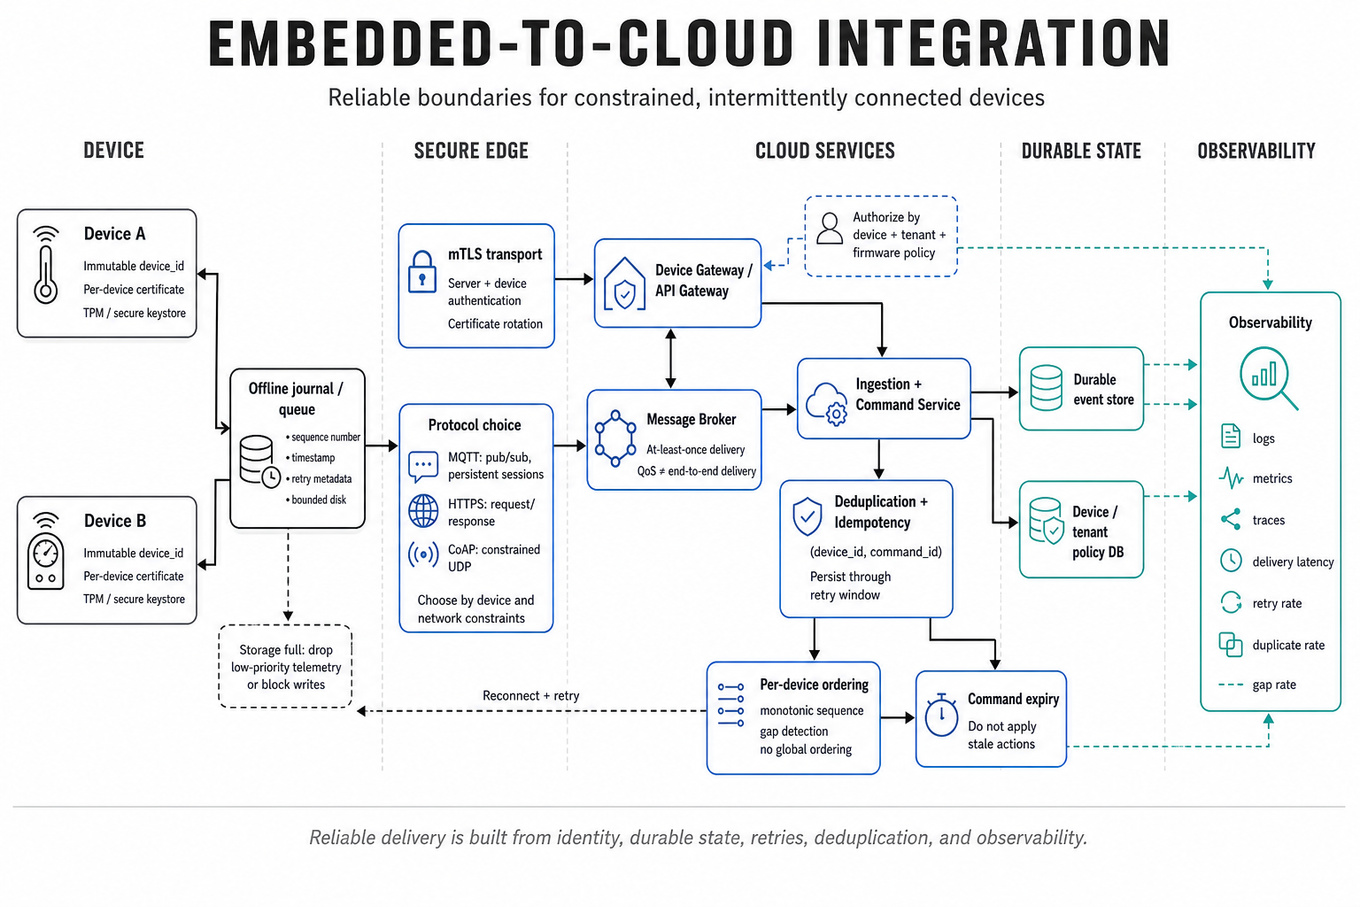
What's being tested
This topic tests whether you can design a reliable distributed boundary between constrained, intermittently connected embedded devices and elastic cloud services. The interviewer is probing your ability to reason about device identity, protocol selection, asynchronous communication, retries, ordering, offline behavior, security, and observability as one system rather than isolated components. Google cares because failures at this boundary are common, expensive, and difficult to reproduce: devices may have limited CPU, storage, power, and connectivity while the backend must serve millions of heterogeneous clients safely.
Core knowledge
-
Device identity and authentication must be separate concepts: assign each device a stable immutable identifier, authenticate it with a per-device credential or certificate, and authorize its operations using device, tenant, and firmware policy. Avoid shared fleet-wide secrets.
-
Mutual TLS (mTLS) is a strong default for device-to-cloud connections because the device authenticates the server and the server authenticates the device. Use certificate rotation, short-lived credentials where practical, revocation strategy, and secure key storage such as a
TPMor hardware-backed keystore. -
Protocol selection follows constraints.
MQTTprovides lightweight publish/subscribe, persistent sessions, QoS levels, and retained messages;HTTPSis simpler for request/response and broad infrastructure compatibility;CoAPsuits constrained networks, often overUDP. Do not claim protocol QoS guarantees end-to-end application delivery. -
At-least-once delivery is usually the practical choice over unreliable networks. Retries create duplicates, so every mutating operation needs an idempotency key, such as
(device_id, command_id), persisted long enough to cover the retry window. “Exactly once” is generally an application-level illusion built from deduplication and durable state. -
Offline-first behavior requires a local queue or journal with bounded disk usage, sequence numbers, timestamps, and retry metadata. Define what happens when storage fills: drop oldest telemetry, drop lowest-priority records, or block writes. Commands should have expiration times so stale actions are not applied after reconnection.
-
Ordering is scoped, not global. A per-device monotonic sequence number can detect gaps and duplicates, but reconnects and multiple backend workers complicate ordering. If commands must be serialized, partition processing by
device_idor use a per-device state machine; do not impose a single global ordering across the fleet. -
The ingestion path should separate connection handling from durable processing: gateway or broker accepts traffic, durable buffering absorbs bursts, consumers validate and persist events, and downstream workers perform side effects. Use bounded queues, backpressure, admission control, and dead-letter handling rather than unbounded memory.
-
State modeling should distinguish desired state, reported state, and command execution state. A device may report version 7 while the cloud desires version 9; reconciliation compares versions and issues a new operation rather than assuming a synchronous request succeeded.
-
Concurrency control prevents stale updates from overwriting newer state. Use device sequence numbers, version checks, compare-and-set semantics, or a per-device actor. A last-write-wins timestamp is unsafe when clocks are skewed or messages arrive out of order.
-
Reliability targets should be explicit: connection success rate, command acceptance rate, command completion latency, telemetry freshness, duplicate rate, and error rate by firmware version and network type. Track
p50,p95, andp99; averages hide tail failures concentrated in poor connectivity regions. -
Fleet-scale rollout needs staged deployment, compatibility checks, resumability, and rollback. Firmware or configuration updates should be chunked, cryptographically verified, power-loss safe, and protected against bricking; the backend should enforce rollout limits and stop conditions.
-
Observability and debugging require a correlation ID spanning device logs, gateway records, broker messages, and backend processing. Use structured logs, metrics, and traces where feasible, and a device-side diagnostic ring buffer. Redact secrets and avoid assuming clocks are synchronized.
Worked example
Design an embedded-to-cloud backend for remote device commands and telemetry. In the first 30 seconds, clarify device count and growth, connectivity patterns, command latency requirements, telemetry volume, offline duration, security requirements, and whether commands may be duplicated or delayed. I would state an assumption such as one million devices, intermittent connectivity, at-least-once delivery, and commands that must not execute after a defined expiration time. I would organize the design around device authentication and protocol termination, durable ingestion and command delivery, device-side offline queues, and per-device state plus observability. I would use MQTT for long-lived bidirectional sessions, a broker or gateway layer for connection management, and durable cloud storage or streaming infrastructure behind it rather than having application workers hold device connections. The explicit tradeoff is choosing at-least-once delivery with idempotent command processing instead of pursuing end-to-end exactly-once semantics, which would add complexity without preventing every physical-world duplicate effect. I would explain reconnect behavior, bounded queues, sequence numbers, dead-letter handling, and certificate rotation before discussing capacity estimates. If I had more time, I would add failure-injection tests for broker outages, power loss during updates, clock skew, certificate expiry, and a staged firmware rollout.
A second angle
Design a cloud service that maintains desired configuration for intermittently connected devices. The framing shifts from high-throughput telemetry ingestion to reconciliation of durable state under disconnection and conflicting updates. Model desired configuration, reported configuration, and operation status separately, with version numbers and a clear authority rule for device-local versus cloud-managed changes. A reconnecting device should fetch the latest desired version, apply it transactionally if possible, report success or failure, and remain safe if the same configuration is delivered repeatedly. The key constraint is not merely message delivery; it is convergence, compatibility across firmware versions, and preventing an old device response from overwriting newer reported state.
Common pitfalls
Pitfall: Saying “
MQTTQoS 2 guarantees exactly-once execution.” It only defines protocol-level delivery behavior between participants; the application still needs durable deduplication and idempotent physical actions.
Pitfall: Presenting a synchronous
RESTrequest from the cloud to the device as if the device were always reachable. Stronger answers model commands as durable, expiring jobs whose acceptance and execution are separate states.
Pitfall: Discussing encryption without explaining key provisioning, rotation, revocation, or recovery after credential compromise. Name the trust anchor, certificate lifecycle, authorization boundary, and fleet-level containment plan.
Connections
An interviewer may pivot to distributed-systems consistency, event-driven architecture, backpressure, zero-trust security, or firmware update safety. Be ready to connect per-device ordering and idempotency to stream partitioning, transactional state transitions, and failure recovery.
Further reading
-
Google SRE Book — “Handling Overload” — practical treatment of backpressure, overload control, and graceful degradation.
-
MQTT Version 5.0 Specification — authoritative details on sessions, QoS, retained messages, and delivery semantics.
-
Designing Data-Intensive Applications by Martin Kleppmann — strong foundations for logs, replication, streams, consistency, and distributed failure modes.
Practice questions
Behavioral & Leadership
Focus area — L7 interviews require evidence of scope, influence, and trade-off judgment; keep leadership stories explicit and metric-backed.
What's being tested
Interviewers are probing your ability to take ownership of a technical area while managing ambiguity, tradeoffs, and multiple stakeholders. They want to see clear problem framing, evidence-based tradeoff analysis, pragmatic delivery plans (including risk mitigation), and effective communication under pressure. For a Software Engineer this means demonstrating technical judgment that leads to shipping reliable code, resolving incidents, and aligning cross-functional partners without delegating the engineering responsibilities you own.
Core knowledge
-
Ownership vs. accountability: Ownership means owning technical decisions, rollout, monitoring, and remediation; accountability is accepting follow-through until metrics show recovery or launch success.
-
Clarifying goals fast: Ask for the success metric (e.g.,
p95latency, error rate, adoption %, revenue impact), the deadline, and non-negotiable constraints (privacy, compliance, infra limits). -
Stakeholder map: Identify approvers, implementers, and consumers; capture names, acceptance criteria, and communication cadence in a one-page decision log or RFC.
-
Risk assessment formula: Use Risk = Probability × Impact; quantify impact (user count, revenue/hour, SLA penalty) and use it to prioritize fixes vs. features.
-
Incremental delivery patterns: Use feature flags, canary rollout, and progressive exposure to limit blast radius; require rollback plan and quick toggle in
Git-driven CI/CD. -
Observability and SLOs: Define dashboards and alerts tied to
SLO/SLAandp99/p95metrics; ensure alerts map to on-call viaPagerDutyand have runbooks. -
Incident & postmortem hygiene: Run blameless postmortems, list corrective actions with owners and deadlines, and track them in
JIRA. Include root cause, contributing factors, and time-to-detect/repair. -
Tradeoff language: Frame decisions as three-part: benefit, cost (engineering/time/opportunity), and mitigation. Quantify when possible (e.g., "adds 2 engineer-weeks, reduces error rate by 60%").
-
Communication primitives: Use asynchronous docs (
Google Docs/RFC) for detailed tradeoffs, short syncs for alignment, and single-owner status updates for escalation; summarize decisions in a TL;DR at top. -
When to escalate: If risk > threshold (e.g., potential customer-facing outage or >X% revenue impact), escalate to product or SRE managers immediately; otherwise handle within the squad with clear checkpoints.
-
Code-quality gates: Define minimal acceptable CI checks (unit tests, linters, integration smoke) and when to accept tech debt with a remediation timeline.
-
Ambiguity tactics: Propose explicit assumptions, prototype the riskiest unknown for one sprint, and agree on acceptance criteria to prevent rework.
Worked example — "Answer leadership and ambiguity scenarios"
First 30 seconds: ask for the measurable outcome ("which metric moves define success?"), timeline, and constraints (privacy, infra, dependent teams). Declare assumptions you will use if not specified (e.g., "assume existing API throughput handles +30% load"). Structure your answer around three pillars: (1) clarify and scope — write a one-paragraph objective and list open questions; (2) build & mitigate — deliver a minimal increment behind a feature flag with monitoring and rollback; (3) align & communicate — convene stakeholders for an initial decision and send an RFC summarizing choices and risks. Call out a central tradeoff explicitly: speed-to-production vs. long-term maintainability — choose incremental delivery if you must meet a deadline, but require a follow-up tech task to eliminate temporary scaffolding. Close by stating next steps and what you'd do with more time: broaden tests, run load tests, and coordinate a staged rollout with PagerDuty runbook updates.
A second angle — "Answer leadership and quality tradeoff questions"
The same framing applies but the emphasis shifts to explicit quality thresholds: begin by quantifying acceptable risk (e.g., target p99 latency and minimum test coverage). Use the risk formula to justify cutting scope: prefer shipping a narrower feature with strong observability and rollback capability over a full-featured release with brittle tests. Propose a temporary mitigation (rate limit, circuit breaker) and a technical debt ticket with priority and estimated cost. In negotiation, offer concrete alternatives and associated timelines so stakeholders choose based on quantified tradeoffs rather than abstract assurances.
Common pitfalls
Pitfall: Focusing solely on the technical solution and ignoring stakeholder alignment.
If you produce a great technical plan but haven't secured stakeholder buy-in, the project stalls or gets blocked. State who needs to approve what, surface tradeoffs early, and propose a sync cadence so technical work and stakeholder expectations remain aligned.
Pitfall: Claiming unconditional ownership without delegation or follow-through.
Ownership isn't doing everything alone — it's making clear who owns which subtasks and tracking them until resolution. Use JIRA tickets with owners and due dates; escalate only when commitments miss agreed checkpoints.
Pitfall: Over-engineering to avoid ambiguity.
Building a full solution to remove all unknowns wastes time. Instead, prototype the riskiest unknown, iterate, and use feature flags and canaries to reduce blast radius while you refine the design.
Connections
Interviewers can pivot into incident response and SRE practices (runbooks, SLO design), system design tradeoffs (latency vs. throughput), or cross-team influence topics (how you get alignment without authority). Demonstrating fluency in those adjacent areas makes your behavioral answers more actionable.
Further reading
-
Site Reliability Engineering (Google SRE book) — practical guidance on incident response, SLOs, and blameless postmortems.
-
Accelerate (DORA) — evidence on delivery metrics, tradeoffs between speed and stability, and measurable engineering performance.
Practice questions
Online Assessment — 6 min
Coding & Algorithms
Self-rating is strong, but OA exposure and no solved signals make this a focused refresh on edge cases and binary-search boundaries.

What's being tested
These problems test frequency-counting and anagram/signature reasoning for strings, efficient sliding-window checks over substrings, and membership lookups using hash maps. Interviewers probe algorithmic choices (O(n) vs O(n·k)), correct edge-case handling, and clean iteration/parsing for large inputs.
Patterns & templates
-
Sliding window on contiguous substrings — O(n) two-pointer expand/contract; maintain counts and window invariants to avoid re-scanning.
-
Frequency signature via fixed-size arrays or
Counter— store counts as tuples or serialized keys for O(1) comparison on alphabet-limited strings. -
Hash set / map for membership — pre-hash dictionary words or signatures to get average O(1) membership tests during enumeration.
-
Bitmask / digit mask for digits 0–9 — represent presence with a 10-bit int, enabling O(1) union/intersection checks across numbers.
-
Two-pointer on arrays for monotonic constraints — move left/right and maintain aggregate (sum/count) for O(n) feasibility checks.
-
Binary search over answer space — convert "max size" questions to monotone predicate, run O(n) check per mid for total O(n log n).
-
Single-pass string parsing for snake_case→camelCase — build result in-place, handle separators and capitalization in O(n) time and O(1) extra space.
Common pitfalls
Pitfall: Comparing full count arrays per window naïvely makes algorithms O(n·k); instead update counts incrementally on pointer moves.
Pitfall: Forgetting to canonicalize signatures (order or normalized tuple) causes false negatives when checking anagram membership.
Pitfall: Not validating separators/edge cases (empty string, consecutive underscores) in parsing tasks leads to incorrect outputs or crashes.
Practice these
The practice cards below cover the canonical variants — solve all of them and time yourself.
Practice questions