Statistical Inference For Proportions And Confidence Intervals
Asked of: Data Scientist
Last updated
What's being tested
These prompts test a candidate's ability to do principled statistical inference for proportions: set up and run binomial-based hypothesis tests, compute confidence intervals, and reason about reach/expectation under random allocation. Interviewers check that you can choose appropriate approximations (normal/Poisson/exact), compute/interpret p-values, report confidence intervals, and assess practical significance and power for product decisions. At Meta, a Data Scientist must translate small-sample statistical answers into product-facing statements about lift, risk, and whether an experiment warrants rollout.
Core knowledge
-
Binomial model: individual trials ~ Bernoulli(p); counts follow . Use when trials are independent and identical with fixed n and p. Edge case: dependence (e.g., repeated users) breaks this.
-
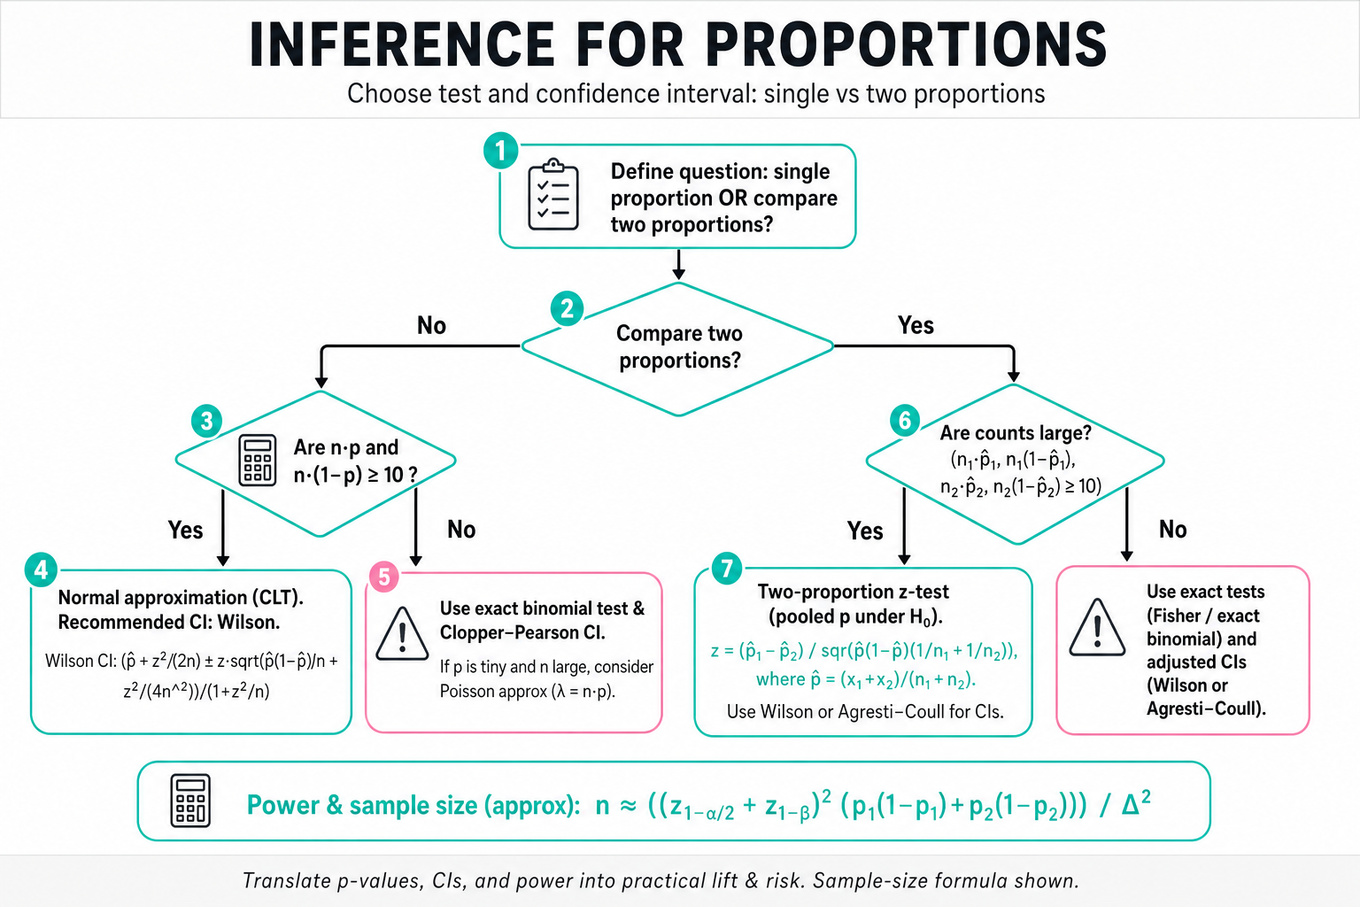
Normal approximation / CLT: for large n, . Use when –10; otherwise use exact or adjusted intervals.
-
Two-proportion z-test: test with pooled estimate ; test statistic and two-sided p-value .
-
Confidence intervals: common choices are Wald (naïve), Wilson (recommended), and Agresti–Coull; Wilson has better coverage for moderate/low n or p near 0/1. Wilson interval:
-
Exact binomial test: compute tail probability from Binomial CDF when normal approx is invalid; use for small n or extreme p (e.g., conversions).
-
Poisson approximation: when n large and p small ( modest), Binomial; useful for expected impressions/reach calculations.
-
Power and sample size: for target absolute lift , approximate required n per arm: Always express power for practical-effect sizes.
-
Multiple comparisons & sequential testing: control family-wise error via Bonferroni or use FDR (Benjamini–Hochberg); for monitoring use alpha spending or sequential methods (e.g., O’Brien–Fleming) to avoid inflated Type I.
-
Bayesian beta-binomial: conjugate prior Beta(a,b) gives posterior Beta(a+x,b+n-x). Use to compute credible intervals, posterior probability of uplift > 0, or small-sample regularization.
-
Practical vs statistical significance: report absolute and relative lift, baseline rate, and expected incremental events; quantify uncertainty in both statistical and product-relevant units (e.g., incremental conversions per million impressions).
-
Random allocation exposure modeling: expected impressions per user = if total impressions and random over R users, or treat each user's impressions as Binomial/Poisson depending on replacement assumptions; probability of at least one exposure is .
-
Reporting standards: always state assumptions (independence, randomization, unit of analysis), show raw counts and intervals, and perform sanity checks (e.g., expected vs observed reach).
Worked example — Calculate Expected Impressions and Probability for Users
Start by clarifying assumptions: are impressions placed uniformly at random with replacement over users (independent draws) or without replacement? Define unit of analysis (user-level). Skeleton: (1) model impressions per user as Binomial(n=m, p=1/R) or Poisson() for large R, (2) compute expectation and probability of at least one , (3) compute expected unique reach = . Flag tradeoffs: if impressions are correlated by time or user caps, independence fails and Poisson overestimates variance. Close by stating what product decisions follow (e.g., estimated reach vs frequency caps) and what extra data you'd request (impression timestamps, dedup keys) if available.
A second angle — Determine Superiority of Model A Using Hypothesis Testing
Here the framing is a two-proportion comparison of model outcomes (click/convert rates). You'd check sample sizes to justify the normal approximation, compute pooled vs unpooled variance depending on H0 formulation, and report both p-value and a 95% confidence interval for the difference to show magnitude. Important tradeoff: statistical significance may be tiny absolute lift with negligible business value; always convert to expected incremental conversions per million impressions. If sequential model comparisons occur (many models), recommend multiplicity correction or Bayesian model comparison to avoid false discoveries.
Common pitfalls
Pitfall: treating tiny p-values as automatically important.
Confusing statistical significance with product impact is common. Always convert the uplift and CI into absolute events and expected business metric changes before recommending rollout.
Pitfall: blind use of the Wald interval or pooled z-test for small counts.
For small n or rare events (CTR << 1%), the normal approximation under-covers; use Wilson/Agresti–Coull or exact tests instead.
Pitfall: ignoring dependence and the correct unit of analysis.
Aggregating multiple impressions per user without accounting for intra-user correlation underestimates variance; use user-level metrics or clustered standard errors and state this assumption to the interviewer.
Connections
This topic often segues to sequential A/B testing, Bayesian decision rules (expected loss vs Type I/II tradeoffs), or metric design (defining conversion events and aggregation at the correct unit). Be prepared to move from inference to product impact and experiment monitoring.
Further reading
-
Agresti, A. & Coull, B. (1998). "Approximate is Better than 'Exact' for Interval Estimation of Binomial Proportions" — explains Wilson/Agresti–Coull intervals and their superior coverage.
-
Casella, G. & Berger, R. L. (2002). "Statistical Inference" — comprehensive theory for hypothesis testing, intervals, and decision-theoretic framing.
Practice questions
- Test two models' proportions for significanceMeta · Data Scientist · Onsite · medium
- Estimate CTR lift with binomial tests and errorsMeta · Data Scientist · Onsite · hard
- Determine Superiority of Model A Using Hypothesis TestingMeta · Data Scientist · Onsite · medium
- Explain Central Limit Theorem's Importance in A/B TestingMeta · Data Scientist · Onsite · easy
- Estimate Lift and Significance in Facebook Ad CampaignsMeta · Data Scientist · Onsite · medium
- Interpreting confidence intervals to choose a treatmentMeta · Data Scientist · Onsite · medium
- Expected impressions per user under random assignmentMeta · Data Scientist · Onsite · easy
- Calculate Expected Impressions and Probability for UsersMeta · Data Scientist · Onsite · easy
Related concepts
- Statistical Inference For Product AnalyticsStatistics & Math
- Statistical Inference, Power, And Metric UncertaintyStatistics & Math
- Central Limit Theorem, Confidence Intervals, And PowerStatistics & Math
- Statistical Inference, Power, And Confidence IntervalsStatistics & Math
- Power Analysis And Statistical InferenceStatistics & Math
- Statistical Inference, Regression, And ProbabilityStatistics & Math