OpenAI Software Engineer Interview Prep Guide
Everything OpenAI actually asks Software Engineer candidates — concept walkthroughs, worked examples, and the real interview questions, drawn from candidate reports. Free to read.
Last updated
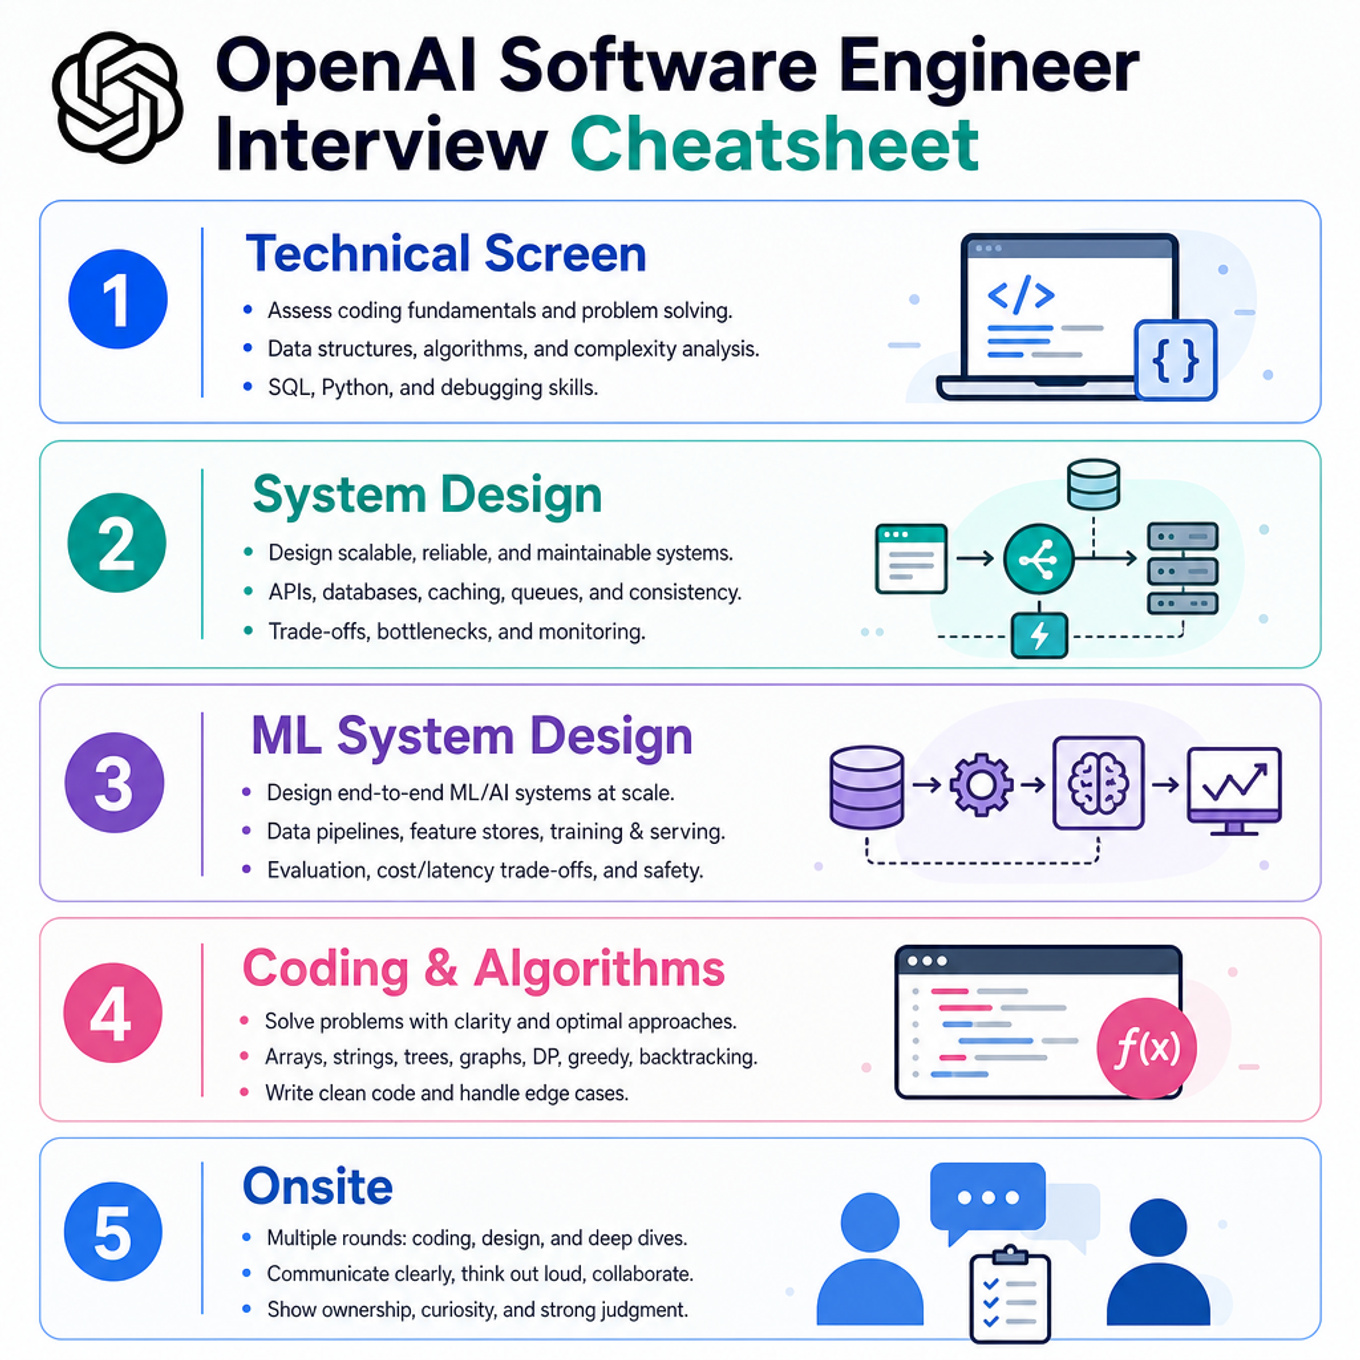
Focus most on OpenAI-shaped systems: GPU credit scheduling, streaming conversational AI, production ML evaluation/safety, and API gateway rate limiting, plus coding implementation drills where your 3/5 rating and zero solved questions show risk. Because all explicit ratings are 3/5 and no solved-history signal exists, nothing is treated as a true strength; CI/CD, payments, messaging, telemetry, cloud IDEs, in-memory DBs, and versioned graphs stay at normal review depth. The OpenAI-specific emphasis is on multi-tenant GPU capacity, token-streaming UX and cancellation, safe/evaluated ML rollouts, and LLM API abuse prevention. With a one-month timeline, plan roughly 3–4 focused study blocks per week, using the 57-minute technical-screen pass first and the 24-minute onsite systems pass as a recurring refresher.
Technical Screen — 57 min
System Design
GPU Credit Ledgers And Schedulers
Focus areaFocus area — OpenAI-specific GPU capacity, quota, and scheduling likely matter; your System Design rating is 3/5 with no solved system-design questions.

What's being tested
Candidates must show practical mastery of designing a multi-tenant, real-time resource accounting and scheduling system that prevents double-spend, enforces budgets, and schedules heterogeneous GPUs. Interviewers probe distributed-systems primitives (consistency, partitioning, idempotency), APIs and failure modes (retries, node failure, clock skew), and scheduler algorithms (gang scheduling, bin-packing, fairness). Expect the interviewer to evaluate clear tradeoffs between strict correctness (no overspend) and scalable, low-latency allocation paths.
Core knowledge
-
Credit ledger data model: per-tenant balance, per-transaction idempotency key, monotonic sequence or vector timestamp to order updates; store in a strongly consistent partition (
etcd,Spanner,PostgreswithSELECT FOR UPDATE) when linearizability is required. -
Idempotency: clients must send an idempotency key; server stores (key -> result) for retry-safe semantics; eviction policy based on TTL and transaction finality to bound storage.
-
Reservation vs commit: implement a two-phase flow: reserve (temporary lease reducing available balance) then commit (final deduction), supporting rollback on node failure; leases expire automatically to avoid stuck resources.
-
Fast-path local checks: use a cached bucket/token (leaky token-bucket) per tenant for sub-second approvals; reconcile with authoritative ledger periodically to bound over-commit risk.
-
Distributed partitioning: partition ledger by tenant-id or account-hash; scale to millions by sharding and routing RPCs to the shard owner, minimizing cross-shard transactions.
-
Heterogeneous GPU costing: normalize GPUs using cost-rate (credits/sec) per device type; billing = sum(cost_rate_i * seconds_used_i). Support preemption and partial refunds with precise time accounting.
-
Scheduler algorithms: for multi-GPU jobs use gang scheduling + bin-packing heuristics (best-fit decreasing) or Dominant Resource Fairness (DRF) for fairness; backfilling reduces fragmentation for short jobs.
-
Atomicity & concurrency control: for strict correctness prefer linearizable updates (compare-and-set, serializable DB txns); for higher throughput consider optimistic allocation with bounded reconciliation windows.
-
Failure modes: handle node crashes (leases expire), network partitions (reject writes if quorum not available for linearizability), and clock skew (use server timestamps or monotonic counters).
-
Observability & SLAs: track
p99allocation latency, double-spend incidents, reconciliation drift, and per-tenant throttles; emit events toKafka/ingestion pipeline for billing pipeline. -
Security & multi-tenancy: authenticate calls via strong identity (mTLS, IAM), enforce RBAC for transfers, and audit every ledger mutation for dispute resolution.
-
Scaling numbers: for N tenants ~10M, keep per-tenant metadata in a scalable KV store; avoid multi-tenant cross-shard txns—they kill throughput. Use asynchronous reconciliation and incremental snapshots for export.
Worked example — "Design GPU credit allocator"
First 30 seconds: ask expected scale (tenants/sec, concurrent allocs), consistency SLA (strict no-overspend vs eventual), GPU heterogeneity, and whether allocations are preemptible. Declare assumptions: target 100k allocs/sec, strict per-tenant no-overspend, heterogeneous GPUs with known cost rates.
Skeleton of an answer:
-
API design:
Reserve(tenant, amount, idempotency_key),Commit(reservation_id),Release(reservation_id); synchronous response for Reserve. -
Ledger implementation: shard by tenant; each shard owner provides linearizable reservations via
SELECT FOR UPDATEoretcdCAS. Store reservations with TTL. -
Fast-path: local token-bucket cache for micro-requests; falls back to authoritative Reserve RPC when cache misses.
-
Scheduler integration: scheduler requests reservations for GPU set (gang), scheduler commits when job starts, releases on preemption.
Explicit tradeoff: using strong linearizability prevents double-spend but requires cross-shard coordination for transfers—choose to ban cross-shard atomic transfers or implement async transfer with temporary credit holds. Closing: if more time, prototype shard-split logic, run chaos-testing (node failures, retries), and design reconciliation jobs to detect and correct drift.
A second angle — "Design credit balance with vector-clock expirations"
This variant emphasizes concurrent updates from multiple disconnected clients and expiry semantics. Use vector clocks or per-shard monotonic counters to track causality of credit events; model balance as an eventually-consistent CRDT only if occasional overspend is acceptable. To support expirations, attach expiry metadata to each credit delta and garbage-collect with causal ordering to avoid prematurely dropping recent updates. The primary shift: when strict single-source ordering is impossible, rely on deterministic merge functions and compensation transactions, and be explicit about allowed windows for inconsistency.
Common pitfalls
Pitfall: Relying solely on a cheap local cache for immediate approvals without any authoritative reconciliation. This leads to silent double-spend when many nodes grant allocations simultaneously; prefer bounded fast-path windows and periodic reconciliation or pessimistic reservations for high-value ops.
Pitfall: Forgetting idempotency keys and storing results only transiently. Retries will create duplicated charges; store idempotency mapping with TTL and ensure idempotent handlers are deterministic.
Pitfall: Designing the scheduler independently from credit semantics. Scheduling multi-GPU jobs requires atomic reservations across multiple GPUs (gang scheduling); otherwise partial allocations result in wasted resources and complex refunds. Flag the need for a coordinated reserve-and-commit for multi-device jobs.
Connections
Interviewers may pivot to adjacent topics: designing the billing/export pipeline and offline reconciliation (data engineering), or to fine-grained scheduler optimization (resource management research like Borg/Omega). They may also ask about monitoring and alerting thresholds (SRE concerns).
Further reading
-
Designing Data-Intensive Applications — Martin Kleppmann — strong treatment of consistency, partitioning, and CRDTs for ledger-like systems.
-
Dynamo: Amazon’s Highly Available Key-value Store — background on partitioning, eventual consistency, and vector-clock techniques.
-
Stripe: Idempotency keys — practical pattern and tradeoffs for retry-safe financial operations.
Practice questions
-
LLM API Gateway, Rate Limits, And Abuse Prevention (Focus) — covered in depth under Onsite below.
-
CI/CD Workflow Orchestration — covered in depth under Onsite below.
-
Cloud IDE And DevBox Sandboxing — covered in depth under Onsite below.
ML System Design
Streaming Conversational AI Systems
Focus areaFocus area — Central to OpenAI product surfaces; emphasize streaming, cancellation, privacy, and safety despite no explicit ML rating.
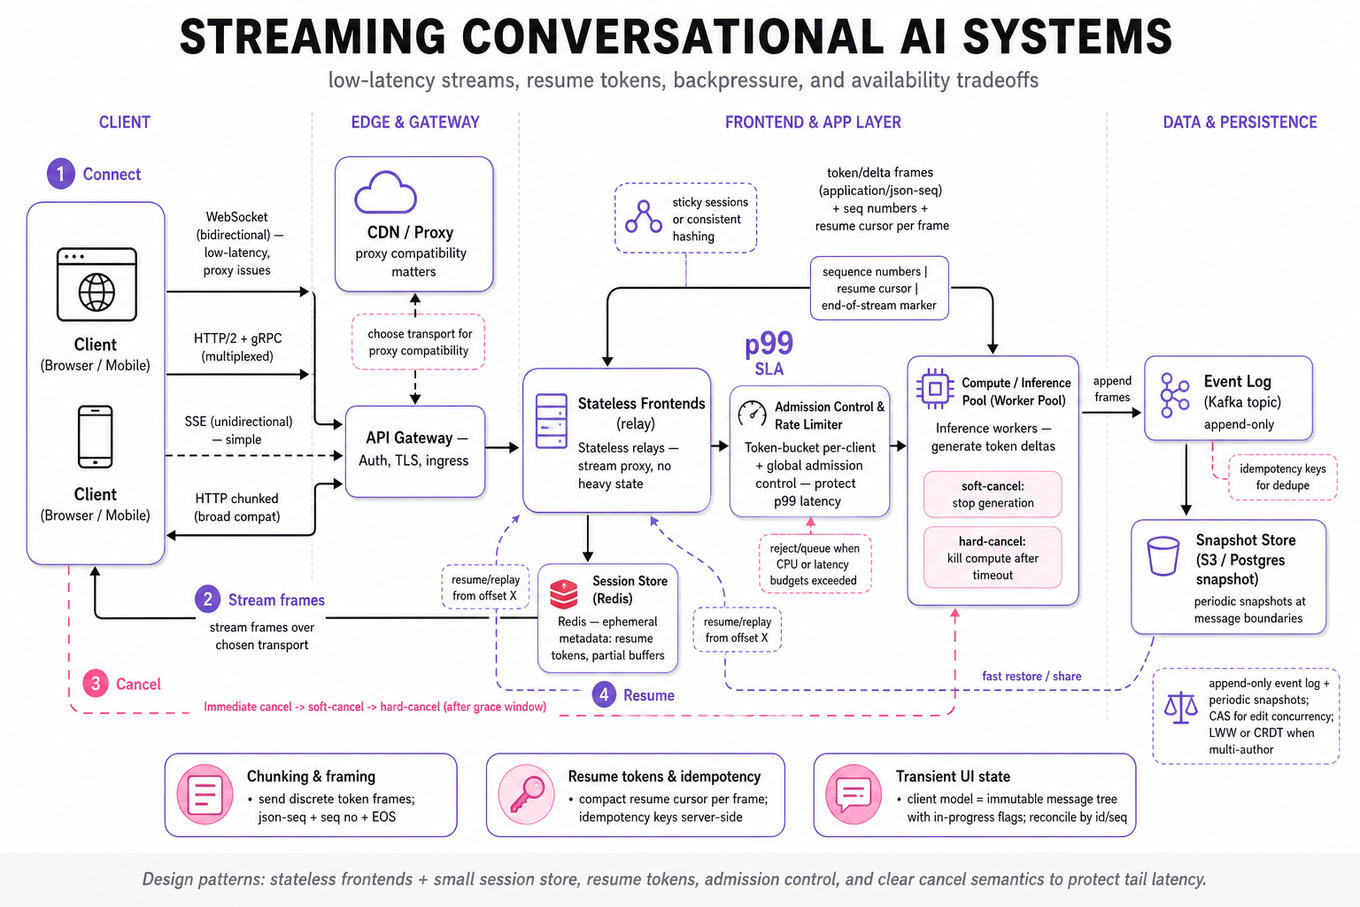
What's being tested
Candidates must show end-to-end engineering judgment for building low-latency, robust streaming chat systems: real-time transport choices, transient client state management, concurrency and cancellation, backpressure/admission control, and availability tradeoffs. Interviewers probe whether you can design practical, testable interfaces (APIs, idempotency, resume tokens), reason about tail latency and resource isolation, and communicate clear failure modes and mitigations a Software Engineer would implement.
Core knowledge
-
Streaming transport options — tradeoffs between
`WebSocket`, Server-Sent Events (SSE),HTTP/2+gRPCstreaming, and HTTP chunked responses; choose by bidirectionality, proxy compatibility, and browser support. -
Chunked transfer & framing — send discrete token/delta frames; include sequence numbers, content-type
application/json-seq, and explicit end-of-stream markers to enable reassembly and resume. -
Resume tokens & idempotency — attach a compact resume cursor or token with each frame so clients can reconnect and request "resume from offset X"; use server-side idempotency keys for request deduplication.
-
Backpressure & admission control — use token-bucket or leaky-bucket per-client rate limiting and global admission control; reject or queue requests when CPU/latency budgets exceed thresholds to protect
p99latency. -
Cancellation semantics — propagate client cancels immediately to compute layer; implement soft-cancel (stop token generation) and hard-cancel (kill compute) with timeout/window for graceful cleanup.
-
Stateless fronting with sticky state — keep frontends stateless relays but use sticky session routing or external session store (small
Redis) for ephemeral streaming metadata (resume tokens, partial buffers). -
Transient UI state model — represent in client as immutable message tree with in-progress flags and append-only token deltas; reconcile streams by id/seq to avoid flicker and duplicates.
-
Persistence model: snapshots & event log — store conversation as append-only event log plus periodic snapshots for reads; snapshotting at message boundaries speeds restores and sharing use-cases.
-
Consistency and concurrent updates — use optimistic concurrency control (CAS) for edits and snapshot writes; design for last-writer-wins or CRDT merge only if multi-author editing required.
-
Latency budgeting — set tight budgets: e.g., client RTT + server queueing + model compute ≤ target (e.g., 500ms for response start), monitor
p95/p99for throttling decisions; expose graceful degrade path (shorter summary instead of full generation). -
Monitoring & observability signals — instrument request lifecycle: enqueue time, start time, token emission rate, bytes streamed, cancellation rate, resume success rate; alert on rising resume/retry counts and
p99token gaps. -
Testing & determinism — add deterministic replay hooks and synthetic load tests that simulate partial-frame loss, reconnects, and slow clients; mock providers with configurable latency and tokenization.
Worked example — Build a Reliable Streaming Chat UI
First 30 seconds: clarify client constraints (browser vs native), expected throughput (users concurrently streaming), allowed transports (`WebSocket` vs SSE), and what “reliable” means (resume on reconnect, no duplicated tokens, consistent UI ordering). Skeleton answer pillars: (1) transport + framing (frame = {msg_id, seq, resume_token, delta}), (2) client state management (immutable message list with an in-progress entry and id/seq reconciliation), (3) resume & idempotency (server issues resume cursors and supports resume API), and (4) admission/backpressure (client-level rate-limits & server-side admission).
One tradeoff to flag: using `WebSocket` gives bidirectional control and built-in backpressure semantics in some stacks, but is harder to proxy and scale through certain load balancers—SSE is simpler but uni-directional. Implementation detail to call out: include sequence numbers and a server-signed resume token to avoid accepting stale resumes after conversation deletion. Close with next steps: if time remains, sketch tests (reconnect fuzzing), performance targets (p95 start latency), and how to instrument for out-of-order or missing frames.
A second angle — Design a Highly Available Conversational AI Service
This question emphasizes availability, regional isolation, and dependency failures. Apply the same streaming principles but shift focus to system-level resilience: front-door load shedding, multi-region routing, replica isolation, and graceful degradation. With streaming, you must plan admission control globally (reject to preserve p99 for existing streams), fall back to cached or summarised responses on dependency failure, and implement cross-region resume tokens so clients reconnect to nearest healthy region without redoing expensive compute. Also design per-tenant quotas and circuit breakers around an external LLM provider: if provider latency spikes, return a short canned reply or progress bar while preserving connection and allowing resume. The core primitives (framing, resume, cancellation, instrumentation) are identical, but you now prioritize isolation, capacity planning, and failover strategies.
Common pitfalls
Pitfall: assuming TCP backpressure is enough — TCP windows don't provide application-level flow control for tokenized JSON frames; you still need explicit rate or frame control and client-side buffering limits to avoid OOM or UI jank.
Pitfall: resuming by raw byte offset — resumes should be by logical token/sequence id with server validation; byte offsets break across different encodings, partial serialization, and middleware rewrites.
Pitfall: client optimistic UI that blindly appends streamed deltas without deduplication — this yields duplicated text after reconnects; reconcile on
msg_id+seqand keep an idempotency filter.
Connections
Interviewers may pivot to adjacent topics like model-serving orchestration (scaling inference backends, warm pools) or data consistency (event sourcing vs relational snapshots) — be prepared to discuss how streaming primitives interact with those systems, especially for admission control and snapshot durability.
Further reading
- Designing Data-Intensive Applications (Martin Kleppmann) — event logs, snapshots, and distributed consistency patterns for conversation stores.
Practice questions
Focus area — OpenAI-specific ML reliability and safety angle; emphasize evals, monitoring, rollouts, and inference debugging.
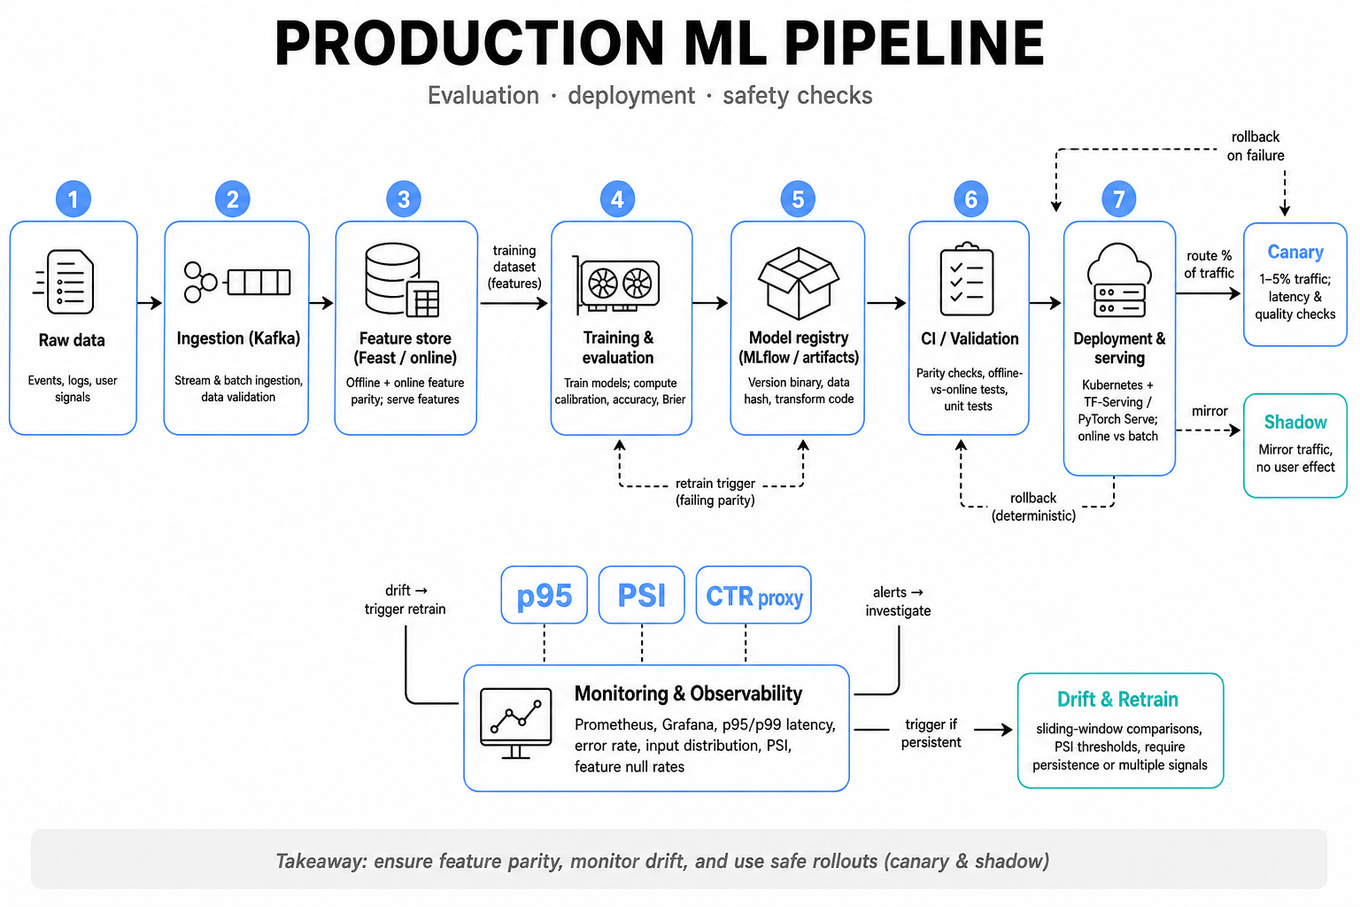
What's being tested
Candidates must show practical, systems-focused debugging and design skills for production ML: diagnosing pipeline and model failures, instrumenting reliable serving, and choosing safe rollout strategies. Interviewers probe the candidate’s ability to structure an investigation, read telemetry, and propose engineering fixes (retries, feature parity, canaries, rollbacks) rather than invent new ML algorithms.
Core knowledge
-
Data drift vs concept drift: know the difference—data distribution change (input features) vs label relationship change (P(y|x)); detect with population statistics, PSI, or simple KS tests on feature histograms.
-
Feature parity: ensure offline-features and online-features are computed identically; mismatches are a top cause of production failures. Reproduce feature pipelines locally before blaming the model.
-
Model versioning and lineage: use
MLflowor artifact stores to track model binary, training data hash, feature-transformation code, and config; make rollbacks deterministic by pinning all artifacts. -
Serving patterns: know the tradeoffs of online inference (low latency, strong consistency) vs batch/async (higher throughput, relaxed freshness). Implement with
Kubernetes+TensorFlow Serving/PyTorch Serveor a lightweight microservice. -
Canary & shadow deployment: route a small % of live traffic to a new model (canary) for latency/quality checks; mirror traffic to a new model with no user effect (shadow) to validate parity.
-
Monitoring & SLOs: instrument
p95/p99latency, error rate, and throughput; add model-specific telemetry: input distribution summaries, feature null rates, and top-10 features by contribution. Alert on threshold breaches. -
Model evaluation signals: track surface metrics (
accuracy,precision,recall) plus calibration (reliability diagrams, Brier score) and production proxies (CTR, downstream conversion) when labels are delayed. -
Drift detection and retraining triggers: use sliding-window comparisons, population-stability-index (PSI), or statistical change detectors; avoid retraining on transient spikes — require persistence or multiple signals.
-
Observability tools: integrate
Prometheusfor metrics,Grafanadashboards, structured logs for request/response, and distributed traces to correlate model latency with upstream/downstream services. -
Operational robustness: implement idempotent requests, graceful degradation (cached fallback model), circuit breakers, and exponential backoff for retriable failures; log inputs that hit fallbacks for analysis.
-
Privacy & safety guardrails: enforce input sanitization and rate limits, redact PII before logging, and add a pre-check to block toxic or out-of-distribution inputs.
Tip: capture a reproducible failing request (input, feature values, model version) so engineers can replay production behavior locally.
Worked example — Debug a failing ML classifier
Start by framing: ask what “failing” means (latency, accuracy drop, calibration drift, or increased false positives), when it started, rollout/versions, and whether labels are available in production. Organize the investigation into three pillars: (1) reproduce the failure locally (replay production requests), (2) inspect pipeline differences (feature-parity, preprocessing), and (3) inspect runtime signals (latency, memory, OOMs, infra errors). Triage steps: check recent deployments and config changes, verify feature histograms for top features against training distribution, and run the model binary on a sample of production inputs to compare predicted scores and confidences. A concrete tradeoff to call out: if retraining is easy, you can quick-retrain on recent data, but that risks reinforcing label bias—prefer validating drift and running a controlled canary retrain. Close by proposing short-term mitigations (canary rollback, serving fallback) and long-term fixes (add feature-parity tests, automated drift alerts, and reproducible replay pipelines), and say: “if I had more time, I’d add a shadow test harness and automated A/B quality gates with live labels.”
A second angle — Design a response-ranking ML system
Ranking introduces high-throughput, latency-critical serving and heavy instrumentation needs. The same debugging primitives apply: ensure feature parity between offline ranker training and online scorer, use shadowing to mirror traffic to new ranking models, and monitor both ranking-specific metrics (NDCG, CTR at k) and system SLOs. Unique constraints include candidate-generation latency (multi-stage pipelines), stateful session features, and the need for online batch scoring or pre-computed candidate scores. A software engineer must design efficient feature lookup (in-memory cache or Redis), ensure deterministic sort order under ties, and provide fast rollbacks because model mistakes directly affect user experience and revenue.
Common pitfalls
Pitfall: Blaming the model first.
Jumping to retrain without checking feature pipelines or infra issues wastes time. A better approach is to first reproduce requests end-to-end and confirm that the model gets the same inputs offline as online.
Pitfall: Relying solely on offline metrics.
Offline evaluation (e.g., cross-val accuracy) can miss production mismatches. Always correlate with production telemetry, shadow experiments, and delayed-label feedback loops.
Pitfall: Over-alerting on transient noise.
Triggering retrains or rollbacks on single spikes causes churn. Require multiple corroborating signals (persisting drift, label degradation, increased error rates) before automating heavyweight changes.
Connections
Interviewers may pivot to adjacent systems topics: feature stores and their consistency semantics, or deployment pipelines like CI/CD for models and canary automation. They might also ask about distributed tracing and SLO-driven incident response for ML services.
Further reading
-
Hidden Technical Debt in Machine Learning Systems — Sculley et al., NIPS 2015 — seminal paper on production ML failure modes and engineering debt.
-
Designing Data-Intensive Applications — Martin Kleppmann — practical reference for durable storage, stream processing, and system reliability patterns relevant to ML serving.
Practice questions
Coding & Algorithms
Focus area — Coding is 3/5 with views but no solved questions; serialization edge cases are common implementation-screen traps.
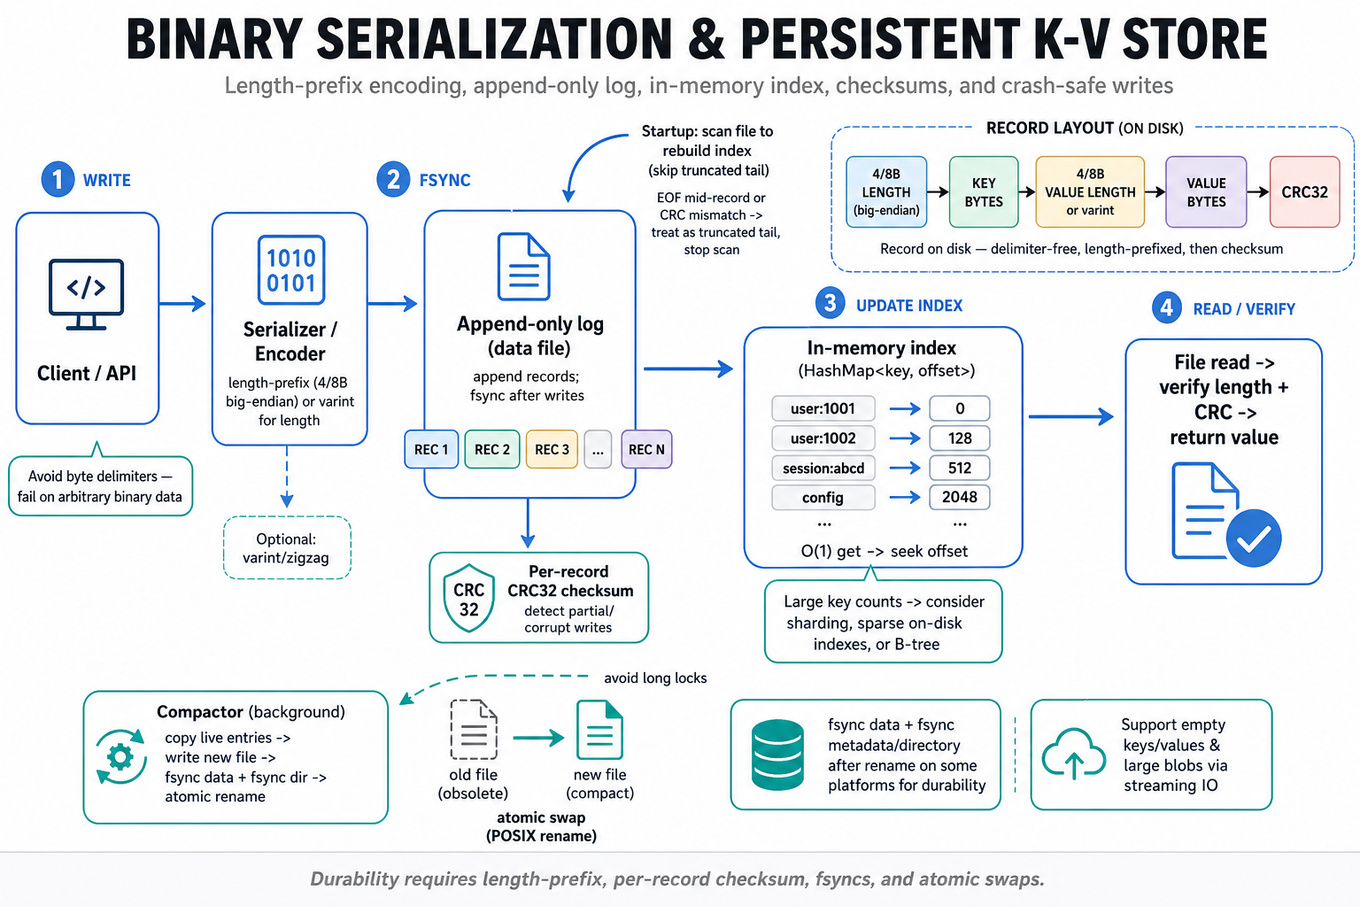
What's being tested
Demonstrates designing reversible, delimiter-free binary serialization and a crash-consistent persistent key-value store: encoding arbitrary bytes/Unicode, managing offsets/indexes, and safe disk writes. Interviewers probe correctness across edge cases, complexity reasoning, and simple durability guarantees.
Patterns & templates
-
Length-prefix encoding: store a fixed-width (e.g., 4- or 8-byte) big-endian length before bytes; decode by reading length then exact payload, O(n) serialize/deserialize.
-
Varint / zigzag for compact integer lengths: saves space for small values; implement decode loop carefully to avoid infinite loops.
-
Append-only log + in-memory index: append records to file, keep
HashMap<key, offset>for O(1) get; rebuild index by scanning on startup. -
Per-record checksum (e.g.,
CRC32) after payload to detect partial writes or corruption before using a record. -
Atomic replace pattern: write to temp file,
fsyncdata and metadata, thenrenameto swap files atomically on POSIX. -
Compaction/GC: background pass copies live entries to new file, then atomic swap; avoid holding long-lived locks during compaction.
-
Edge-size handling: support empty keys/values and very large blobs by streaming IO and limiting in-memory buffers.
Common pitfalls
Pitfall: Using a byte delimiter (e.g.,
\0) fails for arbitrary binary data — always prefer length-prefix or escape-free encodings.
Pitfall: Forgetting to
fsyncmetadata (fsyncon directory afterrenameon some platforms) breaks durability guarantees on crash.
Pitfall: Rebuilding index by naive memory structures without bounds can OOM on millions of keys — consider sharding, sparse indexes, or on-disk B-tree.
Practice these
the practice cards below cover the canonical variants — solve all of them and time yourself
Practice questions
You viewed coding content but have no solved evidence; practice snapshot semantics, but prioritize serialization and allocators first.
What's being tested
These problems test building a mutable directed graph that supports versioning and efficient snapshotting for point-in-time queries alongside live mutations. Interviewers probe data structures (per-edge logs, hash maps, balanced trees), algorithmic complexity for queries and updates, and memory/time tradeoffs when producing recommendations from historical graph state.
Patterns & templates
-
Per-edge event lists: store adds/removes as timestamped ops in sorted arrays; use
binary searchfor membership at version V, O(log m) per edge lookup. -
Immutable snapshots via copy-on-write: keep a root pointer to shared structures so snapshot creation is O(1) and mutations copy only changed nodes, amortized efficient for sparse updates.
-
Sparse version index / change logs: maintain
Map<version, root>or per-node change lists to replay until V; snapshot creation O(1), point-in-time rebuild cost depends on log length. -
In-memory adjacency map:
Map<node, Map<neighbor, List<(ts, op)>>>gives O(1) node access; watch memory for high-degree vertices and prefer compressed neighbor lists. -
Ordered containers for fast range queries: use
TreeMap/skiplist or arrays +bisectto find prefix/suffix of events in O(log n)+O(k) to scan k events. -
Recommendations via mutual intersections: iterate the smaller neighbor list and hash-count candidates, use a size-k heap for top-k, cost ~O(sum small_deg + m log k).
-
Compaction/checkpointing: checkpoint full adjacency at intervals and drop old deltas to bound read/replay cost; tune checkpoint frequency to update rate.
Common pitfalls
Pitfall: Treating unfollow as instantaneous deletion without a timestamp makes point-in-time queries ambiguous and yields wrong historical membership.
Pitfall: Assuming snapshot = deep copy; naive copies are O(N) and blow up memory — prefer structural sharing or periodic checkpoint+delta strategies.
Pitfall: Building recommendations by intersecting all neighbors (all-pairs) — this can be O(n^2) on heavy nodes; always iterate the smaller set or use sampling.
Practice these
The practice cards below cover the canonical variants — solve all of them and time yourself.
Practice questions
Onsite — 24 min
System Design
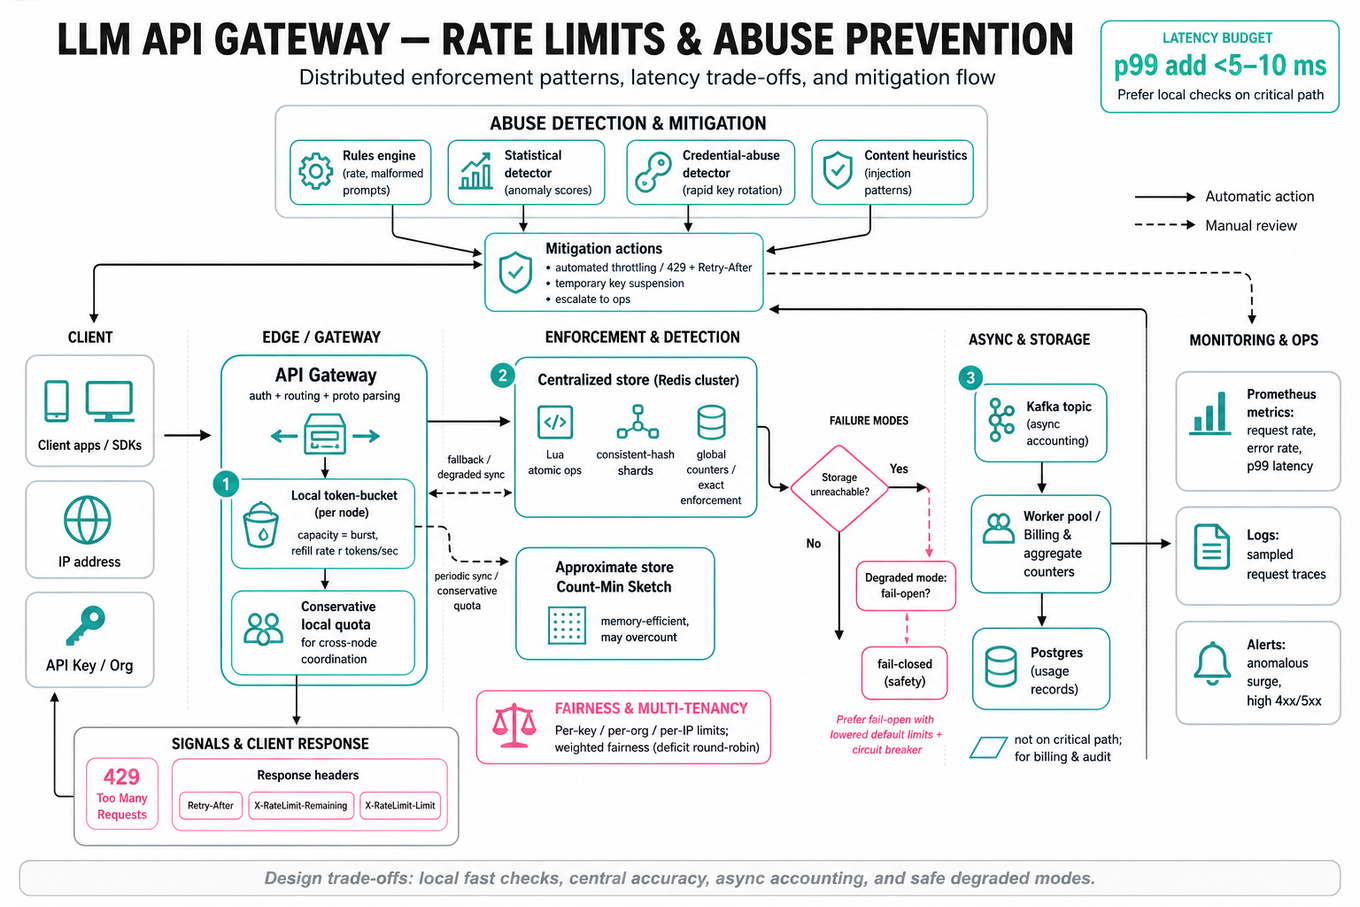
Focus area — New OpenAI API-facing layer: rate limits, abuse controls, auth, and metering connect product safety with scalable backend design.
What's being tested
Designing a robust API gateway that enforces scalable rate limits and defends against abuse requires balancing correctness, latency, and operational complexity. Interviewers probe your ability to pick and justify distributed enforcement strategies (consistency vs. availability), quantify capacity and burst behavior, and integrate detection/mitigation without blowing up latency or false positives. Expect to explain failure modes, instrumentation, and one or two concrete implementation sketches that could be built in a week.
Core knowledge
-
Rate-limiting primitives: understand fixed-window, sliding-window log, sliding-window counter, token-bucket, and leaky-bucket;
token-bucket: capacity = burst, refill ratertokens/sec, consumektokens per request. -
Tradeoffs: accuracy vs. latency: fixed-window is cheapest (O(1)) but produces spikes; sliding-window reduces spikes at higher storage cost; token-bucket supports bursts naturally.
-
Distributed enforcement patterns: centralized store (
Redis) with atomic ops (Lua scripts) for global counters, or local token-buckets per gateway node with periodic sync / conservative quotas for cross-node coordination. -
Sharding and scale: use consistent hashing to shard counters across a
Rediscluster; for approximate needs, use Count-Min Sketch to reduce memory at the cost of over-counting. -
Latency budget: putting enforcement on the critical path must meet SLOs (e.g., add <5–10ms); prefer local checks for
p99-sensitive paths and async accounting for billing. -
Fairness and multi-tenancy: support per-API-key, per-organization, per-IP limits, and weighted fairness (e.g., deficit round-robin) to prevent noisy neighbors.
-
Failure modes & resilience: decide fail-open (availability) vs fail-closed (safety); use degraded-mode heuristics (e.g., lower default limits) and circuit breakers to avoid cascading failures.
-
Backpressure & client signaling: return
429 Too Many RequestswithRetry-After, expose remaining-quota headers, and support soft-limits for graceful throttling. -
Abuse detection signals: behavioral (high request rate, repeated malformed prompts), credential abuse (rapid key rotation), and content heuristics (repeated injection patterns); combine rules + lightweight statistical detectors.
-
Mitigation tools: automated throttling, temporary key suspension, CAPTCHA or proof-of-work for unauthenticated flows, connection blackholing for verified abusers.
-
Operational metrics: track
p50/p95/p99latency, throttle rate, quota exhaustion rate, unique active keys, false-positive rate for abuse detection, and SLO burn. -
Clock and atomicity issues: avoid relying on client clocks; use monotonic server time and atomic operations (e.g.,
INCRBYwith expiry) to prevent race conditions and skewed bursts.
Worked example — "Design an LLM API Gateway that enforces per-customer rate limits and prevents prompt-injection abuse"
First 30s: clarify scope — are limits per API key, per account, per IP? Is enforcement global across regions? Are latency SLOs strict (p99 < X ms)? Are we blocking for safety or simply throttling? Skeleton: (1) edge gateway (Envoy/NGINX) enforces local token-bucket for low-latency checks, (2) centralized Redis rate-limiter for cross-node single source of truth (Lua script for atomicity), (3) light-weight content heuristics filter (regex/signature) plus async ML-based signal pipeline for deeper analysis. Key tradeoff: local buckets reduce latency but can allow slightly higher aggregate bursts; centralized enforcement is exact but adds cross-AZ latency—choose local-first with periodic reconciliation if p99 latency matters. Failures: on Redis outage prefer fail-open with reduced default quotas and increased logging, or fail-closed if safety-critical. Close by saying: with more time I’d prototype the Redis Lua scripts, write canary tests to measure p99 impact, and add a shadow-mode to tune abuse-detection thresholds.
A second angle — "Preventing abuse from distributed clients rotating API keys and IP addresses"
Here the attacker evades per-key/IP limits by rotating credentials. Emphasize device- or behavior-level signals: fingerprint request headers, TLS client hello fingerprints, rate-of-new-key-creation, and anomaly scoring aggregated per account. Architecturally, push detection into a streaming analytics pipeline (lightweight enrichment at the gateway, heavy scoring off-path) and apply rapid short-term mitigations (temporary global soft-throttle or proof-of-work) while the account’s historical risk score is computed. The tradeoff is privacy and false positives: more aggressive fingerprinting improves detection but raises privacy and operational complexity.
Common pitfalls
Pitfall: using fixed-window counters by default.
Fixed-window counters are attractive for simplicity but allow 2x bursts at window boundaries; interviewers will flag this. Show you know sliding or token-bucket alternatives and quantify burst behavior.
Pitfall: not clarifying quota semantics.
If you don't ask whether limits are per-key or per-org, the interviewer will test you with multi-API-key tenants. Always state assumptions about identity granularity and how shared quotas behave.
Pitfall: ignoring degraded-mode behavior and clock skew.
Designs that assume always-availableRedisor perfectly synchronized clocks break in outages; explain fail-open vs fail-closed choices and how monotonic server time + atomic ops (Lua) prevent race conditions.
Connections
Expect quick pivots to adjacent areas: authentication & authorization (how tokens/roles affect quota), observability & SLOs (how throttling counts against customer-visible SLOs), and distributed caching/consensus (how to shard and replicate counters consistently).
Further reading
-
Designing Data-Intensive Applications — M. Kleppmann — strong grounding on distributed consistency and storage tradeoffs.
-
Envoy Rate Limit Service docs — practical patterns for pushing policies into the gateway.
-
Redis-based rate limiting patterns (blog posts) — concrete examples of Lua-based atomic counters and token-bucket implementations.
Practice questions
Core infra topic across both rounds; keep steady practice since self-rating is 3/5 and platform solving evidence is absent.
What's being tested
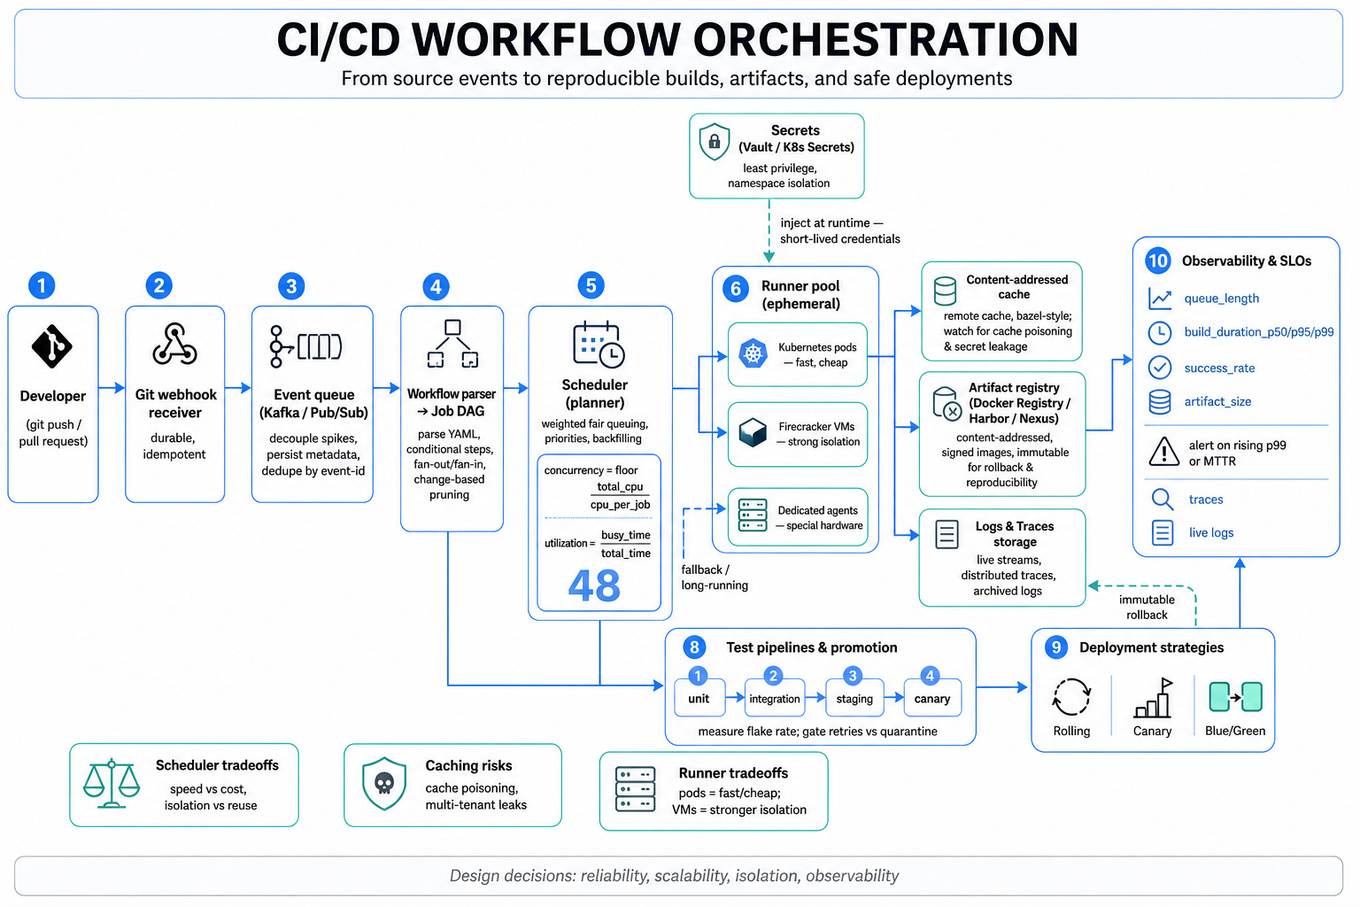
Candidates must show how to design a reliable, scalable CI/CD workflow orchestration system that turns source events into reproducible builds, tests, artifacts, and safe deployments. Interviewers probe architecture decomposition (ingest → planner/scheduler → runners → artifact & log storage), operational tradeoffs (speed vs cost, isolation vs reuse), and practical run-time concerns: scheduling policies, caching, observability, security, and rollback. Demonstrate concrete choices, capacity math, and failure-mode mitigation that a software engineer would own.
Core knowledge
-
Event intake: Git/webhook handling should be durable and idempotent; use a queue (
`Kafka`/Pub/Sub) to decouple spikes, deduplicate by event-id, and persist metadata for auditing and replay. -
Workflow parsing & DAG: Parse YAML into a job DAG; support conditional steps, fan-out/fan-in, and change-based pruning (skip downstream jobs if no affected files).
-
Scheduler & fairness: Scheduler implements priorities, weighted fair queuing, and backfilling; model capacity: concurrency = floor(total_cpu / cpu_per_job); utilization = busy_time/total_time.
-
Runners / isolation: Provide ephemeral runners via
`Kubernetes`pods, lightweight VMs (Firecracker), or dedicated agents; tradeoffs: pods = fast/cheap, VMs = stronger isolation. -
Caching & incremental builds: Use content-addressed caches (remote cache or
`bazel`-style) and artifact caching; beware cache poisoning and secret leakage between tenants. -
Artifact immutability and registries: Store artifacts in a content-addressed registry (
`Docker Registry`,`Harbor`,`Nexus`) and sign images; immutability simplifies rollbacks and reproducibility. -
Security & secrets: Inject secrets at runtime via
`Vault`/`Kubernetes`secrets with short-lived credentials; enforce least privilege and runtime namespace isolation. -
Testing layers & flakiness: Compose unit → integration → staging → canary; quantify flakiness (test flake rate) and gate retries vs quarantine to avoid wasting resources.
-
Observability & SLOs: Emit metrics: queue_length, build_duration_p50/p95/p99, success_rate, artifact_size; logs streamed live, distributed traces for long DAGs, alerts for rising p99 latency or MTTR.
-
Deployment strategies: Implement rolling, canary, and blue/green deployments plus feature-flag integration; ensure idempotent deployment APIs and immutable artifact references.
-
Multi-tenant constraints: Enforce per-tenant quotas, RBAC, logs/artifact scoping, and fair-share scheduling to prevent noisy neighbors; include admission control on resource consumption.
-
Cost & capacity planning: Estimate cost_per_build = CPU_seconds * price_cpu + storage_gb * price_storage + egress; shard scheduler when builds/day > ~10k or concurrency >> cluster size.
Tip: Prefer content-addressed artifact IDs and immutable tags; they make rollbacks and cache reuse deterministic.
Worked example — "Design a CI/CD pipeline with scheduler"
First 30s: clarify scope (single repo vs monorepo? polyglot builds?), SLOs (p95 build latency target), and scale (builds/day, avg duration, concurrency). State assumptions: monorepo, target ~500 builds/day, average 5min build, multi-stage tests.
Skeleton pillars to present:
-
Event ingestion: Git webhooks → validated → enqueue in
`Kafka`with dedupe. -
Workflow planner: YAML → DAG; compute affected tasks with file-change graph to skip irrelevant jobs.
-
Scheduler: global scheduler implements priority, backfilling, and slot accounting (CPU/memory/GPU). Maintain per-project quotas and tenant weights.
-
Runners & execution: ephemeral
`Kubernetes`pods using a sidecar for log streaming and secret injection; cache mounts from remote cache. -
Artifacts & deploy: push content-addressed artifacts to
`Harbor`, sign, then trigger deployment pipeline with canary rollout and automated rollback on health regression.
One tradeoff to flag: shared runner pools maximize utilization but require rigorous sandboxing and secret handling; dedicated runners increase latency and cost but give stronger isolation. Close by saying: if I had more time, I'd prototype scheduler policies with a load simulator, add ML-based prioritization for critical PRs, and detail quorum-based rollout health checks.
A second angle — "Design multi-tenant CI/CD workflow system"
Multi-tenancy shifts priorities: tenant isolation and fairness become first-class. Start by scoping isolation boundaries (logical via namespaces vs physical via clusters). Scheduler must enforce per-tenant quotas, weighted priorities, and admission control; consider hierarchical scheduling (global broker + per-tenant local scheduler) to scale. Artifact and log stores must be multi-tenanted with ACLs and encryption-at-rest; billing meters resource usage (CPU_seconds, storage_gb). Also design for noisy-neighbor mitigation: throttling, preemption, and per-tenant reservation pools.
Common pitfalls
Pitfall: Focusing only on fast median builds (p50) and ignoring p99 latency — this leads to bad SLOs; always present p50/p95/p99 and tail-case mitigation like pre-warmed runners.
Pitfall: Proposing naive shared caches without considering security and cache poisoning; articulate cache scoping and validation (content-addressed + signed artifacts).
Pitfall: Treating scheduling purely as FIFO; interviewers expect tradeoffs between fairness, priority, and cost — describe algorithms (weighted fair queuing, backfill) and capacity math.
Connections
Design conversations often pivot to distributed schedulers, observability/alerting (SRE practices), and build-system internals (remote execution, `bazel` caching). Be ready to dive into runtime security (sandboxing, attestation) or cost-optimization (spot instances, preemptible runners).
Further reading
-
Argo Workflows — practical model for
`Kubernetes`-native DAG execution and workflow controller. -
Tekton Pipelines — a vendor-neutral CI/CD primitives project with pipeline-as-
`Kubernetes`-CRDs, useful for scheduler/running patterns.
Practice questions
Relevant to secure multi-tenant infrastructure; review isolation and lifecycle management without over-allocating time.
What's being tested
Candidates must design a multi-tenant, secure, and scalable cloud development environment that balances isolation guarantees, fast developer experience, durable state, and operational cost. Interviewers probe distributed-systems design (scheduling, autoscaling, persistence), runtime sandboxing choices (container vs. microVM vs. VM), networking/security controls (egress/no-egress, RBAC), and observable lifecycle and failure modes. Expect to defend tradeoffs (density vs. safety, cold-start latency vs. resource utilization) with concrete implementation choices.
Core knowledge
-
Isolation model: understand namespaces (PID, MNT, NET), cgroups, and the difference between process-level containers and hardware-virtualized microVMs for attack-surface reduction and kernel-escape risk.
-
Sandbox runtimes: trade
containerd/Docker +gVisor(user-space kernel) vsFirecracker(microVM) vs full VMs (qemu) — density, startup time, surface area, and required kernel features differ. -
Orchestration & scheduling: know
Kubernetespod scheduling, custom schedulers, bin-packing heuristics (first-fit-decreasing), and node affinity/taints for isolating sensitive workloads. -
Ephemeral vs persistent storage: use ephemeral local SSDs for fast compile/cache; durable state via network object storage (
S3-compatible) or block PVs (CSI) with snapshot/versioning for workspace persistence and fast restore. -
Snapshotting & image layering: store base images + user overlay using union filesystems (OverlayFS) or layered container images; snapshot restore time ≈ download bandwidth + mount cost — optimize via shared base layers and lazy fetching.
-
Networking & security controls: apply network policy (CNI plugins like
Calico), per-workspace egress whitelists, per-tenant VPCs, and programmable proxies for logging/mitigation of outbound traffic. -
Authentication & RBAC: map short-lived credentials (OAuth, OIDC) to workspace tokens, implement fine-grained RBAC and ephemeral SSH/port tunneling; rotate keys frequently and enforce least privilege.
-
Hot-reconnect & session continuity: stream editor state over
WebSocket/gRPCand persist terminal output to replay logs; implement checkpointing to allow reconnect within seconds. -
Autoscaling and cost model: autoscale by queue depth and per-workspace metrics (CPU, memory, I/O); compute cost per workspace ≈ (vCPU-hours * vCPU-price) + (GB-month * storage-price); set thresholds to prefer suspend/snapshot for idle > T_idle.
-
Cold-start vs warm-pool tradeoff: keep warm pool size W to target
p90start latency L_target: P(start latency ≤ L_target) ≈ 1 - e^{-λW} for Poisson arrivals, tune W against cost of idle resources. -
Observability & SLOs: collect
p95start time, reconnection latency, storage restore time, resource-usage per-tenant, and security audit logs; usePrometheus+Grafana; ship structured logs to long-term store. -
Operational limits & multi-tenancy: partition tenants by quota (CPU, memory, storage) and by node-pools for noisy-neighbor isolation; enforce secure defaults and resource request/limit enforcement in the runtime.
Worked example — Design a sandboxed cloud IDE
First 30 seconds: ask about expected concurrency (typical and peak), required persistence semantics (durable home dir vs ephemeral), security level (untrusted code?), and allowed network egress. Skeleton answer pillars: (1) runtime isolation (choose microVMs Firecracker for untrusted code, containers + gVisor for trusted tenants for higher density), (2) lifecycle & orchestration (use Kubernetes with a custom controller that provisions workspace images and manages warm pools), (3) storage & snapshotting (shared base images + per-user overlay on S3 with block PV for hot caches), (4) networking & RBAC (per-workspace network policies, ephemeral credentials), (5) observability & autoscaling (track start latency, idle metrics, warm-pool sizing). Explicit tradeoff: choosing microVMs gives stronger isolation but ~2–10x higher resource cost and slower cold starts; containers improve density but require stronger kernel-hardening and runtime sandboxing. Close with: if more time, detail eviction strategy for long-idle workspaces, CI integration, and experiments to tune warm-pool size by arrival-rate telemetry.
A second angle — Design a Cloud DevBox Platform
For longer-lived DevBoxes, emphasize durable user customization and higher-weight persistence guarantees: provide custom images, pre-installed packages, and per-user secrets management. Shift architecture toward image builder pipelines, immutable image registries, and incremental snapshot storage to allow fast restore of entire environment. Operationally, add quota-based billing, retention policies, and RBAC for shared team-devboxes. The scheduling focus becomes placement for disk-heavy boxes (local SSD binding) and ensuring backups/snapshots have RPO/RTO SLAs; security pivots to secret injection and auditability rather than purely runtime escape prevention.
Common pitfalls
Pitfall: Underestimating kernel attack surface — choosing plain containers without user-space sandboxing or seccomp filters can leave the system vulnerable to container-to-host escapes; prefer
gVisor/microVMs for untrusted code paths.
Not asking about persistence semantics is a communication mistake: many candidates design ephemeral-only systems; interviewers often expect clarifying whether "workspace state" includes dotfiles, installed packages, databases, or only source files, since each choice changes storage and snapshot design.
Pitfall: Over-optimizing for density without amortizing cold-start cost — packing maximum containers per node increases cold-start latency and noisy neighbors; show measurement-driven warm-pool sizing and prefetch strategies instead.
Failing to describe observability and SLOs is a depth mistake: don't claim "it will be fast" — define metrics (p95 start time, reconnection time), alert thresholds, and how they map to autoscaler triggers and incident responses.
Connections
Interviewers can easily pivot to adjacent systems: remote CI/CD runners and build caches (same scheduling and sandboxing tradeoffs), or secure multi-tenant compute for model serving (similar egress controls and auditing). Be ready to discuss how workspace snapshots integrate with backup/restore and image-building pipelines.
Further reading
-
Firecracker: Lightweight Virtualization for Serverless Workloads — explains microVM tradeoffs and startup characteristics.
-
gVisor Overview (Google) — details user-space kernel sandboxing for container workloads.
-
Gitpod Architecture Blog — practical reference architecture for cloud IDEs (image layering, persistence, and orchestration).
Practice questions